Measuring How Fast Your IIoT Queries Are Degrading
Stop waiting for the dashboard to get slow. Record latency against row count, fit the curve, and get a date when your query breaches its target.
By John Shi
October 9th, 2026

By Raja Rao DV
February 9th, 2026
9 min
Search is one of those problems that’s deceptively hard. You think you can just LIKE '%query%' your way through it, and then you spend three months learning why that doesn’t work.
Here’s the problem: sometimes users search with exact keywords like “PostgreSQL error 23505”. Other times they search with the meaning: “why is my database slow”. Most of the time, it’s somewhere in between.
Documents are the same way. Some are full of specific terms and jargon. Others are conversational and conceptual. Most are a mix of both.
So you have queries that could be keywords or meaning, hitting documents that could be keywords or meaning. That’s four combinations:
Document has Keywords | Document has Meaning | |
Query has Keywords | ✅ BM25 nails it | ❌ BM25 misses it |
Query has Meaning | ❌ Vectors miss it | ✅ Vectors nail it |
No single approach covers all four quadrants. You need both keyword search AND vector search. And you need a way to combine them intelligently.
That’s exactly what Elasticsearch does. It uses BM25 for keyword ranking, vector embeddings for semantic search, and RRF (Reciprocal Rank Fusion) to merge the results into a single ranked list. This combination is called hybrid search, and it’s why Elasticsearch actually works.
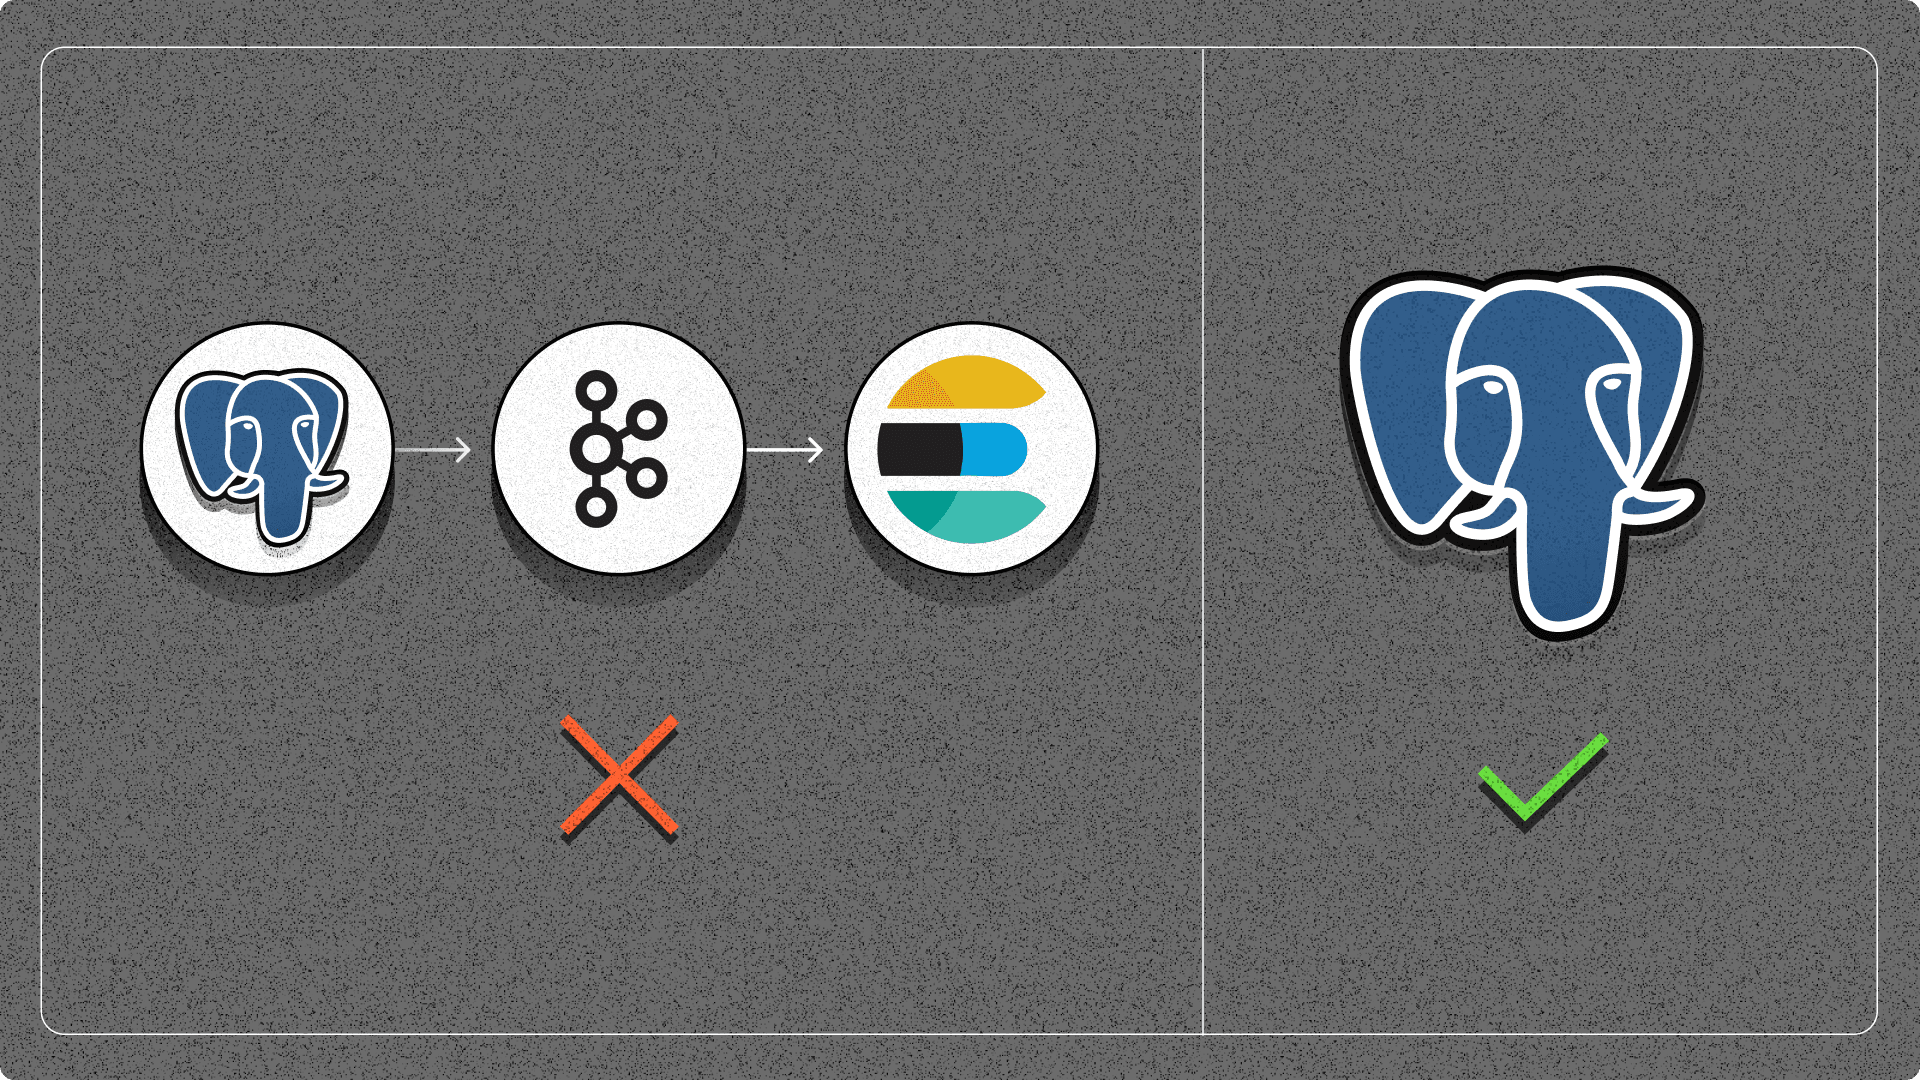
But here’s the trade-off: to use Elasticsearch, you need to build a pipeline. Your data lives in Postgres, but search lives in Elasticsearch. So you’re stuck with:
Postgres → Kafka/Debezium → ElasticsearchThat’s three systems to manage. Three things that can break. Sync jobs to maintain. Stale data to debug. And with AI agents now needing to search through docs and codebases on the fly, the pipeline problem is getting worse. You can’t easily spin up a test environment when your search lives in a completely different system.
Still, teams pay for it. Over a billion dollars a year, collectively. Because search that works is worth the pain.
Here’s the good news: all three pieces of Elasticsearch’s hybrid search are now available in Postgres:
And pgai eliminates the embedding pipeline entirely (no more Postgres → Kafka → Elasticsearch sync jobs). It automatically syncs changes to the data and updates the corresponding embeddings appropriately.
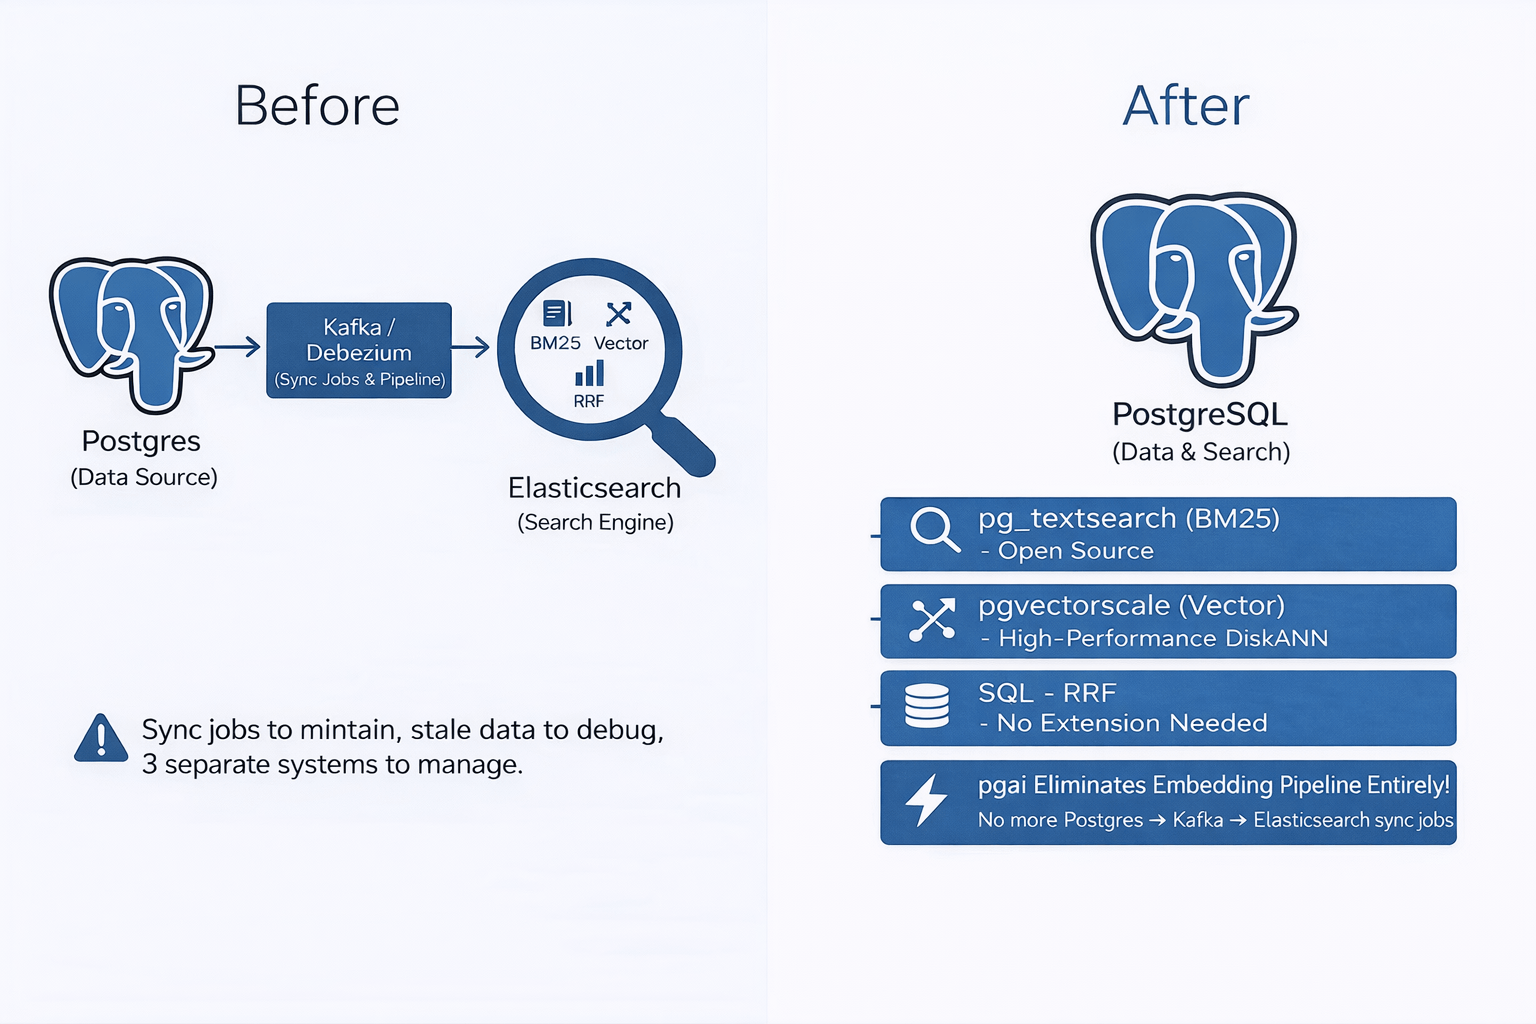
We’ve already covered how BM25 works. This blog focuses on Hybrid Search, RRF, pgai, how they all work together, why it’s elegant, and how to implement hybrid search entirely in Postgres.
RRF (Reciprocal Rank Fusion) is elegantly simple. It’s the industry standard for combining ranked lists, and it’s what Elasticsearch uses for hybrid search.
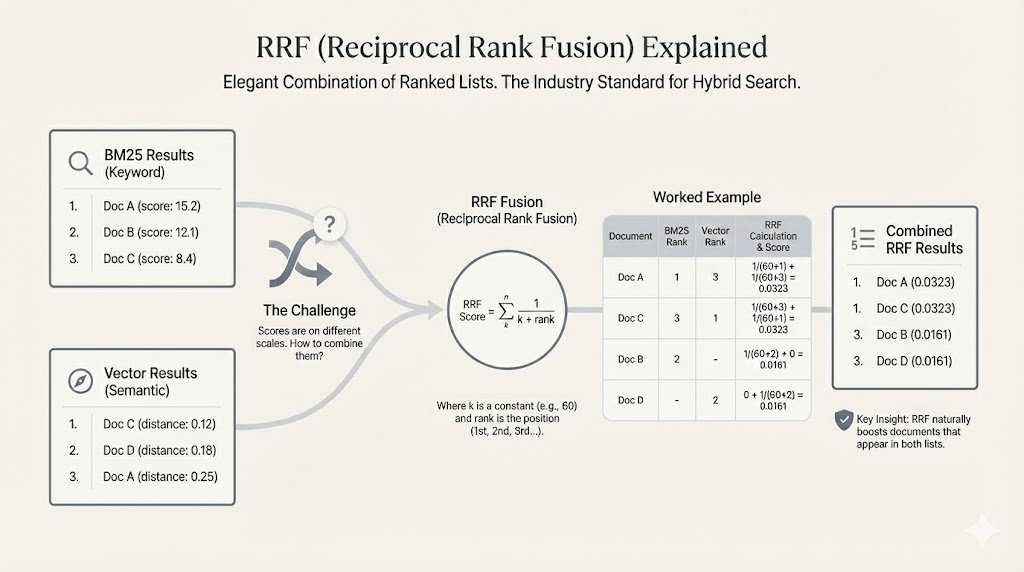
You run two searches and get two ranked lists:
BM25 Results (keyword): 1. Doc A (score: 15.2) 2. Doc B (score: 12.1) 3. Doc C (score: 8.4)
Vector Results (semantic): 1. Doc C (distance: 0.12) 2. Doc D (distance: 0.18) 3. Doc A (distance: 0.25)
How do you combine them? You can’t just add the scores. They’re on completely different scales. BM25 scores might be 0-50. Vector distances are 0-2.
RRF ignores the actual scores. It only cares about rank position:
RRF_score = Σ (1 / (k + rank))Where:
k is a constant (typically 60) rank is the position (1st, 2nd, 3rd…)That’s it. Dead simple.
Let’s calculate RRF scores for our documents:
Document | BM25 Rank | Vector Rank | Calculation | RRF Score |
Doc A | 1 | 3 | 1/(60+1) + 1/(60+3) | 0.0323 |
Doc C | 3 | 1 | 1/(60+3) + 1/(60+1) | 0.0323 |
Doc B | 2 | - | 1/(60+2) + 0 | 0.0161 |
Doc D | - | 2 | 0 + 1/(60+2) | 0.0161 |
Result: Doc A and Doc C tie for first place. Why? Because they appeared in both lists. RRF naturally boosts documents that multiple systems agree on.
Here’s how to implement hybrid search with RRF using pg_textsearch and pgvectorscale.
-- Enable extensions
CREATE EXTENSION pg_textsearch;       -- Adds BM25 ranking for keyword search
CREATE EXTENSION vectorscale CASCADE; -- Adds DiskANN for fast vector search (includes pgvector)
CREATE EXTENSION ai;                  -- Adds auto-embedding generation (optional but recommended)

-- Create your table
CREATE TABLE documents (
  id SERIAL PRIMARY KEY,
  title TEXT,
  content TEXT,                       -- This column gets BM25 indexed
  embedding vector(1536)              -- This column stores OpenAI embeddings (1536 dimensions)
);

-- Create indexes
CREATE INDEX idx_bm25 ON documents
  USING bm25(content)                 -- BM25 index on content column
  WITH (text_config = 'english');     -- Use English stemming/stopwords

CREATE INDEX idx_vector ON documents
USING diskann(embedding); -- DiskANN index for fast approximate nearest neighborWITH
-- STEP 1: Get top 20 keyword matches using BM25
bm25_results AS (
SELECT
id,
ROW_NUMBER() OVER (
ORDER BY content <@> to_bm25query('database optimization', 'idx_bm25')
) as rank -- Assign rank 1, 2, 3... based on BM25 score
FROM documents
ORDER BY content <@> to_bm25query('database optimization', 'idx_bm25')
LIMIT 20 -- Only keep top 20 keyword matches
),
-- STEP 2: Get top 20 semantic matches using vector similarity
vector_results AS (
SELECT
id,
ROW_NUMBER() OVER (
ORDER BY embedding <=> $1 -- $1 is the query embedding (passed from app)
) as rank -- Assign rank 1, 2, 3... based on vector distance
FROM documents
ORDER BY embedding <=> $1 -- <=> is cosine distance operator
LIMIT 20 -- Only keep top 20 semantic matches
)
-- STEP 3: Combine both lists using RRF formula
SELECT
d.id,
d.title,
d.content,
-- RRF: 1/(k+rank) for each list, summed together
-- k=60 prevents top results from dominating
COALESCE(1.0 / (60 + b.rank), 0) + -- Score from BM25 (0 if not in BM25 results)
COALESCE(1.0 / (60 + v.rank), 0) -- Score from vectors (0 if not in vector results)
as rrf_score
FROM documents d
LEFT JOIN bm25_results b ON d.id = b.id -- Join BM25 ranks
LEFT JOIN vector_results v ON d.id = v.id -- Join vector ranks
WHERE b.id IS NOT NULL OR v.id IS NOT NULL -- Must appear in at least one list
ORDER BY rrf_score DESC -- Highest RRF score = most relevant
LIMIT 10; -- Return top 10 resultsJust one query, two search types, but RRF smooths everything over. This makes your life super simple. What's better? Wrap it into a function called hybrid_search and then you can now call that function.
-- Reusable function: call hybrid_search('your query', $embedding, 10)
CREATE OR REPLACE FUNCTION hybrid_search(
  query_text TEXT,                    -- The search query (for BM25)
  query_embedding vector(1536),       -- The query embedding (for vectors)
  match_count INT DEFAULT 10          -- How many results to return
)
RETURNS TABLE (id INT, title TEXT, content TEXT, rrf_score FLOAT)
AS $$
  WITH
  -- BM25 keyword search
  bm25_results AS (
    SELECT id, ROW_NUMBER() OVER (
      ORDER BY content <@> to_bm25query(query_text, 'idx_bm25')
    ) as rank
    FROM documents
    ORDER BY content <@> to_bm25query(query_text, 'idx_bm25')
    LIMIT 20
  ),
  -- Vector semantic search
  vector_results AS (
    SELECT id, ROW_NUMBER() OVER (
      ORDER BY embedding <=> query_embedding
    ) as rank
    FROM documents
    ORDER BY embedding <=> query_embedding
    LIMIT 20
  )
  -- Combine with RRF
  SELECT
    d.id, d.title, d.content,
    COALESCE(1.0 / (60 + b.rank), 0) +
    COALESCE(1.0 / (60 + v.rank), 0) as rrf_score
  FROM documents d
  LEFT JOIN bm25_results b ON d.id = b.id
  LEFT JOIN vector_results v ON d.id = v.id
  WHERE b.id IS NOT NULL OR v.id IS NOT NULL
  ORDER BY rrf_score DESC
  LIMIT match_count;
$$ LANGUAGE SQL;
Now your app code is just:
SELECT * FROM hybrid_search('database optimization', $embedding, 10);Sometimes you want to favor one search type over the other. Technical docs might benefit from stronger keyword matching. Conversational queries might need more semantic weight. So you can expose all the weights in your function, and then you can call this weighted function.
-- Weighted version: control how much keyword vs semantic matters
CREATE OR REPLACE FUNCTION weighted_hybrid_search(
  query_text TEXT,                    -- The search query (for BM25)
  query_embedding vector(1536),       -- The query embedding (for vectors)
  bm25_weight FLOAT DEFAULT 0.5,      -- Weight for keyword search (0.0 to 1.0)
  vector_weight FLOAT DEFAULT 0.5,    -- Weight for semantic search (0.0 to 1.0)
  match_count INT DEFAULT 10          -- How many results to return
)
RETURNS TABLE (id INT, title TEXT, content TEXT, rrf_score FLOAT)
AS $$
  WITH
  -- BM25 keyword search
  bm25_results AS (
    SELECT id, ROW_NUMBER() OVER (
      ORDER BY content <@> to_bm25query(query_text, 'idx_bm25')
    ) as rank
    FROM documents
    ORDER BY content <@> to_bm25query(query_text, 'idx_bm25')
    LIMIT 20
  ),
  -- Vector semantic search
  vector_results AS (
    SELECT id, ROW_NUMBER() OVER (
      ORDER BY embedding <=> query_embedding
    ) as rank
    FROM documents
    ORDER BY embedding <=> query_embedding
    LIMIT 20
  )
  SELECT
    d.id, d.title, d.content,
    -- Weighted RRF: multiply each score by its weight
    (bm25_weight * COALESCE(1.0 / (60 + b.rank), 0)) +   -- Weighted BM25 score
    (vector_weight * COALESCE(1.0 / (60 + v.rank), 0))   -- Weighted vector score
    as rrf_score
  FROM documents d
  LEFT JOIN bm25_results b ON d.id = b.id
  LEFT JOIN vector_results v ON d.id = v.id
  WHERE b.id IS NOT NULL OR v.id IS NOT NULL
  ORDER BY rrf_score DESC
  LIMIT match_count;
$$ LANGUAGE SQL;
Usage:
-- Equal weight (default): 50% keywords, 50% semantic
SELECT * FROM weighted_hybrid_search('database optimization', $embedding);

-- Favor keywords (70% BM25, 30% vectors)
-- Good for: error codes, specific terms, exact phrases
SELECT * FROM weighted_hybrid_search('error 23505', $embedding, 0.7, 0.3);

-- Favor semantic (30% BM25, 70% vectors)
-- Good for: natural language questions, conceptual queries
SELECT * FROM weighted_hybrid_search('how do I make queries faster', $embedding, 0.3, 0.7);Remember the pipeline problem from the intro? Postgres → Kafka → Elasticsearch, with separate jobs to generate embeddings?
pgai eliminates pretty much all of that.
When you create a vectorizer, pgai sets up background workers that monitor your table for changes. When a row is inserted or updated, pgai automatically:
1. Detects the change
2. Calls the embedding API (OpenAI, Cohere, or local models)
3. Stores the embedding in a linked table 4. Keeps everything in sync
-- Set up automatic embedding generation
SELECT ai.create_vectorizer(
  'documents'::regclass,              -- Which table to watch for changes
  loading => ai.loading_column(
    column_name => 'content'          -- Which column to generate embeddings from
  ),
  embedding => ai.embedding_openai(
    model => 'text-embedding-3-small', -- OpenAI model to use
    dimensions => '1536'               -- Output embedding dimensions
  )
);
-- That's it! pgai now watches 'documents' and auto-generates embeddings
-- whenever content changes. No cron jobs. No sync scripts.
That’s it. Now any change to the documents table triggers automatic embedding updates:
- INSERT into documents → embedding generated for content column
- UPDATE the content column → embedding regenerated
- DELETE from documents → embedding removed
Embeddings are stored in a linked table (documents_embedding) that pgai creates and manages for you.
Note: On Tiger Data, the vectorizer worker runs automatically as a managed service. If you’re self-hosting, you’ll need to run the pgai vectorizer worker (a Python CLI) to process the embedding queue.
No Kafka. No Debezium. No sync jobs. No “why is my search stale?” debugging sessions at 3 AM.
Your embeddings live next to your data, updated in near real-time, managed by Postgres itself. This is what makes hybrid search in Postgres practical for production.
Everything you need is available on Tiger Data:
-- 1. Enable extensions (one-time setup)
CREATE EXTENSION pg_textsearch;        -- BM25 keyword search
CREATE EXTENSION vectorscale CASCADE;  -- Vector search (includes pgvector)

-- 2. Create indexes on your table
CREATE INDEX idx_bm25 ON documents USING bm25(content)
  WITH (text_config = 'english');      -- BM25 index with English stemming
CREATE INDEX idx_vector ON documents
  USING diskann(embedding);            -- Fast vector similarity index

-- 3. Search! (using the hybrid_search function from this post)
SELECT * FROM hybrid_search('your query', $embedding, 10);Elasticsearch built a billion-dollar business on BM25 and RRF. Those algorithms aren’t proprietary. They’re not even complicated. And now they run natively in Postgres.
No pipelines. No sync jobs. No extra infrastructure. Just your database doing what databases should do: storing your data and making it searchable.
The question isn’t whether Postgres can do hybrid search. It can. The question is: why are you still running two systems when one will do?
Our Posts:
Extensions:
Background:
Get Started:
// Related posts
Stop waiting for the dashboard to get slow. Record latency against row count, fit the curve, and get a date when your query breaches its target.
By John Shi
October 9th, 2026
A 20-byte sensor reading costs 95.6 on disk. Measure bytes per row, project 631 billion rows, and test your ingest ceiling before the schema review.
By John Shi
September 25th, 2026
Composite indexes charge every insert and pay back only some queries. Four steps to price both sides and audit the indexes you already run.
By John Shi
September 18th, 2026
Receive the latest technical articles and release notes in your inbox.