This is an installment of our “Community Member Spotlight” series, in which we invite our customers to share their work, spotlight their success, and inspire others with new ways to use technology to solve problems.
In this edition, Danny Burrows, Vice President of Software Engineering at Flogistix by Flowco, an Oil & Gas vapor recovery business, shares how Tiger Data improved performance while drastically cutting costs for their sensor data collections and real-time analytics.
About the Company & Team
I’m Danny Burrows, Vice President of Software Engineering and Data Intelligence at Flogistix by Flowco. Flogistix is an Oil & Gas field service company focused on vapor recovery. We maximize well performance by capturing and processing fugitive emissions and turning those into usable substrates to prevent damaging gases entering into the atmosphere, primarily with the use of data.
What that means in practice is that we design, build, manufacture and maintain a large fleet of compression equipment across U.S. oil and gas fields. Our equipment packages weigh from 8,000 pounds to 250,000 pounds operating in remote locations. My team supports ~250 field technicians and a fleet that’s grown to roughly 3,700 pieces of equipment. We ingest operational metrics continuously, approximately 100 data points every minute for the entire fleet, and then turn those data points into decisions that keep equipment healthy, production efficient, and crews safe.
The Challenge of Siloed OT/IT data
Before Tiger Data, our data layer couldn’t keep up with how we operate:
Fractured set of technologies: Multiple systems for ingest, storage, and “cooling off” of data without a coherent integration strategy to manage the 250-275 GB of data ingested daily, in addition to challenges around data classification and data storage requirements to keep the data performant.
Limited expertise on fine-tuning performance: Systems implemented on top of NoSQL databases made optimizing ingestion/query performance difficult.
Lagging regulatory follow-ups: No flexible, fast access to the historical operations and equipment data that customer SLAs demanded for environmental compliance to prevent government fines and well site shutdowns.
Delayed field service insights: We couldn’t respond quickly to answer live questions from field technicians seeking answers to diagnose equipment problems in remote, harsh conditions.
Exponential growth in data: Year-over-year growth of data in assets had pushed the existing system to its limits, as we now managed approximately 140 million records in production, with around 500 GB of data storage.
Edge constraints: Spotty cellular data coverage in oil fields resulted in data that couldn’t be packaged appropriately for efficient field service use.
We needed a system our team could run with existing skills, that scaled for time-series data, exceeded our customer SLAs, and provided field technicians with operational and historical data insights on the fly.
The Solution: Tiger Data’s Purpose-Built Performant Time-Series Postgres
Powered by TimescaleDB on AWS, Tiger Cloud runs on Amazon EC2 with S3 tiered data storage.
Our evaluation criteria for our existing tech stack replacements were simple and non-negotiable: data rolloff, aggregations, and compression. We needed clean data rolloff from hot to cool to cold so operations could understand current state instantly while longer-horizon reporting tolerated looser SLAs. We also had to package results and cut down on the noise: nobody wants minute-by-minute plots over six months, and we weren’t about to stream that volume over HTTP to the front-end, so both precomputed and on-the-fly summaries were essential. And with the sheer quantity of telemetry we ingest, compression had to keep storage lean without hurting query performance.
In short: speed, performance, and cost, delivered through rolloff policies, smart aggregations, and aggressive compression.
Based on our evaluation criteria, Tiger Data uniquely fit the bill:
Familiar managed PostgreSQL: App teams are familiar with SQL and Postgres. We didn’t want a special-purpose database with bespoke languages and syntax the team would have to learn.
Purpose-built time-series features: Tiger Data’s hypertables, native compression, and incremental materialized views, called continuous aggregates (CAGGs), let us decouple raw ingest from downsampled views used by dashboards and analytics.
Operational pragmatism: Automatic tiering to keep hot data fast and cold data cheap which Tiger Data offered as part of their S3 tiered storage, along with read replicas for scale.
Flogistix by Flowco’s Simplified Sensor Ingestion Workflow
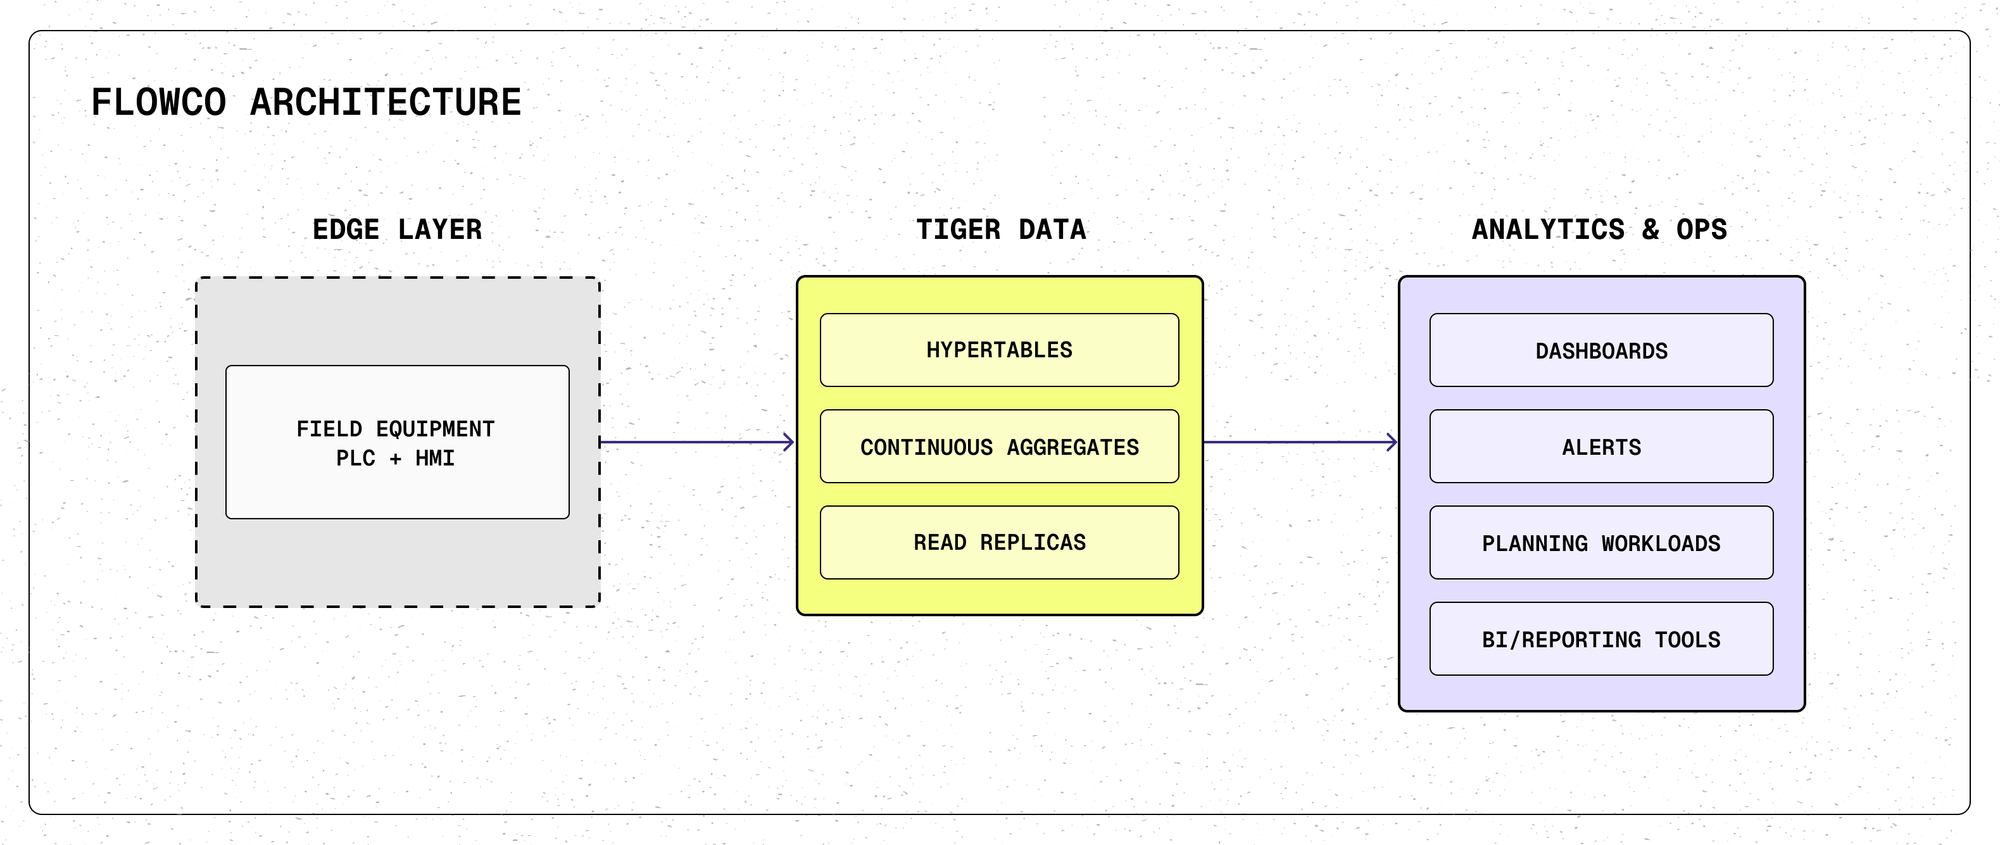
Here’s the high-level flow we implemented to keep the edge resilient and the cloud fast, with minimal operational overhead. It’s designed to buffer through spotty connectivity, compress and summarize efficiently, and isolate analytics from real-time ingest so dashboards stay responsive as the fleet scales.
IoT data from the edge comes in from both Docker runtimes as well as traditional PLC and HMI controls.
Ingest into Tiger Data Hypertables with compression on both hypertables and CAGGs.
Continuous Aggregates for rolling 1-minute, 5-minute, and hourly summaries to power dashboards, alerts, and planning workloads.
Read replica for BI/reporting, keeping production ingest isolated.
“We needed automatic data tiering, high compression, and edge-first logging so we weren’t waking a fleet of servers every minute. Tiger Data let us run locally in a lightweight Docker setup, log data at the edge, then push to the cloud.” - Danny Burrows, VP of Software Engineering, Flogistix by Flowco.
Instant Savings and Speed with Tiger Data
Within the first month of real usage, we saw the combination of compression + CAGGs eliminate our worst pain points around cost and query latency. Reliability of inbound data jumped (no more “mystery gaps”) and long-range queries became practical because teams pivoted to CAGGs for most views while raw data remained available for deep dives.
66% savings on infrastructure and storage costs after implementing and resizing our pipelines and databases.
84% compression in production after tuning, with CAGGs and hypertables compressed.
“We started seeing benefits around 3–4 weeks after starting to use Tiger Data, great time-to-value results to help manage costs for a fleet that grows 10–15% per year.” - Danny Burrows, VP of Software Engineering, Flogistix by Flowco.
Flowco Engineers Advance Their Competitive Advantage
By working with Tiger Data, we modernized our data pipeline to ingest at the edge, keep dashboards fast with continuous aggregates, and retain raw data for deep analysis. With native compression and tiering, our data reliability jumped from ~95% to well above 99%, and by using standard SQL on Postgres, we’ve cut costs and boosted developer velocity.
“We didn’t see the gaps we used to; data reliability went from about 95% to well above 99%.” - Danny Burrows, VP of Software Engineering, Flogistix by Flowco.
Real-time ingest without fighting the system: we log at the edge and push when the pipe allows. CAGGs keep dashboards fast while raw is retained.
Cheaper long-term retention: native compression + tiering means we don’t delete history we actually need.
Operational uptime: reliability of incoming data rose from “~95% good” to “well above 99%,” which directly affects how quickly we can triage in the field.
Looking Ahead
We’ll keep tightening CAGG refresh policies, add indexes on our most-hit aggregates, and continue tuning compression windows as ingest patterns evolve. We’re also exploring new data tiering strategies and broader replica usage for heavy analytics.
How ControlCom Turns 300+ Million Monthly Facility Data Points Into Instant Answers With Tiger Data
Industrial IoT on TimescaleDB: ControlCom streams 1K-10K points/sec from thousands of assets, powering instant dashboards and AI that caught $160K billing errors.
How Float Runs an AI Energy Company on a 3-Person Team with Tiger Data
How Danish startup Float hit 99.3% compression on 1Hz smart meter data with Tiger Data, powering appliance-level energy analytics for hundreds of homes.