Time-series data provides significant value to organizations because it enables them to analyze important real-time and historical metrics. By showing trends over time, time-series data allows for decision-making based on relations between old and new data. Unsurprisingly, time-series analysis is an extensively developed field of data analysis.
However, data is valuable only if it’s easy to access. That’s where being able to build fast dashboards for time-series data becomes a force multiplier for organizations looking to expose their analytics across teams.
In this post, we will look at Timescale's continuous aggregates to speed up queries that aggregate over time. Additionally, we will walk through building a sample application that leverages this feature specific to TimescaleDB.
What Are Continuous Aggregates?
Continuous aggregates are Timescale's enhanced version of PostgreSQL materialized views. They pre-aggregate your data, just like materialized views, but they are automatically refreshed in the background as new data is added or old data is modified. This means that when you query a continuous aggregate, you will always get up-to-date results.
But before we actually work with continuous aggregates, let's see how they operate under the hood.
How continuous aggregates work
The design of continuous aggregates was heavily influenced by PostgreSQL materialized views, but continuous aggregates work like a materialized view on steroids. Under the hood, materialized views are tables that store the results of an aggregate query so that it can be accessed without recomputation, basically caching the query result.
The main problem of materialized views—especially when you're collecting data frequently, such as in the case of time-series data—is that they get out of date as soon as new data is added. You can manually refresh a materialized view, but it will recompute the entire aggregate, slowing down the aggregation process.
In sum, continuous aggregates allow for the computational leverage of a PostgreSQL materialized view while staying consistent with updates to the database—a powerful improvement if you're building PostgreSQL dashboards at scale.
A Sample Time-Series Dashboard With Continuous Aggregates
time_bucket()and time_bucket_gapfill() are two critical TimescaleDB time-series functions. Time_bucket() is used for aggregating arbitrarily-sized time periods, and gapfill() is important when your time buckets have missing data or gaps, which is a very common occurrence when capturing thousands of time-series readings per second. Together, both of these are essential for analyzing and visualizing time-series data.
The sample application is written in Python. It essentially scrapes the Open AQ (air quality) API, parses the results, and stores all measurements collected from air quality sensors for all cities in Great Britain. You can check out the code here.
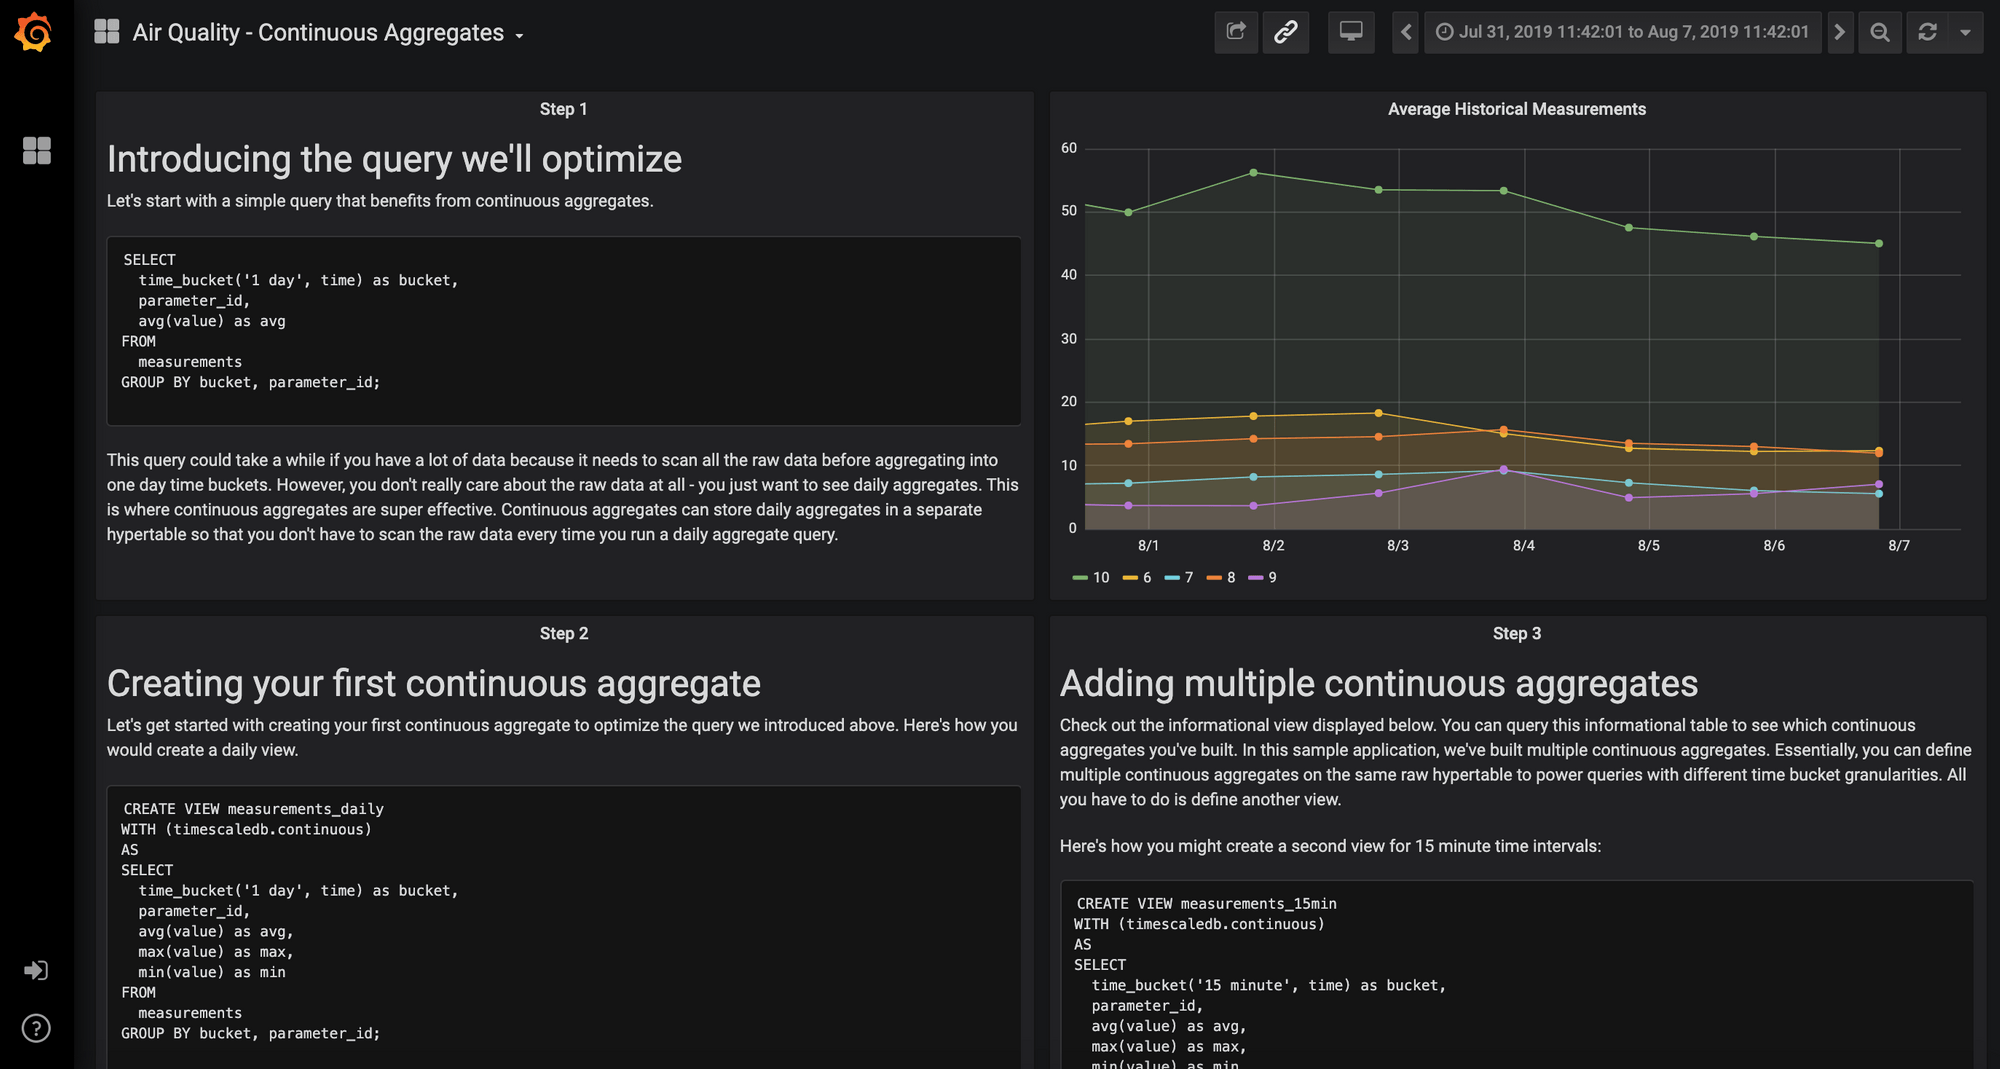
To give you a quick sense of why continuous aggregates are really useful, here’s a query that we use in the Air Quality example:
SELECT
  time_bucket('1 day', time) as bucket,
  parameter_id,
  avg(value) as avg,
  max(value) as max,
  min(value) as min
FROM
  measurements
GROUP BY bucket, parameter_id;
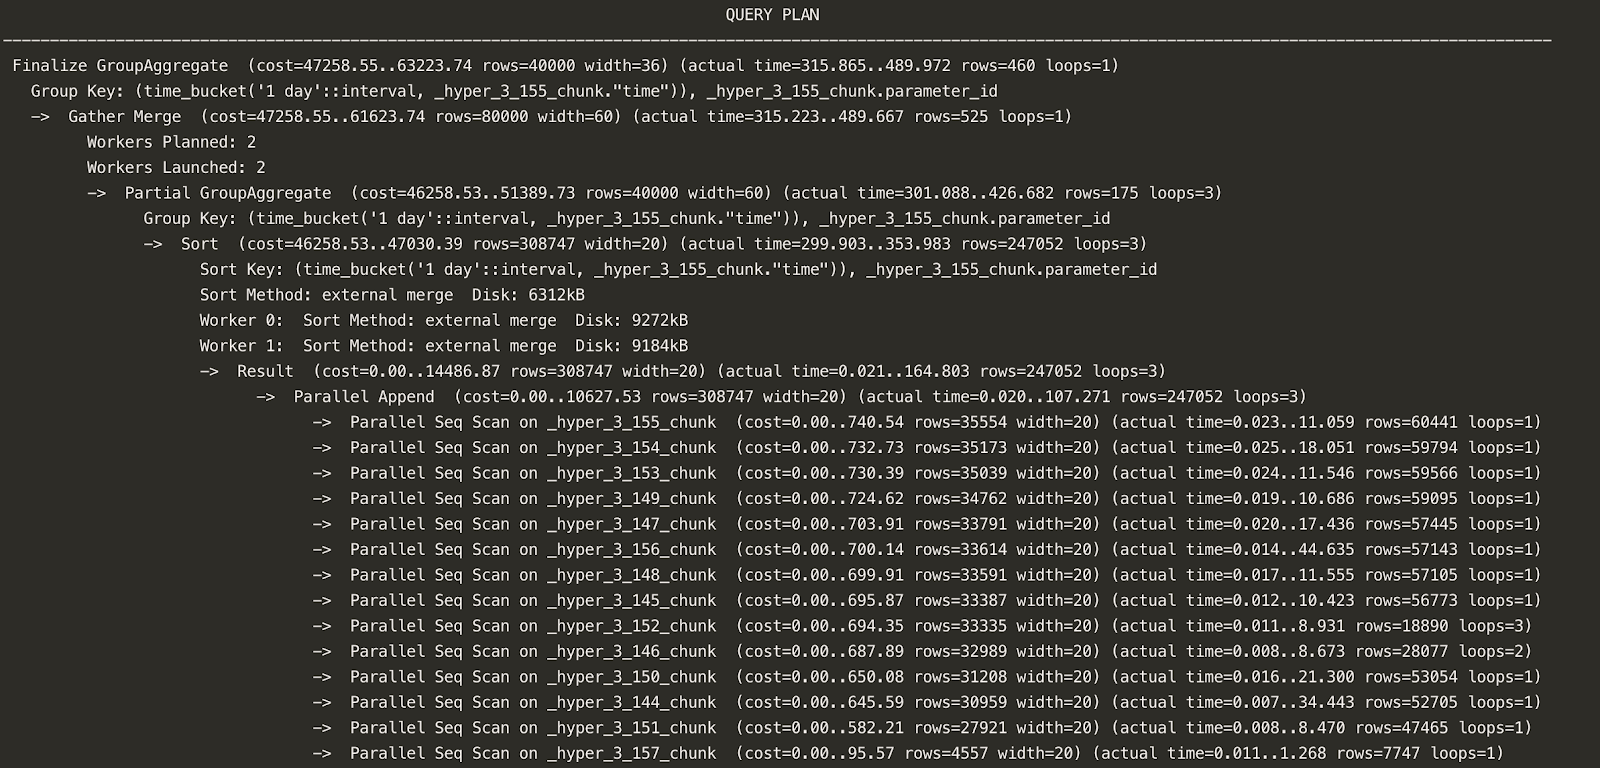
You’ll notice that we are querying across all time and bucketing things by 1-day intervals. The computations of bucketing things by one day, as well as reading all that data off disk, is high. The table at the point at which I’m running this query has ~700k rows. You can imagine how this query could get really slow as you add more data.
Below is an example query plan. Notice how much work is required to compute this query!
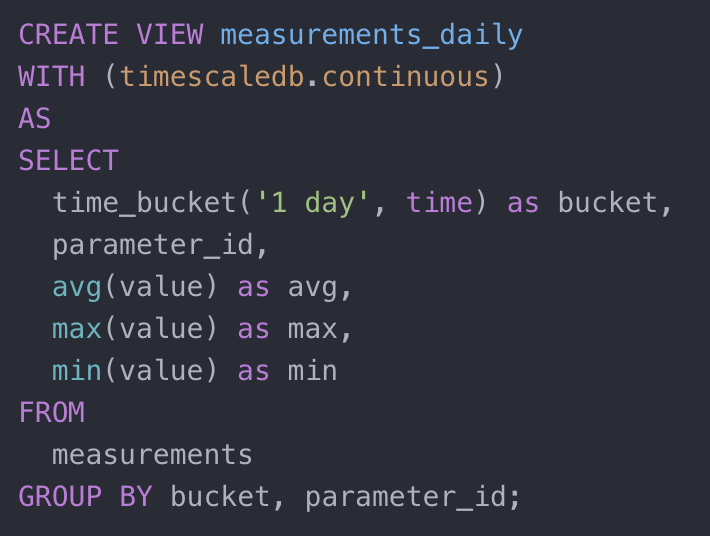
To speed this up, I wrote a continuous aggregate.
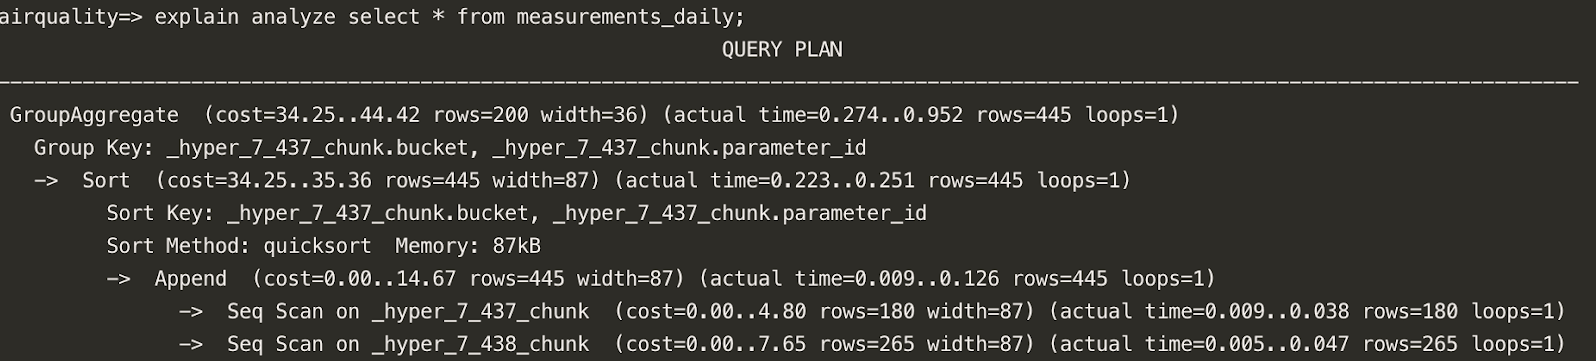
Now, let’s try to query the same thing but query the measurements_daily table directly. The query plan is greatly simplified because it no longer scans as much data.
Advanced configurations and toggles
By default, continuous aggregates are materialized only (since version 2.11).
timescaledb.materialized_only is true by default, but when set to false, it can unite real-time data from the raw hypertable with the continuous aggregates materialized part.
After creating the continuous aggregates, if you follow the WITH NO DATA option, it will not update or materialize new data but will wait for a call to refresh the data. Timescale offers a refreshing data policy that allows us to define how often to update the materialized view.
There’s also the refresh_continuous_aggregates function that you can call to materialize the data from a specific time range. Policies have the advantage of running as a background worker, continuously updating as new data comes.
If data changes, the policy also tracks the fragments that need to be updated and runs them together in the next refresh, managing and updating the continuous aggregates.
Next Steps
As you can see, continuous aggregates can be an extremely useful function when you are looking to further reduce disk throughput and compute requirements when running historical aggregate queries.
SkipScan in TimescaleDB: Why DISTINCT Was Slow, How We Built It, and How You Can Use It
Learn how TimescaleDB's SkipScan transforms DISTINCT queries from multi-second waits to milliseconds by jumping between values instead of scanning every row.
Introducing Phased Rollouts for Safer TimescaleDB Upgrades
Tiger Data introduces Phased Rollouts, a safer upgrade process for all TimescaleDB services on Tiger Cloud providing a 3-week validation period between dev and production deployments.
Introducing Direct Compress: Up to 40x Faster, Leaner Data Ingestion for Developers (Tech Preview)
Direct Compress delivers up to 40x faster data ingestion for TimescaleDB by compressing time-series data in memory during insertion, eliminating background jobs.