Building an Ingest Safety Monitor for Your IIoT Pipeline in SQL
Ingest fails suddenly, not gradually. Sample WAL volume, replica lag, and dead tuples every minute, and get one headroom percentage you can alert on.
By John Shi
October 16th, 2026
J
By John Shi
September 18th, 2026
7 min
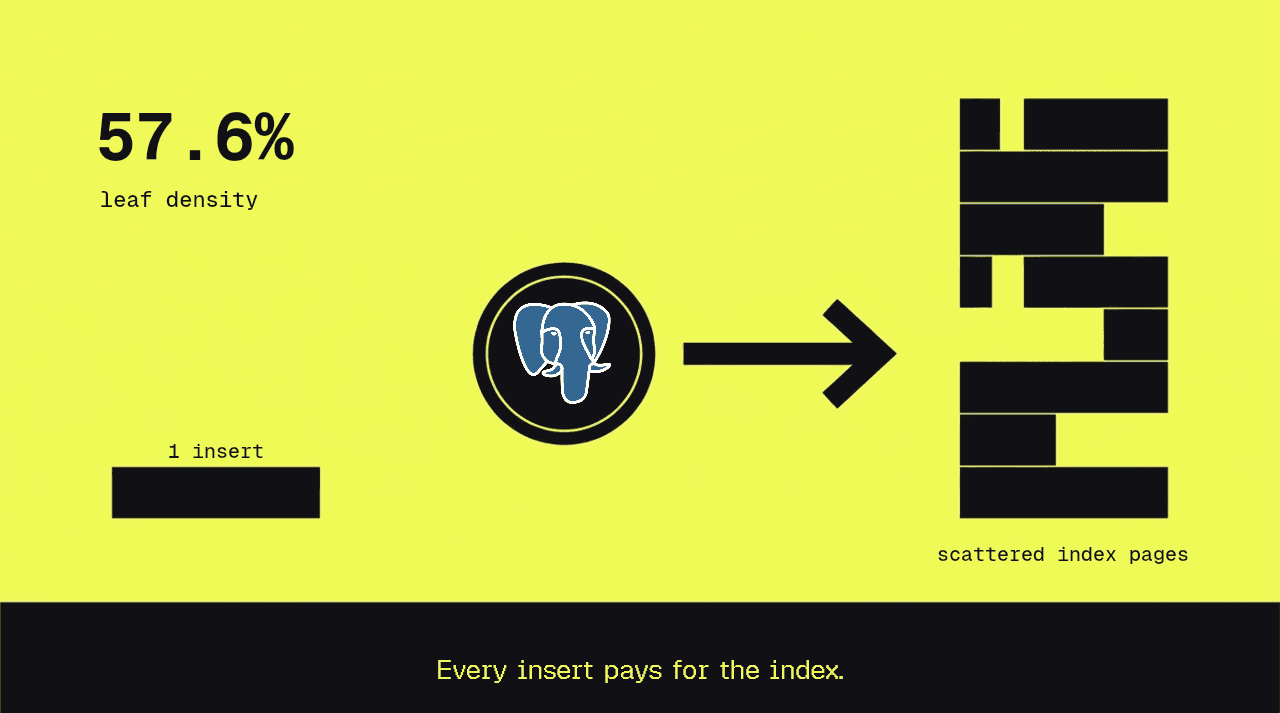
Every insert pays for an index, but only the queries that use the index benefit.
That gap is what makes an index a decision instead of a default. The index in this guide changed a dashboard query from a full table scan to a seek, and charged every insert to do it. Which side wins depends on how often that query runs and how much ingest headroom you have.
By the end of this guide you'll know which query shapes a composite index accelerates, how to measure its write penalty, and how to decide using your ingest ceiling instead of a hunch. You'll leave with two queries you can run against production today.
Indexes get added during incidents and nobody comes back to audit them. Each one turns a logical insert into an extra physical write, with its own buffer to dirty and its own WAL record. Five indexes mean six writes per row. That's Phase 1 of the Optimization Treadmill, the cycle where each round of tuning buys a few months before the next ceiling arrives. Indexing buys three to six months, and then write throughput is the ceiling.
The write tax is invisible because nothing reports it. EXPLAIN shows what an index saves, down to the buffer, but it doesn’t show what it costs per row. The benefit comes as a number, the cost comes as a hunch, and the hunch loses every time.
Fortunately, both costs and benefits are measurable. The rest of this guide measures them in a specific order to help you decide whether a composite index is right for you.
Before pricing an index, check that it does anything for you. A composite index answers questions that start with its leading column. If yours don't, it's pure write cost, and nothing in the next three sections will save it.
That comes from how a B-tree stores keys. The sort is lexicographic: (tag_id, ts DESC) orders by tag_id, then by ts within each tag. No ts ordering spans tags.
Every example below runs against readings, which holds 40 million rows, 90 days of history, 10,000 tags.
CREATE INDEX readings_tag_ts_idx ON readings (tag_id, ts DESC);That index serves queries like WHERE tag_id = 4417 AND ts >= now() - interval '30 days', one tag across a third of that history, because both columns are used left to right. It serves WHERE tag_id = 4417 ORDER BY ts DESC LIMIT 500, the newest 500 readings for that tag, with no sort node. (Postgres reads B-trees in both directions, so plain (tag_id, ts) would serve that one too. The explicit DESC earns its place only on mixed-direction sorts.)
This index cannot seek on ts alone, and that failure is worse than being ignored. Ask for one hour across all tags, 18,500 rows out of the 40 million, and Postgres still picks it, reading 161,347 buffers to find them against roughly 254,000 to scan the entire table. The index gets used and barely helps. Widen the window to a day and the planner abandons it.
Run that test before you run any benchmarks. If your queries lead with the indexed column, start pricing. If not, you have your answer already.
Pricing starts on the read side, with the query that motivated the index. Run that query under EXPLAIN (ANALYZE, BUFFERS) and read the buffer counts rather than the timings. Buffer counts hold steady across runs. Timings swing with whatever happens to be cached.
Without the index, the dashboard query from Step 1 has to scan the whole table:
Limit (actual time=1569.568..1569.651 rows=500 loops=1)
  Buffers: shared hit=130716 read=124065
  ->  Sort (actual time=1504.763..1504.807 rows=500 loops=1)
        Sort Key: ts DESC
        ->  Seq Scan on readings (actual time=1019.622..1504.049 rows=1333 loops=1)
              Filter: ((tag_id = 4417) AND (ts >= (now() - '30 days'::interval)))
              Rows Removed by Filter: 39998667
Execution Time: 1583.016 ms
That is the same full-table scan Step 1 priced at roughly 254,000 buffers, plus a sort to pull the newest 500 rows out of the 1,333 that matched.
With the index:
Limit (actual time=0.061..3.676 rows=500 loops=1)
  Buffers: shared hit=500 read=6
  ->  Index Scan using readings_tag_ts_idx on readings (actual time=0.060..3.594 rows=500 loops=1)
        Index Cond: ((tag_id = 4417) AND (ts >= (now() - '30 days'::interval)))
Execution Time: 3.763 ms
254,781 buffers down to 506, and the sort node disappears, because the index already holds each tag's rows in ts DESC order.
That saving is the entire benefit side of the ledger. Everything from here measures what it costs.
The cost side is harder to see, because no query plan reports it. It depends almost entirely on which column leads the index, and that is where most teams guess wrong.
(ts)          [leaf][leaf][leaf][leaf*]      1 insertion point, packs to 90%
(tag_id, ts)  [leaf*][leaf][leaf*][leaf*]    10,000 of them, all half empty
With a ts-led index, every new row sorts after every existing one, so all inserts land on the rightmost leaf page. Postgres splits that page to the index fillfactor, 90 percent by default, rather than down the middle. With (tag_id, ts DESC) and 10,000 tags there are 10,000 insertion points instead of one. The page an insert needs is rarely the page the previous insert touched, and each split leaves both halves half full.
That difference is measurable. Load 5 million rows into two empty tables, one indexed on ts and one on (tag_id, ts DESC), then read the result with pgstatindex from the pgstattuple extension:
| Index | Built by | Size | Leaf density |
|---|---|---|---|
(ts) | 5M inserts | 107 MB | 90.1% |
(tag_id, ts DESC) | 5M inserts | 236 MB | 57.6% |
(tag_id, ts DESC) | one CREATE INDEX | 150 MB | 90.0% |
The third row is the control: the same index over the same rows, built in a single pass instead of row by row. Built in one pass it holds 90 percent density. Built by inserts it settles at 57.6 percent and takes 57 percent more disk. That gap is page-split waste, and only REINDEX reclaims it.
WAL carries the same penalty. Each index insertion writes its own record, and the first change to a page after a checkpoint writes a full-page image of that page into WAL. Appending keeps reusing pages already dirtied since the last checkpoint, so it skips most of those images. Scattering does not. Across the same 5 million inserts, the scattered index wrote 834MB of WAL against 699MB, and took 22.1 seconds against 15.7.
So the question is not whether an index slows writes, but instead whether it scatters them.
Density and WAL explain the mechanism. What you decide with is throughput, and that takes a benchmark.
Run the benchmark against a copy of production, never an empty table. An empty table hides the cost, because the whole index stays in cache. This is easy to get wrong: the first run of the numbers below used a 10-million-row table and reported a 4.7 percent penalty, because the index still fit inside shared_buffers.
\set tag random(1, 10000)
INSERT INTO readings (ts, tag_id, value) VALUES (now(), :tag, random() * 100);
pgbench -n -f insert.sql -c 8 -j 2 -T 60 yourdbRun that script twice against the 40-million-row table, once with the index in place and once without:
Those two figures are your ingest ceiling with and without the index. Expect a wider gap once the index outgrows memory. At 1.2GB on a 7GB box this one still lived in page cache, so the scattered reads never reached disk. Size the test to your own memory ratio.
| Configuration | Inserts/sec | Change |
|---|---|---|
| No index | 12,623 | baseline |
(tag_id, ts DESC) | 11,639 | −7.8% |
Both sides are now on the table, in different units. A read saving measured in buffers cannot be weighed against a write cost measured in percent. Convert the cost into the one number that actually constrains you: your ingest ceiling.
Step 4 put that ceiling at 11,639 inserts per second with the index and 12,623 without. Compare it against your peak ingest rate:
Focus on peak, not average. A pipeline averaging 4,000 rows a second and spiking to 12,000 at the top of each hour breaks at the spike, and the index is what put it there.
That rule works on an index you are considering. It works just as well on the ones already installed, and those have usually never been checked. This query lists them with their scan count and their footprint:
SELECT
    s.indexrelname AS index_name,
    s.idx_scan,
    pg_size_pretty(pg_relation_size(s.indexrelid)) AS index_size,
    i.indisunique AS is_unique
FROM pg_stat_user_indexes s
JOIN pg_index i ON i.indexrelid = s.indexrelid
WHERE s.relname = 'readings'
ORDER BY pg_relation_size(s.indexrelid) DESC;
Look for a large index_size beside an idx_scan at or near zero. Those indexes charge every insert and return nothing.
Three checks before dropping one:
pg_stat_database.stats_reset. If counters reset last week, a zero scan count means nothing. You need a full business cycle, monthly reports included.idx_scan is per node. An index unused on the primary may be carrying every analytics query on a replica.The audit also turns up redundancy. A standalone (tag_id) index sitting next to (tag_id, ts DESC) is close to dead weight, because any query the narrow index serves, the composite index serves from its leading column. Two write penalties, one capability.
After dropping or adding an index, reset the counters and let one full cycle run. pg_stat_reset_single_table_counters takes one relation at a time, and an index counts as its own relation, so pass each index OID rather than the table's:
SELECT pg_stat_reset_single_table_counters(indexrelid)
FROM pg_index
WHERE indrelid = 'readings'::regclass;
A week later, run the audit again. Every index still on the table should map to a query you can name, and your ingest ceiling should have moved by roughly what Step 4 predicted. If the ceiling did not move, the index was never the bottleneck, and WAL flushing or autovacuum is the next place to look.
Run the audit query against your highest-volume table this week. Indexes with real size and near-zero scans are the easiest throughput you'll ever recover. Use DROP INDEX CONCURRENTLY so the drop does not block writes.
Once the dead indexes are gone, the survivors are real trade-offs, and adding more B-trees stops being the answer. That is where chunk-level indexing changes the arithmetic. A Tiger Data hypertable splits the table into time-based chunks and indexes each chunk separately, so an insert touches a small, recent index instead of one that grows without bound. Test that against your own workload with a free Tiger Data trial today.
About the author
J
By John Shi
// Related posts
Ingest fails suddenly, not gradually. Sample WAL volume, replica lag, and dead tuples every minute, and get one headroom percentage you can alert on.
By John Shi
October 16th, 2026
Stop waiting for the dashboard to get slow. Record latency against row count, fit the curve, and get a date when your query breaches its target.
By John Shi
October 9th, 2026
A 20-byte sensor reading costs 95.6 on disk. Measure bytes per row, project 631 billion rows, and test your ingest ceiling before the schema review.
By John Shi
September 25th, 2026
Receive the latest technical articles and release notes in your inbox.