This post is a practical companion to It's 2026, Just Use Postgres. That post makes the architectural case for consolidating on Postgres. This one shows you how.
Below are working SQL examples for each use case. Every extension listed here is available on Tiger Cloud with no additional setup. If you're self-hosting, each section links to the extension's repo.
What you'll be able to do after reading this: Set up Postgres extensions for full-text search, vector search, time-series, caching, message queues, document storage, geospatial queries, and scheduled jobs. Each section is self-contained, so you can skip to what you need.
Enable Everything
Here's the full set. You probably don't need all of them. Pick the ones that match your workload.
CREATE EXTENSION pg_textsearch;   -- BM25 full-text search
CREATE EXTENSION vector;          -- Vector search (pgvector)
CREATE EXTENSION vectorscale;     -- DiskANN index for vectors
CREATE EXTENSION ai;              -- AI embeddings and RAG workflows
CREATE EXTENSION timescaledb;     -- Time-series
CREATE EXTENSION pgmq;            -- Message queues
CREATE EXTENSION pg_cron;         -- Scheduled jobs
CREATE EXTENSION postgis;         -- Geospatial
Full-Text Search (Replace Elasticsearch)
Extension: pg_textsearch (true BM25 ranking)
What you're replacing: Elasticsearch (separate JVM cluster, complex mappings, sync pipelines), Solr, or Algolia ($1 per 1,000 searches).
What you get: The same BM25 algorithm that powers Elasticsearch, running natively in Postgres. No separate cluster. No sync jobs. No data drift.
CREATE TABLE articles (
  id SERIAL PRIMARY KEY,
  title TEXT,
  content TEXT
);

-- Create a BM25 index
CREATE INDEX idx_articles_bm25 ON articles USING bm25(content)
  WITH (text_config = 'english');

-- Search with BM25 scoring
SELECT title, -(content <@> 'database optimization') AS score
FROM articles
ORDER BY content <@> 'database optimization'
LIMIT 10;
Deep dive: You Don't Need Elasticsearch: BM25 is Now in Postgres
Vector Search (Replace Pinecone)
Extensions: pgvector + pgvectorscale
What you're replacing: Pinecone ($70/month minimum, separate infrastructure, data sync), Qdrant, Milvus, or Weaviate.
What you get: pgvectorscale uses the DiskANN algorithm (from Microsoft Research). On a 50M vector benchmark, it achieved 28x lower p95 latency and 16x higher throughput than Pinecone at 99% recall.
CREATE EXTENSION vector;
CREATE EXTENSION vectorscale CASCADE;

CREATE TABLE documents (
  id SERIAL PRIMARY KEY,
  content TEXT,
  embedding vector(1536)
);

-- High-performance DiskANN index
CREATE INDEX idx_docs_embedding ON documents USING diskann(embedding);

-- Find similar documents
SELECT content, embedding <=> '[0.1, 0.2, ...]'::vector AS distance
FROM documents
ORDER BY embedding <=> '[0.1, 0.2, ...]'::vector
LIMIT 10;
Auto-sync embeddings with pgai
No more manual embedding pipelines. pgai regenerates embeddings automatically on every INSERT and UPDATE.
SELECT ai.create_vectorizer(
  'documents'::regclass,
  loading => ai.loading_column(column_name => 'content'),
  embedding => ai.embedding_openai(
    model => 'text-embedding-3-small',
    dimensions => '1536'
  )
);
Every row stays in sync. No batch jobs. No drift.
Hybrid Search: BM25 + Vectors in One Query
This is where Postgres consolidation pays off immediately. Combining keyword search and semantic search in other stacks requires two API calls, result merging, failure handling, and double the latency. In Postgres, it's one query.
Simple weighted hybrid
SELECT
  title,
  -(content <@> 'database optimization') AS bm25_score,
  embedding <=> query_embedding AS vector_distance,
  0.7 * (-(content <@> 'database optimization')) +
  0.3 * (1 - (embedding <=> query_embedding)) AS hybrid_score
FROM articles
ORDER BY hybrid_score DESC
LIMIT 10;
Reciprocal Rank Fusion (for RAG applications)
WITH bm25 AS (
  SELECT id, ROW_NUMBER() OVER (ORDER BY content <@> $1) AS rank
  FROM documents LIMIT 20
),
vectors AS (
  SELECT id, ROW_NUMBER() OVER (ORDER BY embedding <=> $2) AS rank
  FROM documents LIMIT 20
)
SELECT d.*,
  1.0 / (60 + COALESCE(b.rank, 1000)) +
  1.0 / (60 + COALESCE(v.rank, 1000)) AS score
FROM documents d
LEFT JOIN bm25 b ON d.id = b.id
LEFT JOIN vectors v ON d.id = v.id
WHERE b.id IS NOT NULL OR v.id IS NOT NULL
ORDER BY score DESC LIMIT 10;
One query. One transaction. One result set.
Time-Series (Replace InfluxDB)
Extension: TimescaleDB (21K+ GitHub stars)
What you're replacing: InfluxDB (separate database, Flux or limited SQL), Prometheus (metrics only, not application data).
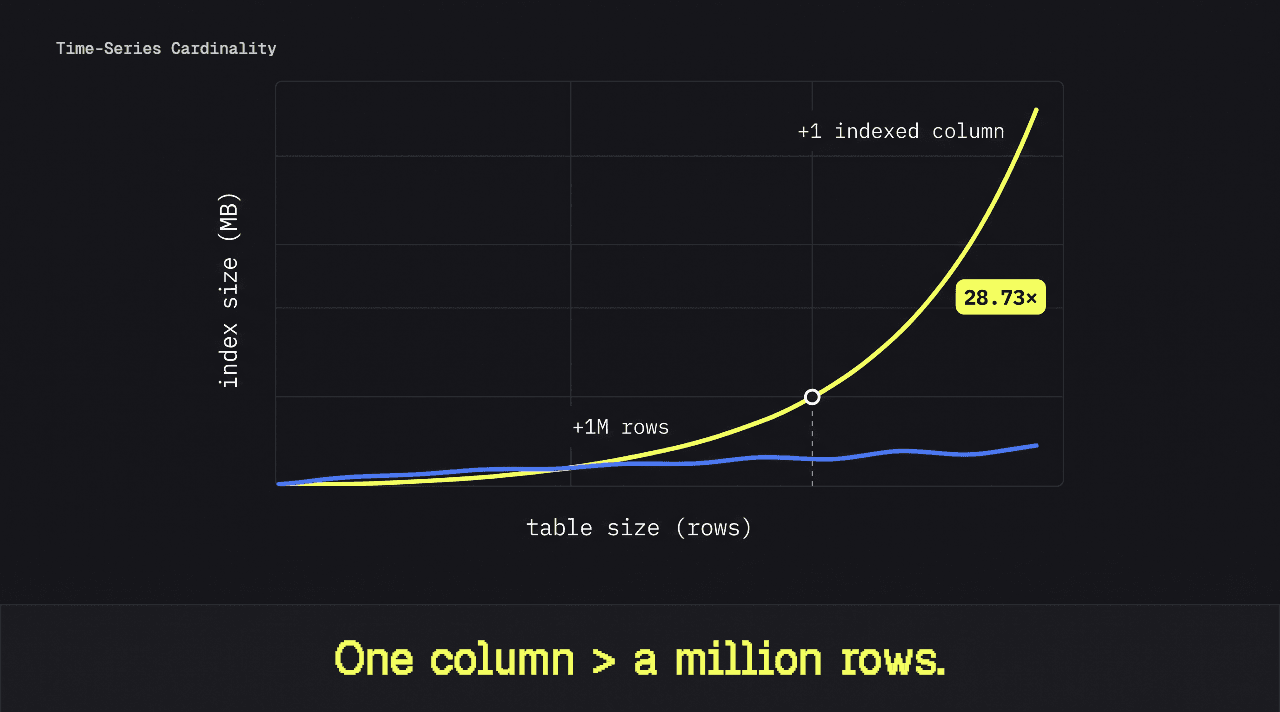
What you get: Automatic time-based partitioning, compression up to 95%, continuous aggregates for fast dashboards, and full SQL. Your time-series data lives alongside your relational data with JOINs and ACID guarantees.
CREATE EXTENSION timescaledb;

CREATE TABLE metrics (
  time TIMESTAMPTZ NOT NULL,
  device_id TEXT,
  temperature DOUBLE PRECISION
);

-- Convert to a hypertable (automatic time partitioning)
SELECT create_hypertable('metrics', 'time');

-- Query with time buckets
SELECT time_bucket('1 hour', time) AS hour,
       AVG(temperature)
FROM metrics
WHERE time > NOW() - INTERVAL '24 hours'
GROUP BY hour;
Lifecycle automation
TimescaleDB handles retention and compression policies so you don't have to build cron jobs for data management.
-- Automatically drop data older than 30 days
SELECT add_retention_policy('metrics', INTERVAL '30 days');

-- Compress data older than 7 days (up to 95% storage reduction)
ALTER TABLE metrics SET (timescaledb.compress);
SELECT add_compression_policy('metrics', INTERVAL '7 days');
Case study: Plexigrid went from 4 databases to 1 and got 350x faster queries.
Caching (Replace Redis)
Feature: UNLOGGED tables + JSONB (built into Postgres, no extension needed)
What you're replacing: Redis for simple key-value caching scenarios.
What you get: In-memory-speed storage without WAL overhead. Good for session data, temporary lookups, and simple caches. No separate service to operate.
When to keep Redis: If you need pub/sub, sorted sets, Lua scripting, or complex data structures, Redis is still the better tool for those specific jobs.
-- UNLOGGED = no WAL overhead, faster writes
CREATE UNLOGGED TABLE cache (
  key TEXT PRIMARY KEY,
  value JSONB,
  expires_at TIMESTAMPTZ
);

-- Set with expiration
INSERT INTO cache (key, value, expires_at)
VALUES ('user:123', '{"name": "Alice"}', NOW() + INTERVAL '1 hour')
ON CONFLICT (key) DO UPDATE SET value = EXCLUDED.value;

-- Get
SELECT value FROM cache
WHERE key = 'user:123' AND expires_at > NOW();

-- Schedule cleanup with pg_cron
SELECT cron.schedule('cache_cleanup', '0 * * * *',
  $$DELETE FROM cache WHERE expires_at < NOW()$$);
Message Queues (Replace Kafka)
Extension: pgmq
What you're replacing: Kafka or RabbitMQ for task queues and simple event processing.
What you get: A lightweight message queue inside Postgres. Send, receive with visibility timeouts, and delete after processing. Transactional with the rest of your data.
When to keep Kafka: If you need high-throughput event streaming across dozens of services, consumer groups, exactly-once semantics, or multi-datacenter replication, Kafka is purpose-built for that.
CREATE EXTENSION pgmq;
SELECT pgmq.create('my_queue');

-- Send a message
SELECT pgmq.send('my_queue', '{"event": "signup", "user_id": 123}');

-- Receive (with 30-second visibility timeout)
SELECT * FROM pgmq.read('my_queue', 30, 5);

-- Delete after processing
SELECT pgmq.delete('my_queue', msg_id);
Alternative: SKIP LOCKED pattern (no extension needed)
For simple job queues, Postgres has a built-in pattern using FOR UPDATE SKIP LOCKED:
CREATE TABLE jobs (
  id SERIAL PRIMARY KEY,
  payload JSONB,
  status TEXT DEFAULT 'pending'
);

-- Worker claims a job atomically
UPDATE jobs SET status = 'processing'
WHERE id = (
  SELECT id FROM jobs WHERE status = 'pending'
  FOR UPDATE SKIP LOCKED LIMIT 1
) RETURNING *;
Documents (Replace MongoDB)
Feature: Native JSONB (built into Postgres since 2014)
What you're replacing: MongoDB for document storage.
What you get: Schemaless document storage with GIN indexing, plus everything Postgres gives you: ACID transactions, relational JOINs, and SQL. No separate database for your "document-shaped" data.
CREATE TABLE users (
  id SERIAL PRIMARY KEY,
  data JSONB
);

-- Insert a nested document
INSERT INTO users (data) VALUES ('{
  "name": "Alice",
  "profile": {"bio": "Developer", "links": ["github.com/alice"]}
}');

-- Query nested fields
SELECT data->>'name', data->'profile'->>'bio'
FROM users
WHERE data->'profile'->>'bio' LIKE '%Developer%';

-- Index specific JSON fields for fast lookups
CREATE INDEX idx_users_email ON users ((data->>'email'));
Geospatial (Replace Specialized GIS)
Extension: PostGIS (the industry standard since 2001)
What you're replacing: Nothing, really. PostGIS is what most specialized GIS tools are built on. It powers OpenStreetMap and has been in production for 24 years.
CREATE EXTENSION postgis;

CREATE TABLE stores (
  id SERIAL PRIMARY KEY,
  name TEXT,
  location GEOGRAPHY(POINT, 4326)
);

-- Find stores within 5km
SELECT name,
  ST_Distance(location, ST_MakePoint(-122.4, 37.78)::geography) AS meters
FROM stores
WHERE ST_DWithin(location, ST_MakePoint(-122.4, 37.78)::geography, 5000);
Scheduled Jobs (Replace External Cron)
Extension: pg_cron
What you're replacing: External cron jobs, Kubernetes CronJobs, or Lambda scheduled triggers for database maintenance tasks.
What you get: Cron scheduling inside Postgres. Useful for cache cleanup, materialized view refreshes, data retention, and periodic aggregation.
CREATE EXTENSION pg_cron;

-- Run cache cleanup every hour
SELECT cron.schedule('cleanup', '0 * * * *',
  $$DELETE FROM cache WHERE expires_at < NOW()$$);

-- Refresh a materialized view every night at 2 AM
SELECT cron.schedule('rollup', '0 2 * * *',
  $$REFRESH MATERIALIZED VIEW CONCURRENTLY daily_stats$$);
Fuzzy Search (Typo Tolerance)
Extension: pg_trgm (built into Postgres)
CREATE EXTENSION pg_trgm;

CREATE INDEX idx_name_trgm ON products USING GIN (name gin_trgm_ops);

-- Finds "PostgreSQL" even when typed as "posgresql"
SELECT name FROM products
WHERE name % 'posgresql'
ORDER BY similarity(name, 'posgresql') DESC;
What's Next
If you want the architectural argument for why consolidating on Postgres matters (especially in the AI era), read It's 2026, Just Use Postgres.
All of these extensions come pre-configured on Tiger Cloud. Create a free database and start building.
Further reading: