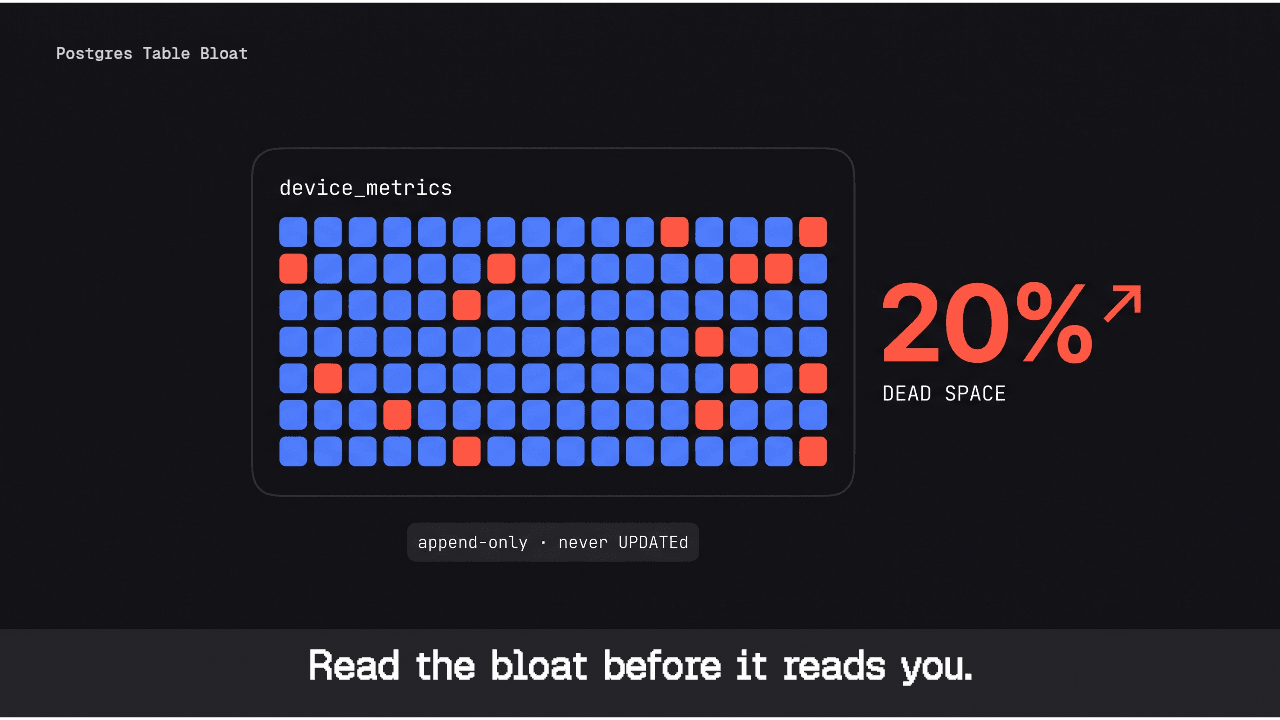
A Postgres table that has never run a single UPDATE can still carry 20% dead space. Bloat is taught as an update-and-delete problem, so this catches high-ingest teams by surprise. On an append-only table taking 50,000 inserts per second, aborted batches and continuous freezing keep autovacuum busy around the clock. When it falls behind, the pages stay allocated and every sequential scan reads dead space at full price.
Bloat almost never announces itself. It shows up as a p95 that drifts up 3 ms a week and a VACUUM that runs longer each night. By the time it registers as an incident, the table is large enough that fixing it means a VACUUM FULL, a rewrite, or a migration. This post gives you the queries to find it, the four patterns you will see, and the settings that keep it from coming back.
What you will learn
- Why MVCC produces dead tuples on tables you never modify.
- How to rank tables by bloat pressure with
pg_stat_user_tables. - How to tell healthy churn from an autovacuum that is losing ground.
- Why index bloat needs a separate query, and what to do about it.
- Which thresholds to set and alert on before bloat becomes a performance problem.
Note: You need PostgreSQL 13 or later for n_ins_since_vacuum, and CREATE EXTENSION pgstattuple for the exact measurements.
Where bloat comes from on append-only tables
Postgres never overwrites a row in place. Every tuple carries a 23-byte header whose t_xmin and t_xmax fields record which transactions can see it. An UPDATE leaves the old version dead until vacuum reclaims the line pointer. That textbook path does not apply to sensor readings or trade records. Two others do.
Aborted transactions
A batch insert that fails on the last row still wrote every preceding tuple to the heap, and those tuples are dead the moment it rolls back. With retry logic in the pipeline, a small abort rate produces a steady stream of dead tuples on a table nobody has ever updated. This is the only mechanism here that creates dead tuples.
Insert-triggered vacuum
Since PostgreSQL 13, autovacuum fires on insert volume, not just dead tuples. Once a table takes more than autovacuum_vacuum_insert_threshold (default 1,000) plus autovacuum_vacuum_insert_scale_factor (default 0.2) times the row count, a vacuum runs to freeze tuples and update the visibility map. A 500-million-row partition hits that at roughly 100 million inserts, or half an hour at 50,000 per second.
So one mechanism fills the table with dead rows and the other keeps vacuum busy cleaning up after a workload that barely dirties anything. None of it is a bug. It is the cost of a concurrency model built for workloads where rows change.
The query: rank your tables by bloat pressure
This reports live and dead tuples, a ratio, on-disk size, and how recently vacuum ran, worst first.
SELECT
    schemaname || '.' || relname                       AS table_name,
    n_live_tup                                         AS live_tuples,
    n_dead_tup                                         AS dead_tuples,
    ROUND(100.0 * n_dead_tup
          / NULLIF(n_live_tup + n_dead_tup, 0), 2)     AS dead_pct,
    n_ins_since_vacuum                                 AS inserts_since_vacuum,
    pg_size_pretty(pg_total_relation_size(relid))      AS total_size,
    autovacuum_count,
    last_autovacuum
FROM pg_stat_user_tables
WHERE n_live_tup + n_dead_tup > 100000
ORDER BY n_dead_tup DESC
LIMIT 20;
These counts are estimates from the cumulative statistics system, and pg_stat_reset() zeroes them. For an exact figure, run pgstattuple on a leaf partition. It reads every page, and it refuses to run against a partitioned parent.
Reading the output
Here are the four patterns you will actually see:
      table_name        | live_tuples | dead_tuples | dead_pct | inserts_since_vacuum | total_size | autovacuum_count |    last_autovacuum
--------------------------+-------------+-------------+----------+----------------------+------------+------------------+------------------------
 public.device_metrics_08 |   412088311 |   118442907 |    22.33 |             41220118 | 68 GB      |             1184 | 2026-08-01 09:14:22-04
 public.audit_log         |    18400221 |    44900318 |    70.93 |                  318 | 41 GB      |              402 | 2026-07-29 02:11:40-04
 public.events_raw        |   208773140 |    31004221 |    12.93 |              9800113 | 34 GB      |             3390 | 2026-08-01 09:41:08-04
 public.trades_2026_07    |   904211887 |     2088410 |     0.23 |               412009 | 122 GB     |             2214 | 2026-08-01 09:44:51-04
The sort puts the worst offender on top, but the ratio and the timestamp tell you which situation you are in.
trades_2026_07: ratio under 5%, recent last_autovacuum. Vacuum is keeping up, even on the largest table here. Nothing to do.
events_raw: ratio steady in the 10% to 20% band, autovacuum_count climbing fast. The equilibrium state on a busy append-only table. Vacuum runs constantly and holds the line. Not a crisis, but you have no headroom for a traffic spike.
device_metrics_08: ratio above 20% and climbing while last_autovacuum stays fresh. Vacuum is running and losing. Each worker is throttled by vacuum_cost_limit, which defaults to 200 and is split across every running worker, so at high insert rates the throttle wins. Check pg_stat_progress_vacuum during a peak.
audit_log: last_autovacuum three days stale, almost no recent inserts, ratio at 71%. Something is blocking cleanup. Usually a long-running transaction or an abandoned replication slot is holding back the xmin horizon, making dead tuples unremovable no matter how often vacuum runs. Check pg_stat_activity for old xact_start values and pg_replication_slots for inactive slots. Tuning will not help until you clear the blocker.
device_metrics_08 is the row to internalize, because it is the one this post is about. Nobody has ever updated it. Its 118 million dead tuples came from aborted batches alone, and vacuum is running flat out and still losing. audit_log looks worse, but a blocked xmin horizon is a bug you clear once. A 22% ratio on an append-only partition is a steady state you inherit.
The heap is only half of it
total_size folds indexes in with the table, and here the common intuition is backwards. A B-tree on a timestamp is the best case, not the worst: Postgres notices inserts landing on the rightmost leaf page and packs those leaves to the 90% fillfactor instead of splitting them down the middle, so a time-ordered index has almost nothing to reclaim. The bloat lives in your other indexes. One on device_id scatters inserts across the tree and splits pages in half, and vacuum never merges partly-full leaf pages back together.
Size alone tells you nothing, since a wide key on narrow rows is legitimately large. Measure density:
CREATE EXTENSION IF NOT EXISTS pgstattuple;

WITH candidates AS (
    SELECT i.schemaname, i.indexrelname, i.indexrelid, i.idx_scan
    FROM pg_stat_user_indexes i
    JOIN pg_class c ON c.oid = i.indexrelid
    JOIN pg_am    a ON a.oid = c.relam
    WHERE a.amname = 'btree'
      AND pg_relation_size(i.indexrelid) > 1024 * 1024
    ORDER BY pg_relation_size(i.indexrelid) DESC
    LIMIT 10
)
SELECT
    schemaname || '.' || indexrelname            AS index_name,
    pg_size_pretty(pg_relation_size(indexrelid)) AS index_size,
    (pgstatindex(indexrelid)).avg_leaf_density   AS leaf_density,
    idx_scan
FROM candidates
ORDER BY leaf_density;
Both guards matter. pgstatindex throws relation is not a btree index on BRIN or GIN, and one error kills the whole result set. It also reads an index in full, so the LIMIT has to pick candidates before density is computed, or you scan every index you own. Run it off-peak regardless.
Read density against 90%. On a test table taking 600,000 incremental inserts, the timestamp index landed at 90.05% and REINDEX returned zero bytes; the device_id index drifted to 80.23% and REINDEX gave back 28% of its size, the extra reclaim coming from empty pages density alone doesn't show. Treat anything under 85% as worth a REINDEX CONCURRENTLY, which unlike VACUUM builds a fresh index and drops the old one, so the space comes back. Treat idx_scan = 0 as a question, not a verdict: pg_stat_reset() zeroes it, replicas keep their own, and an index backing a unique constraint cannot be dropped.
Set thresholds before it compounds
The default autovacuum_vacuum_scale_factor of 0.2 means vacuum waits until 20% of a table is dead. On a 500-million-row partition that is 100 million dead tuples. Scale factors are the wrong lever at that size. Zero them and set flat thresholds on both triggers.
A partitioned parent rejects these with cannot specify storage parameters for a partitioned table, so apply them across every leaf at once. Change the one string on the first line:
DO $$
DECLARE
    parent CONSTANT text := 'device_metrics';
    part   regclass;
BEGIN
    FOR part IN
        SELECT inhrelid::regclass FROM pg_inherits
        WHERE inhparent = parent::regclass
    LOOP
        EXECUTE format($f$
            ALTER TABLE %s SET (
                autovacuum_vacuum_scale_factor        = 0.0,
                autovacuum_vacuum_threshold           = 500000,
                autovacuum_vacuum_insert_scale_factor = 0.0,
                autovacuum_vacuum_insert_threshold    = 5000000,
                autovacuum_vacuum_cost_limit          = 2000
            )$f$, part);
        RAISE NOTICE 'tuned %', part;
    END LOOP;
END $$;
New partitions do not inherit these, so whatever creates tomorrow's partition has to set them too.
Setting only the first pair is the common mistake. It leaves the insert trigger at its default scale factor, so vacuum keeps firing on a schedule you did not choose. Setting autovacuum_vacuum_cost_limit does more than raise the ceiling: a per-table limit is used as written and takes that worker out of the pool sharing the global 200.
Then alert on two signals. Fire when dead_pct on an active partition crosses 15%, an early warning before it leaves the equilibrium band. Fire when last_autovacuum on a table with fresh inserts is older than 30 minutes, because at any real ingest rate the insert trigger should have fired inside that window, so silence means blocked rather than idle. The ratio catches vacuum falling behind. Only the timestamp catches vacuum being prevented.
Confirm it worked
First, verify the settings applied to every partition:
SELECT c.relname, c.reloptions
FROM pg_class c
JOIN pg_namespace n ON n.oid = c.relnamespace
WHERE c.reloptions IS NOT NULL
  AND c.relkind IN ('r','p')
  AND n.nspname NOT IN ('pg_catalog','information_schema')
ORDER BY c.relname;
Second, re-run the ranking query 24 hours later. Expect dead_pct to fall and total_size to stay flat. Plain VACUUM does not compact pages or hand storage back to the OS. It returns space to the free space map, so incoming inserts reuse those 118 million dead tuples' worth of room instead of extending the heap. You are not shrinking the table. You are stopping it from outgrowing your buffer cache. If the ratio came down and stayed down through a write peak, the tuning worked.
When the number comes back
Run the query weekly and watch the trend, not the reading. A dead_pct that holds flat after tuning means you are inside the right architecture, and per-partition thresholds will carry you.
A number that climbs back after every round of tuning means something else. You are on the optimization treadmill: each fix buys three to six months and none changes the trajectory, because you are cleaning up overhead a row-oriented heap generates for data you never modify. At that point the lever is storage layout, not vacuum settings.
Either way the decision starts with the same number, and it is cheaper to know it at 100 million rows than at a billion. Run the ranking query on your largest partition today. Start a free Tiger Cloud trial to test the same workload on your own data.