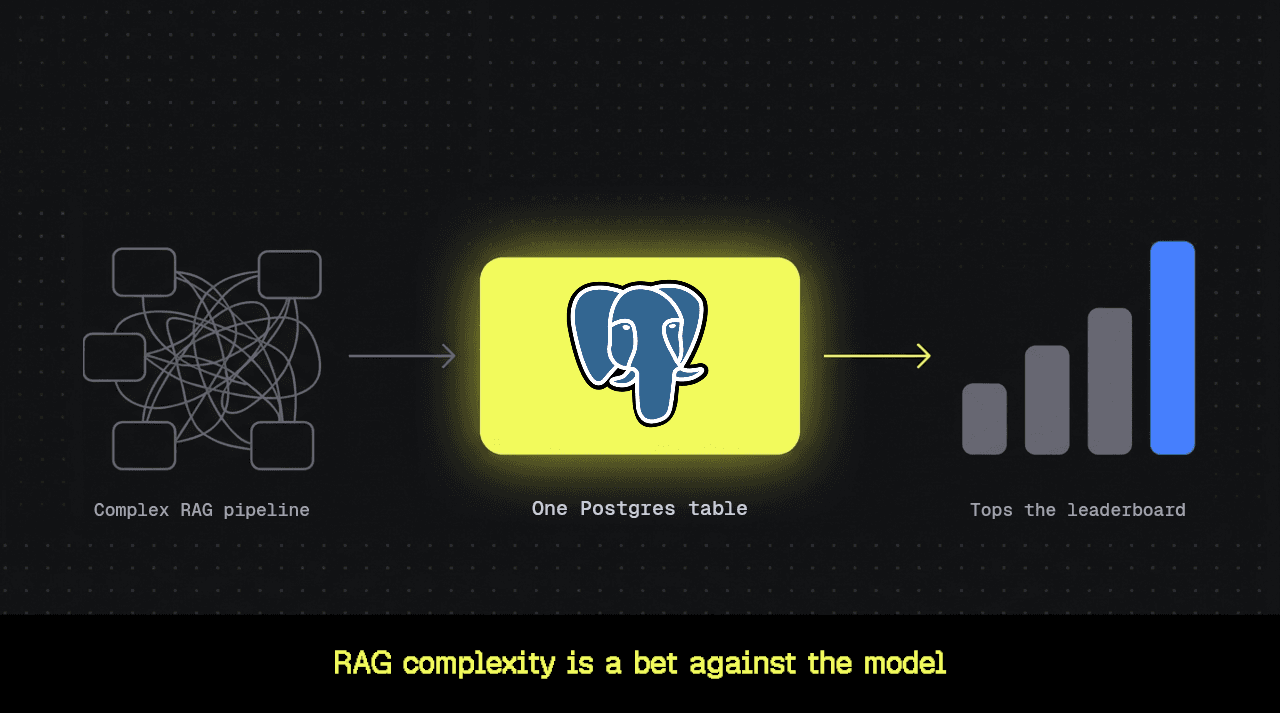
RAG Complexity Is a Bet Against the Model
One Postgres table with two indexes beat every published RAG pipeline on MuSiQue. Every architectural addition is a bet the model stays weak.
By Matvey Arye
September 30th, 2026
By Team Tiger Data
January 15th, 2025
5 min
From chatbots to automotive experiences, we’re witnessing large language models (LLMs) revolutionizing industries and driving the AI adoption race. If you’re familiar with retrieval-augmented generation (RAG), you know it’s a game-changer for giving LLMs the context they need to excel in various applications. This context comes from digging into vast amounts of data using search algorithms, with semantic search leading the pack.
In the early days of RAG, semantic search was exclusive to vector databases, making it seem like a tool only AI engineers could wield. But thanks to plugins like pgai and pgvector alongside platforms like OpenAI, semantic search has broken free from those boundaries. Now, you can unlock this powerful capability in popular databases like PostgreSQL, putting it directly in your hands—no AI expertise required.
Semantic search, or dense vector search, is our go-to strategy for finding the most relevant results by focusing on word associations and meanings. Instead of relying on plain keywords, it uses dense vectors—high-dimensional arrays filled with meaningful data.
The magic happens by calculating the similarity between these embeddings, helping us uncover related information lightning-fast. One popular method is cosine similarity, which measures how close two vectors are to each other. It’s as simple as this formula:
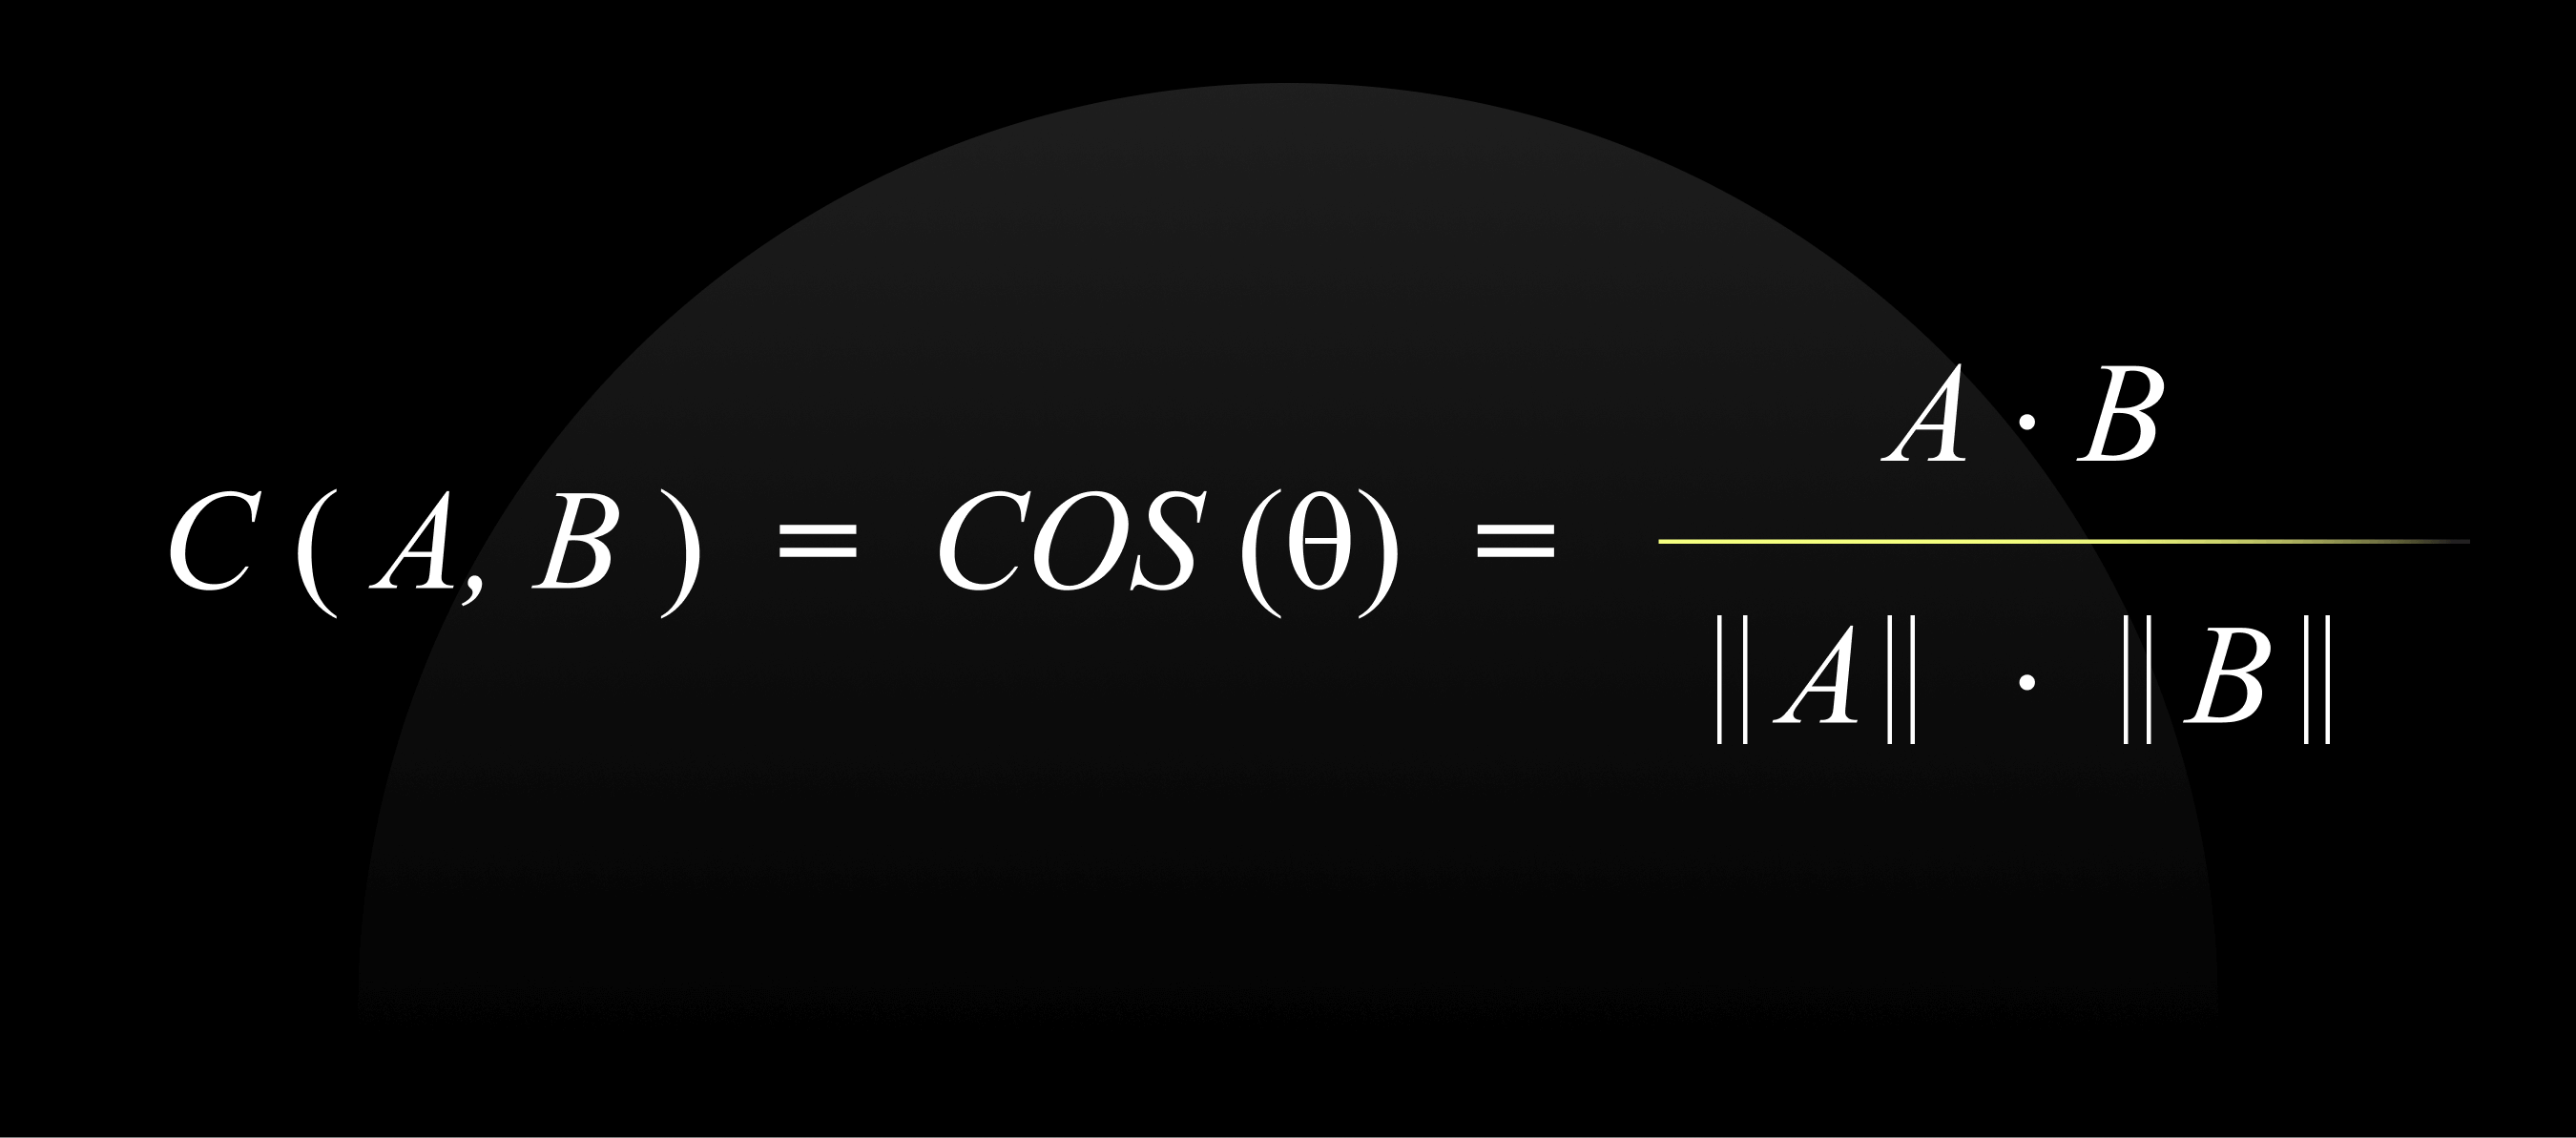
The closer the result is to 1, the more similar the vectors—and the better the search results.
In this article, we’ll set up and perform a semantic search using pgai, pgvector, and OpenAI in just 10 minutes. Let the countdown begin!
Before proceeding, we’ll need an API key from OpenAI. Save this API key, preferably as an environment variable. You can find detailed instructions in the GitHub repository.
Install and import the required libraries:
!pip install pandas pyarrow pgvector openai psycopg2import pandas as pd
import openai
import psycopg2
import os
from ast import literal_evalNow, initialize the OpenAI client.
client = openai.OpenAI(api_key= OPENAI_API_KEY)You can set up the database either locally or in the cloud. If setting it up locally, ensure that PGAdmin is installed and properly configured. For this tutorial, we’ll use a Timescale Cloud instance. Visit Timescale Cloud and set up your instance to get started.
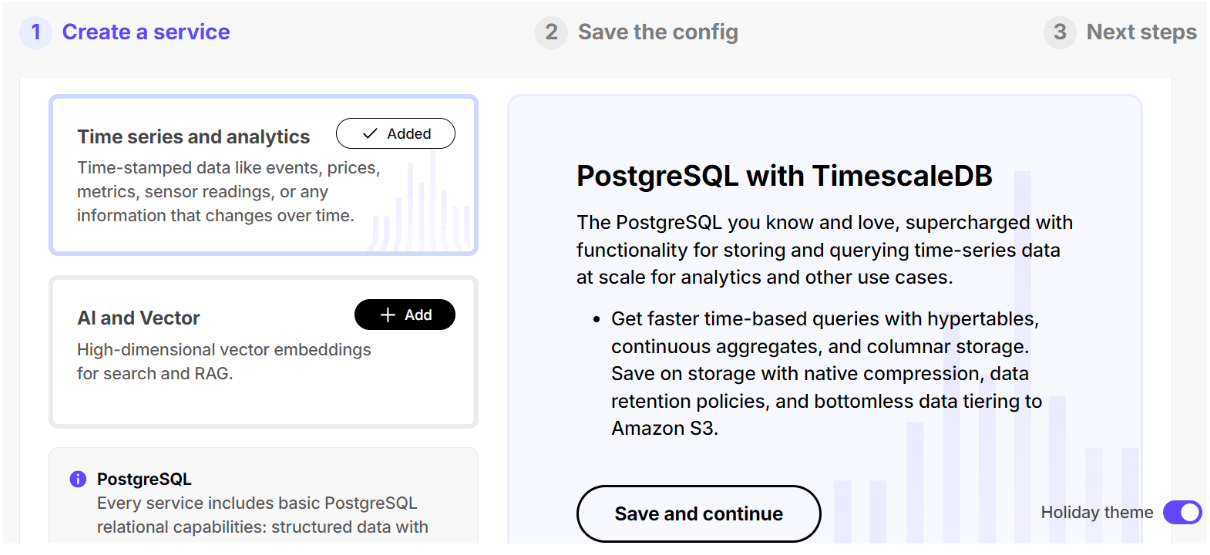
Make sure to enable the AI and vector options, then create the service.
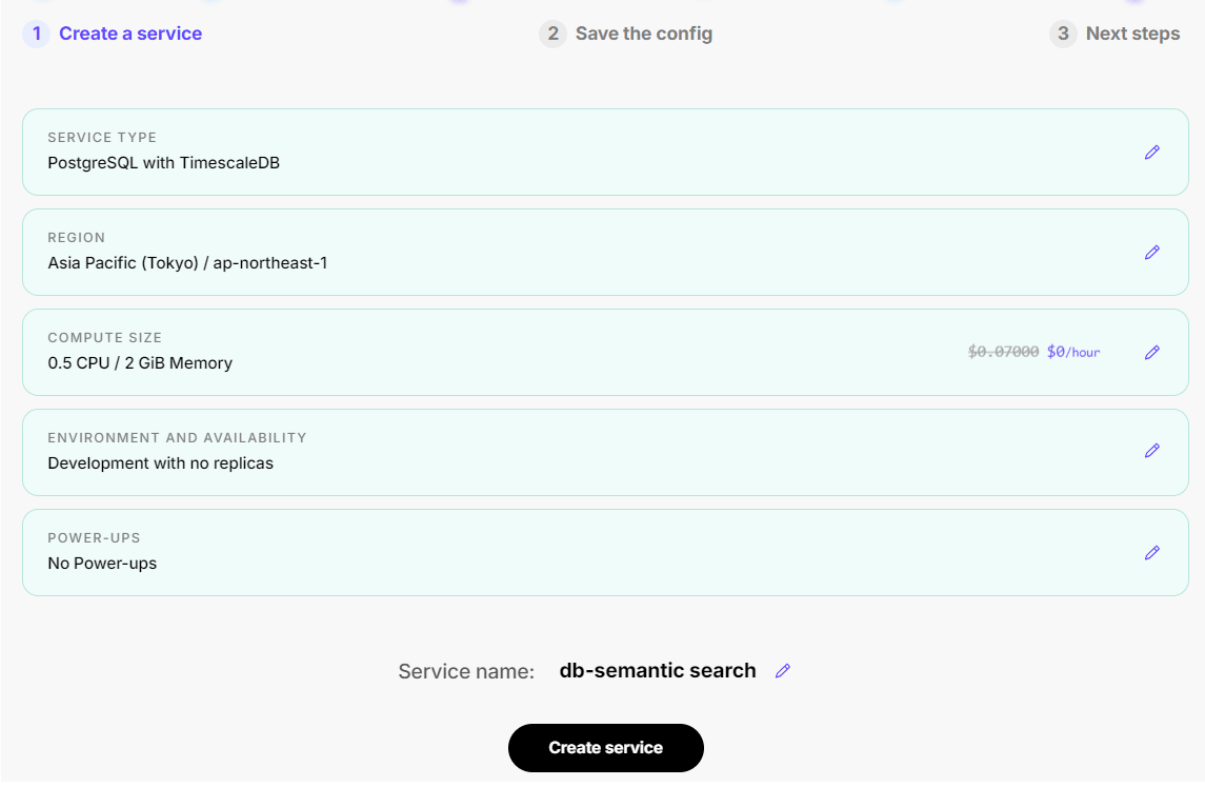
Once the instance is up and running, retrieve your credentials from the page.
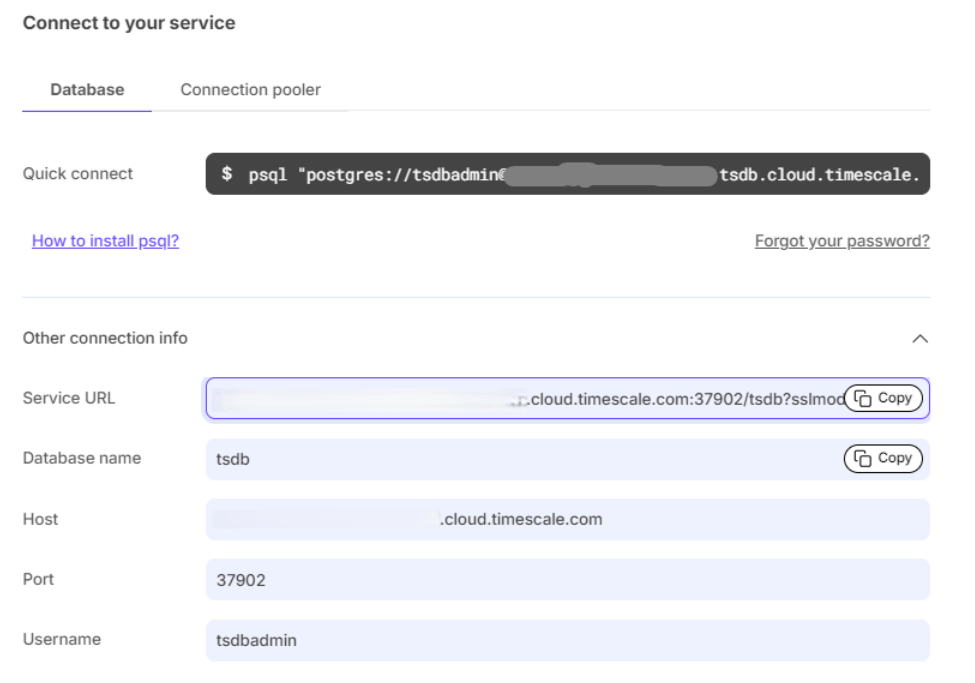
Now, establish the client connection.
conn = psycopg2.connect(DATABASE_CONNECTION_STRING)You’ll need to enable the extensions to start working with pgvector and pgai.
def setup_database():
   pgvector = """CREATE EXTENSION IF NOT EXISTS vector"""
   pgai = """CREATE EXTENSION IF NOT EXISTS ai CASCADE"""
   pgvectorscale = """CREATE EXTENSION IF NOT EXISTS vectorscale CASCADE"""

   with conn.cursor() as cursor:
      cursor.execute(pgvector)
      cursor.execute(pgvectorscale)
      cursor.execute(pgai)

setup_database()
Create the database table using the following SQL query:
CREATE TABLE IF NOT EXISTS movies (
    id bigint primary key generated by default as identity,
    title TEXT NOT NULL,
    overview TEXT,
    genres TEXT,
    producer TEXT,
    "cast" TEXT
);
We’ll be using the Cohere Movies dataset. To load the dataset, we can simply use the load_dataset utility provided by pgai, which allows you to load datasets from Hugging Face's datasets library directly into your PostgreSQL database.
# Use ai.load_dataset to load the dataset
with conn.cursor() as cur:
    # Load the 'movies' dataset from Hugging Face
    cur.execute("""
        SELECT ai.load_dataset(
            name => 'Cohere/movies',
            table_name => 'movies',
            if_table_exists => 'drop',
            field_types => '{"title": "TEXT", "overview": "TEXT", "genres": "TEXT", "producer": "TEXT", "cast": "TEXT"}'::jsonb
        );
    """)
    conn.commit()

print("Dataset loaded successfully into the 'movies' table.")
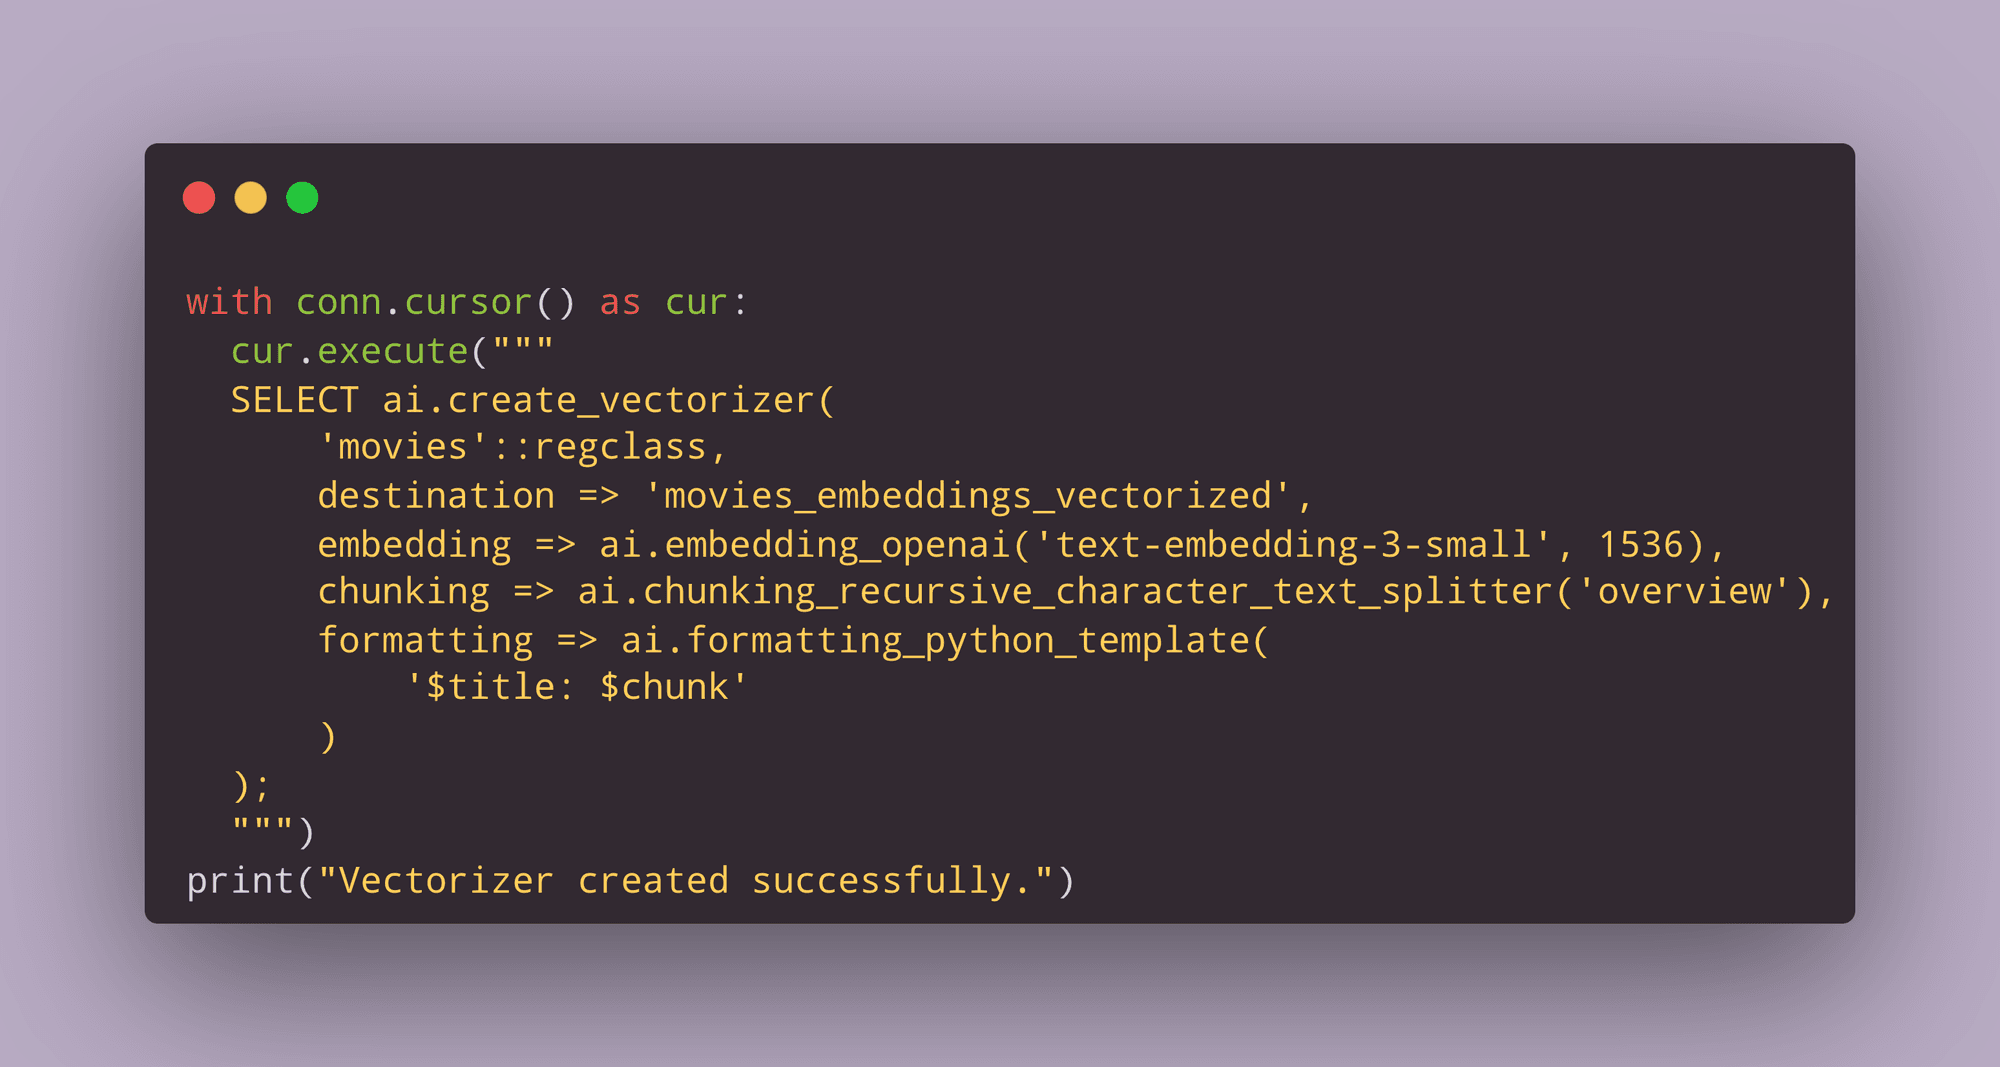
We will also set up pgai Vectorizer to automatically generate embeddings using OpenAI’s text-embedding-3-small embedding model. Here’s how you can do it:
with conn.cursor() as cur:
  cur.execute("""
  SELECT ai.create_vectorizer(
      'movies'::regclass,
      destination => 'movies_embeddings_vectorized',
      embedding => ai.embedding_openai('text-embedding-3-small', 1536),
      chunking => ai.chunking_recursive_character_text_splitter('overview'),
      formatting => ai.formatting_python_template(
          '$title: $chunk'
      )
  );
  """)
print("Vectorizer created successfully.")
With that, you’re all set to perform a vector search across your new database. You can also visualize the database using your Timescale dashboard.
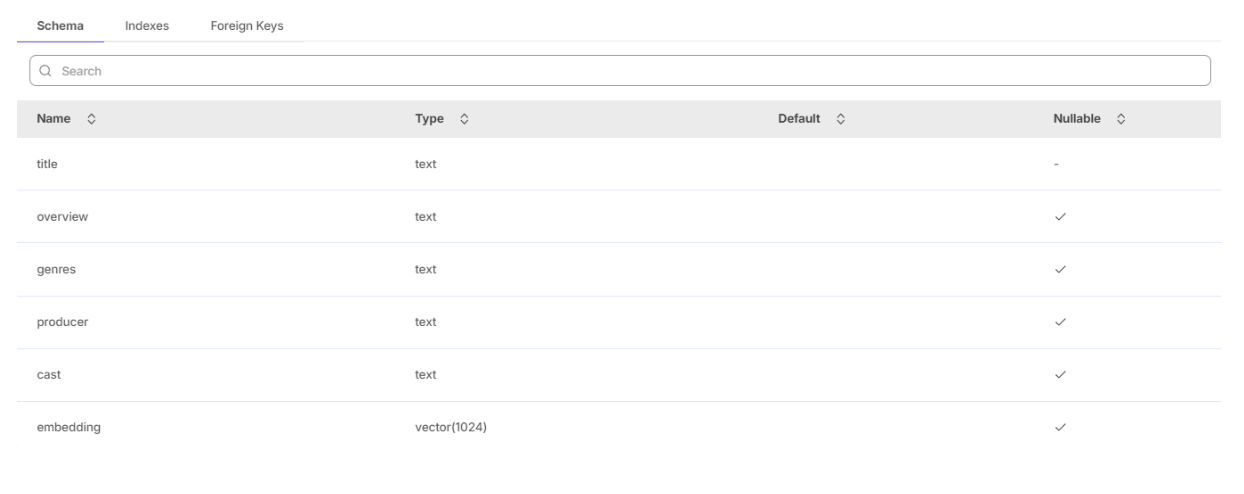
Define the function for performing semantic search.
def semantic_search(conn, query):
    sql = """
    WITH query_embedding AS (
        SELECT openai_embed(
           'text-embedding-3-small'
           , %s
           , _api_key=>%s
       ) AS embedding
    )
    SELECT title, overview
    FROM movies, query_embedding
    ORDER BY movies.embedding <#> query_embedding.embedding
    LIMIT 5
    """
    with conn.cursor() as cur:
        cur.execute(sql, (query,))
        return cur.fetchall()
Here’s a quick walkthrough of what the SQL query is doing:
You can also experiment with other distance functions for similarity searches.
Now, test this function with your custom query.
query = "A thrilling mystery with unexpected twists and turns."
results = semantic_search(conn, query)
[
('Shutter Island',
'World War II soldier-turned-U.S. Marshal Teddy Daniels investigates the disappearance of a patient from a hospital for the criminally insane, but his efforts are compromised by his troubling visions and also by a mysterious doctor.'),
('The Sixth Sense',
'A psychological thriller about an eight year old boy named Cole Sear who believes he can see into the world of the dead. A child psychologist named Malcolm Crowe comes to Cole to help him deal with his problem, learning that he really can see ghosts of dead people.'),
('Angels & Demons',
'Harvard symbologist Robert Langdon investigates a mysterious symbol seared into the chest of a murdered physicist. He discovers evidence of the unimaginable, the rebirth of an ancient secret brotherhood known as the Illuminati, the most powerful underground organization ever to walk the earth.'),
('Gone Girl',
'With his wife's disappearance having become the focus of an intense media circus, a man sees the spotlight turned on him when it's suspected that he may not be innocent.'),
('The Girl with the Dragon Tattoo',
'This English-language adaptation of the Swedish novel by Stieg Larsson follows a disgraced journalist, Mikael Blomkvist, as he investigates the disappearance of a weary patriarch's niece from 40 years ago. He is aided by the pierced, tattooed, punk computer hacker named Lisbeth Salander. As they work together in the investigation, Blomkvist and Salander uncover immense corruption beyond anything they have ever imagined.')
]
That brings us to the end of this tutorial. Here’s a quick recap of what we covered. We learned how to set up pgvector and pgai (with pgai Vectorizer) for our database and how to convert data into embeddings using OpenAI embedding models. Finally, we prepared a query and performed a semantic search on the database—all in under 10 minutes.
Handle all your embedding operations in PostgreSQL—no specialized databases needed. Install pgai Vectorizer and try it yourself (⭐s much appreciated!).
// Related posts
One Postgres table with two indexes beat every published RAG pipeline on MuSiQue. Every architectural addition is a bet the model stays weak.
By Matvey Arye
September 30th, 2026
No fact extraction, no graphs, no memory manager. One Postgres table and three search tools scored F1 0.665 on LoCoMo.
By Matvey Arye
September 29th, 2026
41 experiments in 6 days took LoCoMo memory from F1 0.392 to 0.666. Claude wrote the code; the human caught the metrics that were lying.
By Matvey Arye
September 28th, 2026
Receive the latest technical articles and release notes in your inbox.