A graph benchmarking the DISTINCT query response times with SkipScan vs vanilla PostgreSQL
Hi, I'm James. I work in Developer Advocacy at Timescale. Recently, I’ve been diving deep into performance topics and thinking about the kind of content I enjoy reading and writing. This is a new series that will focus on using data visualizations to spotlight single concepts in Timescale or PostgreSQL performance. No marketing fluff, no unrealistic benchmarks, just straightforward explorations of performance topics I find interesting, with some notes on why I think they matter.
The Introduction: DISTINCT Queries in PostgreSQL
Let’s say you’re working with sensor data in PostgreSQL, with each reading containing a sensor ID, timestamp, and value. You want to power an application dashboard that needs to know the last known state of each sensor in your fleet. Your query might look like this:
SELECT DISTINCT ON (sensorid) *
FROM sensors
ORDER BY sensorid, ts DESC;
The DISTINCT ON clause ensures only one record per sensor is selected, and because the query is ordered by descending timestamp, you’ll get the latest reading for each sensor (although you could also use a WHERE clause to get the latest value at another point in time). Simple enough, right?
In practice, this query pattern can be inefficient, even with proper indexing. In this post, I’ll explain why and walk through a benchmark demonstrating that TimescaleDB’s SkipScan can optimize this query by an astonishing 10,548x at p50 and 9,603x at p95.
💡
This post is about optimizing DISTINCT queries to get the last values associated with an ID quickly, if you want to estimate the cardinality of your dataset (count the unique IDs) then check out the timescaledb-toolkit, which gives you hyperloglog
SkipScan Details
SkipScan is one of those TimescaleDB features that flies under the radar but provides impressive performance improvements—especially given it works with both Timescale’s hypertables and standard PostgreSQL tables (although not currently on compressed hypertables).
As tables and indexes grow, DISTINCT queries slow down in PostgreSQL because it doesn’t natively pull unique values directly from ordered indexes. Even if you have a perfect index in place, PostgreSQL will still scan the full index, filtering out duplicates only after the fact. This approach leads to a significant slowdown as tables grow larger.
SkipScan enhances the efficiency of SELECT DISTINCT ON .. ORDER BY queries by allowing PostgreSQL to directly jump to each new unique value within an ordered index, skipping over intermediate rows. This approach eliminates the need to scan the entire index and then deduplicate, as SkipScan directly retrieves the next distinct value, significantly accelerating query performance. If you're after a deep dive, check out the docs.
We’ve run benchmarks on SkipScan before, but this time, I wanted to see how it interacts in a more realistic environment with ingest and query running at the same time.
The Setup
I set up two Timescale Cloud instances with identical configurations (4 CPUs and 16 GB of memory). On one instance, I disabled SkipScan (SET timescaledb.skip_scan=off), allowing it to default to standard PostgreSQL behavior. The other instance had SkipScan enabled to compare performance.
I created an empty test table using the following SQL (and without any TimescaleDB-specific features):
CREATE TABLE sensors (
  sensorid TEXT,
  ts TIMESTAMPTZ,
  value FLOAT8);

CREATE UNIQUE INDEX ON sensors (sensorid, ts DESC);
Using Grafana K6 (with thexk6-sqlextension), I ran the following test for twenty minutes:
Data ingest: Ingest ran at a target rate of 200K rows per second, using INSERT to ingest data from 1000 sensors, in batches of 1000, with up to 10 concurrent workers (watch this space for a deep dive into the performance of different PostgreSQL INSERT patterns coming soon).
Query load: A SELECT DISTINCT ON query, running 10 times per second with up to 5 concurrent workers. This query pulls the latest reading for all 1000 sensors, simulating an application's needs.
You'll remember the query from earlier:
SELECT DISTINCT ON (sensorid) *
FROM sensors
ORDER BY sensorid, ts DESC;
If you’d like to recreate the benchmark, then check out the GitHub repository for the series.
The Results: SkipScan vs. Vanilla PostgreSQL
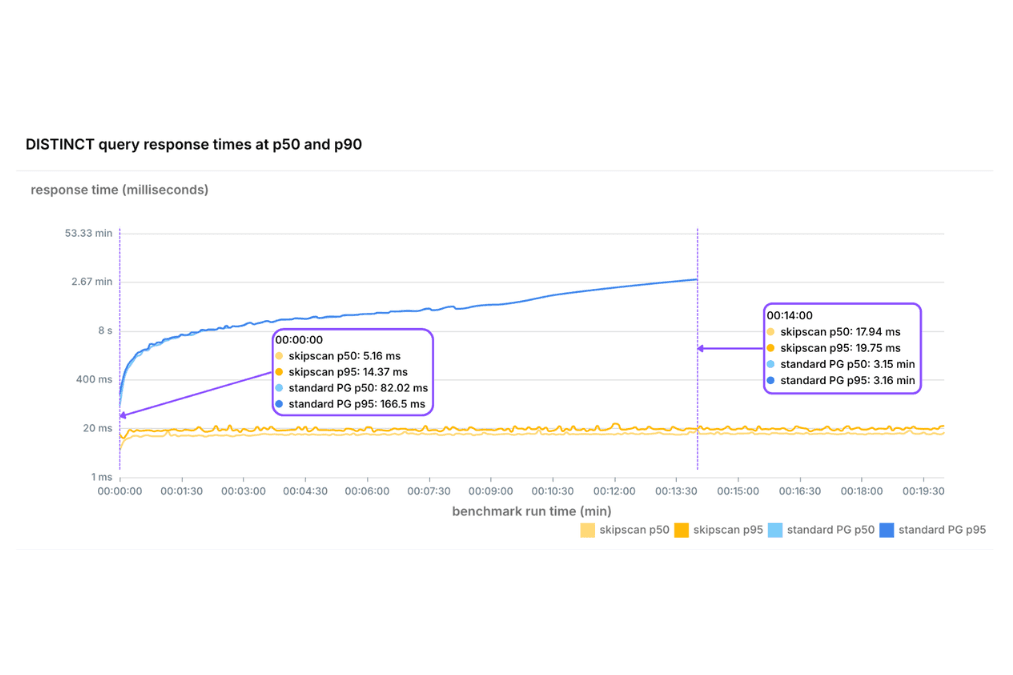
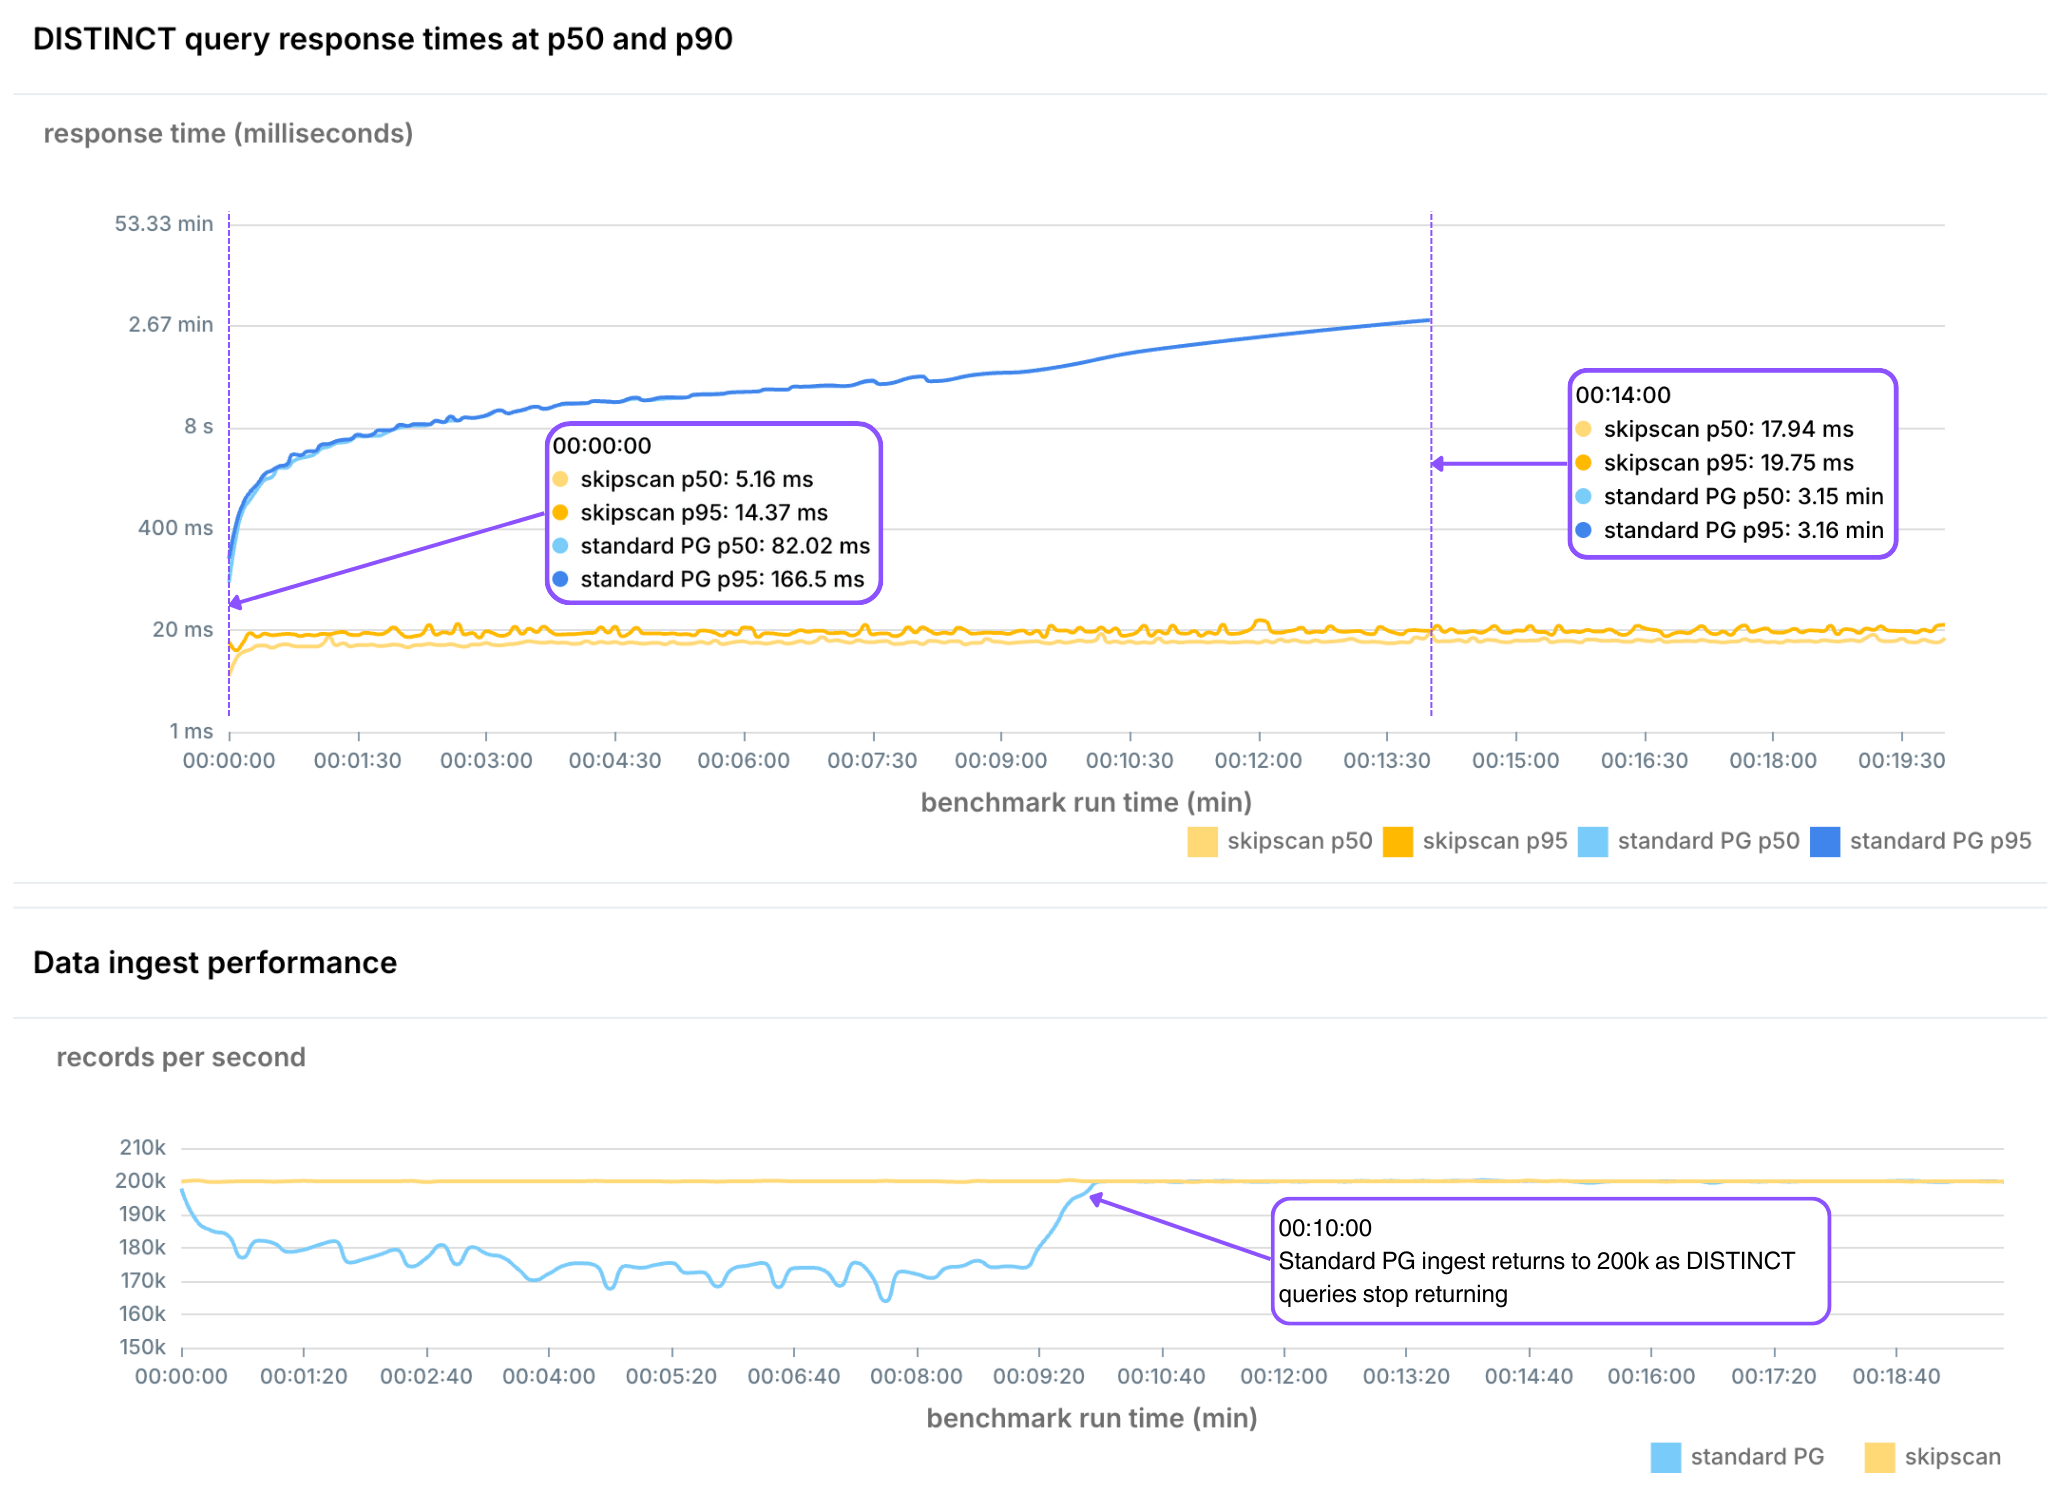
The graphs speak for themselves (please note the X axis in the query graph is a logarithmic scale), but here's a summary:
The standard PostgreSQL server started ingesting 13 % slower and couldn’t sustain the 200K/second goal (it only caught up as DISTINCT14-minute queries stopped returning).
SkipScan performed over11x faster at p50 and p95 right from the start.
By the 14-minute mark, SkipScan was 10,548x faster at p50 and 9,603x faster at p95 than standard PostgreSQL.
SkipScan maintained stable performance throughout the run, while PostgreSQL didn’t return any results after 14 minutes (RIP your dashboard).
If you’d like to interact with the data then you can check out this PopSQL dashboard.
The Conclusion
SkipScan is a pretty remarkable feature, transforming underperforming DISTINCT queries into highly efficient operations. While there has been some discussion on adding it to PostgreSQL, TimescaleDB has your back today. Because SkipScan is not limited to hypertables, it benefits regular PostgreSQL tables as well, giving developers a performance boost just by adding the TimescaleDB extension.
In environments where you need fast, up-to-date insights—like the dashboard example with sensor data—SkipScan lets you keep pace without sacrificing performance. It’s one of those “small but mighty” features that often goes unnoticed but has an outsized impact on real-time analytics workloads.
PostgreSQL write amplification explained: why indexes multiply WAL volume, how to measure it on your tables, and four ways to reduce it without schema changes.
Why a 40-Year-Old Database Is Still Winning in the AI Era
Why Postgres wins in the AI era: 40 years of reliability, extensibility, and an open ecosystem. Agents need trusted foundations, not fragile architectures.
Time-Series Cardinality: Why One More Indexed Column Costs More Than a Million More Rows
Time-series cardinality benchmark: one new indexed column costs 29× more than 1M new rows. Solve with metadata tables and avoid the planner estimation cliff.