We're excited to announce Timescale Analytics, a new project focused on combining all of the capabilities SQL needs to perform time-series analytics into one Postgres extension. Learn about our plans, why we're announcing them now, and ways to contribute your feedback and ideas.
At Timescale, our mission is to enable every software developer to store, analyze, and build on top of their time-series data so that they can measure what matters in their world: IoT devices, IT systems, marketing analytics, user behavior, financial metrics, and more. To this end, we’ve built a petabyte-scale, time-series database.
Today, we’re excited to announce the Timescale Analytics project, an initiative to make Postgres the best way to execute critical time-series queries quickly, analyze time-series data, and extract meaningful information. SQL is a powerful language (we're obviously big fans ourselves), and we believe that by adding a specialized set of functions for time-series analysis, we can make it even better.
The Timescale Analytics project aims to identify, build, and combine all of the functionality SQL needs to perform time-series analysis into a single extension.
In other words, the Timescale Analytics extension will be a "one-stop shop" for time-series analytics in PostgreSQL, and we're looking for feedback from the community: what analytical functionality would you find most useful?
We believe that it is important to develop our code in the open and are requiring radical transparency of ourselves: everything about this project, our priorities, intended features, trade-off discussions, and (tentative) roadmap, are available in our GitHub repository.
It is our hope that working like this will make it easier for the community to interact with the project and allow us to respond quickly to community needs.
To this end, we’re announcing the project as early as possible, so we can get community feedback before we become too invested in a single direction. Over the next few weeks, we’ll be gathering thoughts on initial priorities and opening some sample PRs. Soon after that, we plan to create an initial version of the Timescale Analytics extension for you to experiment with.
Here are some examples of analytics functions we are considering adding: monotonic counters, tools for graphing, statistical sketching, and pipelining.
Monotonic Counters
A monotonically increasing counter is a type of metric often used in time-series analysis. Logically, such a counter should only ever increase, but the value is often read from an ephemeral source that can get reset back to zero at any time (due to crashes or other similar phenomena). To analyze data from such a source, you need to account for these resets: whenever the counter appears to decrease, you assume a reset occurred, and thus, you add the value after the reset to the value immediately prior to the reset.
Assume we have a counter that measures visitors to a website. If we were running a new marketing campaign focused on driving people to a new page on our site, we could use the change in the counter to measure the success of the campaign. While this kind of analysis can be performed in stock SQL, it quickly becomes unwieldy.
Using native SQL, such a query would look like:
SELECT sum(counter_reset_val) + last(counter, ts) - first(counter, ts) as counter_delta
FROM (
    SELECT *,
        CASE WHEN counter - lag(counter) OVER (ORDER BY ts ASC) < 0
            THEN lag(counter) OVER (ORDER BY ts ASC)
            ELSE 0
        END as counter_reset_val
    FROM user_counter
) f;
This is a relatively simple example, and more sophisticated queries are even more complicated.
SELECT delta(counter_agg(counter, ts)) as counter_delta FROM user_counter;
There are many examples like this: scenarios where it’s possible to solve the problem in stock SQL, but the resulting code is not exactly easy to write, nor pretty to read.
We believe we can solve that problem and make writing analytical SQL as easy as any other modern language.
Tools for Graphing
When graphing time-series data, you often need to perform operations such as change-point analysis, downsampling, or smoothing. Right now, these are usually generated with a front-end service, such as Grafana, but this means the graphs you use are heavily tied to the renderer you’re using.
Moving these functions to the database offers a number of advantages:
Users can choose their graphing front-end based on how well it does graphing, not on how well it does data analytics
Queries can remain consistent across all front-end tools and consumers of your data
Doing all the work in the database involves shipping a much smaller number of data points over the network
Key to getting this project working is building the output formats that will work for a variety of front-ends and identifying the necessary APIs. If you have thoughts on the matter, please hop on our discussion threads.
A fully worked-out pure-SQL example of a downsampling algorithm is too long to include inline here (for example, a worked-through version of largest-triangle-three-buckets can be found in this blog post) – but with aggregate support could be as simple as:
SELECT lttb(time, value, num_buckets=>500) FROM data;
This could return a timeseries data type, which could be ingested directly into a tool like Grafana or another language, or it could be unnested to get back to the time-value pairs to send into an external tool.
These tools can then use the simplified query instead of doing their own custom analysis on your data.
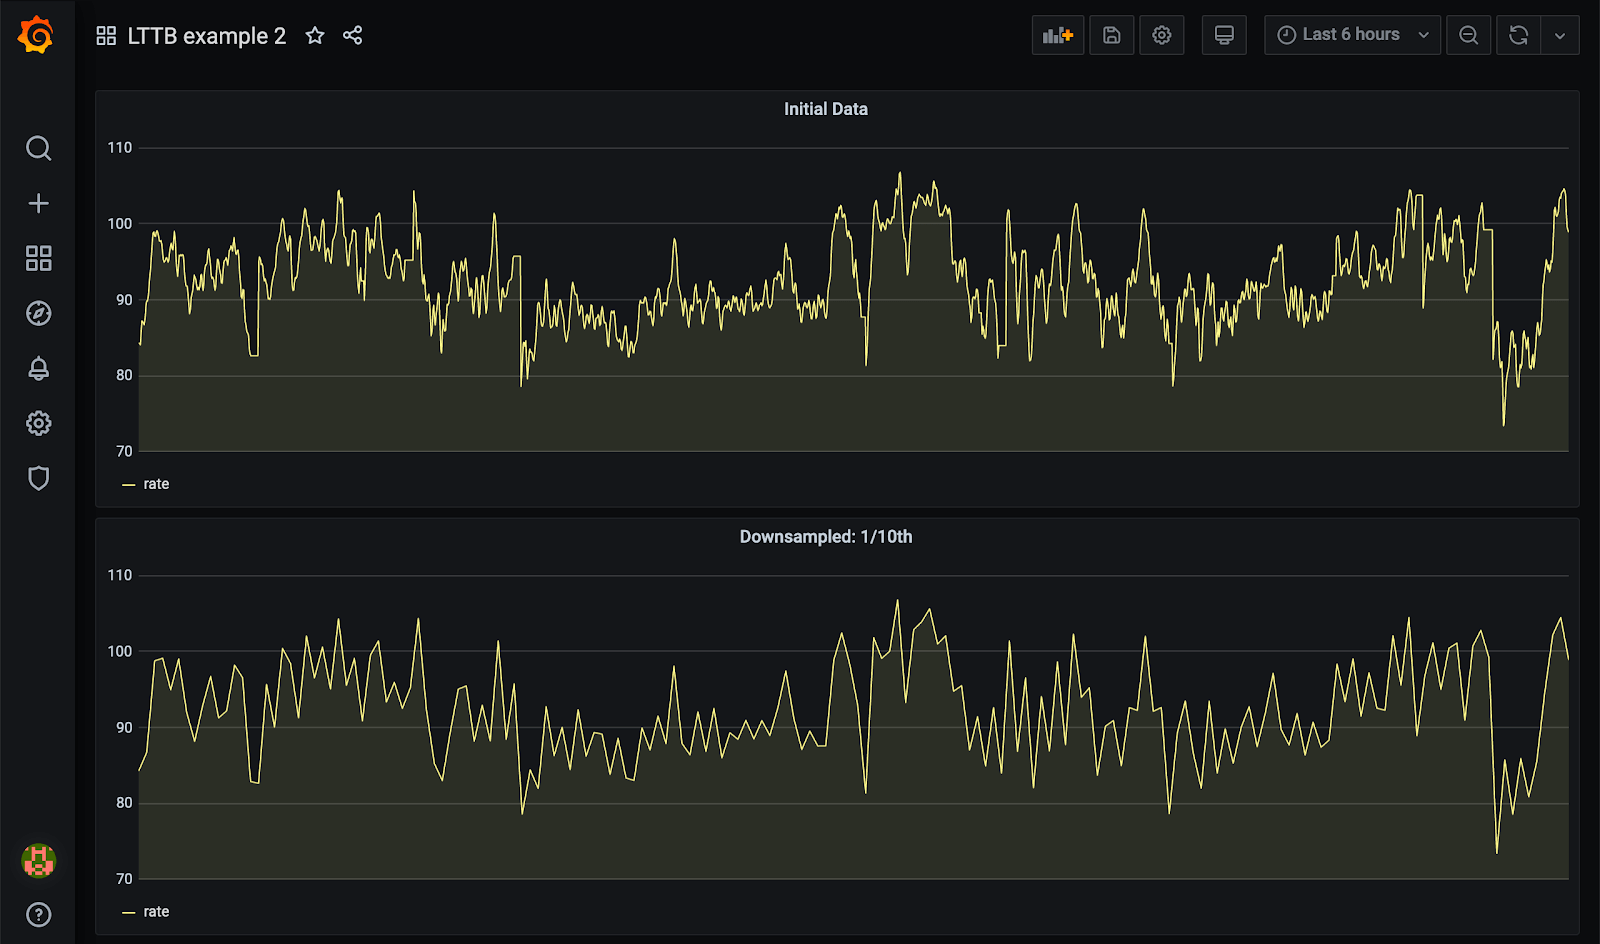
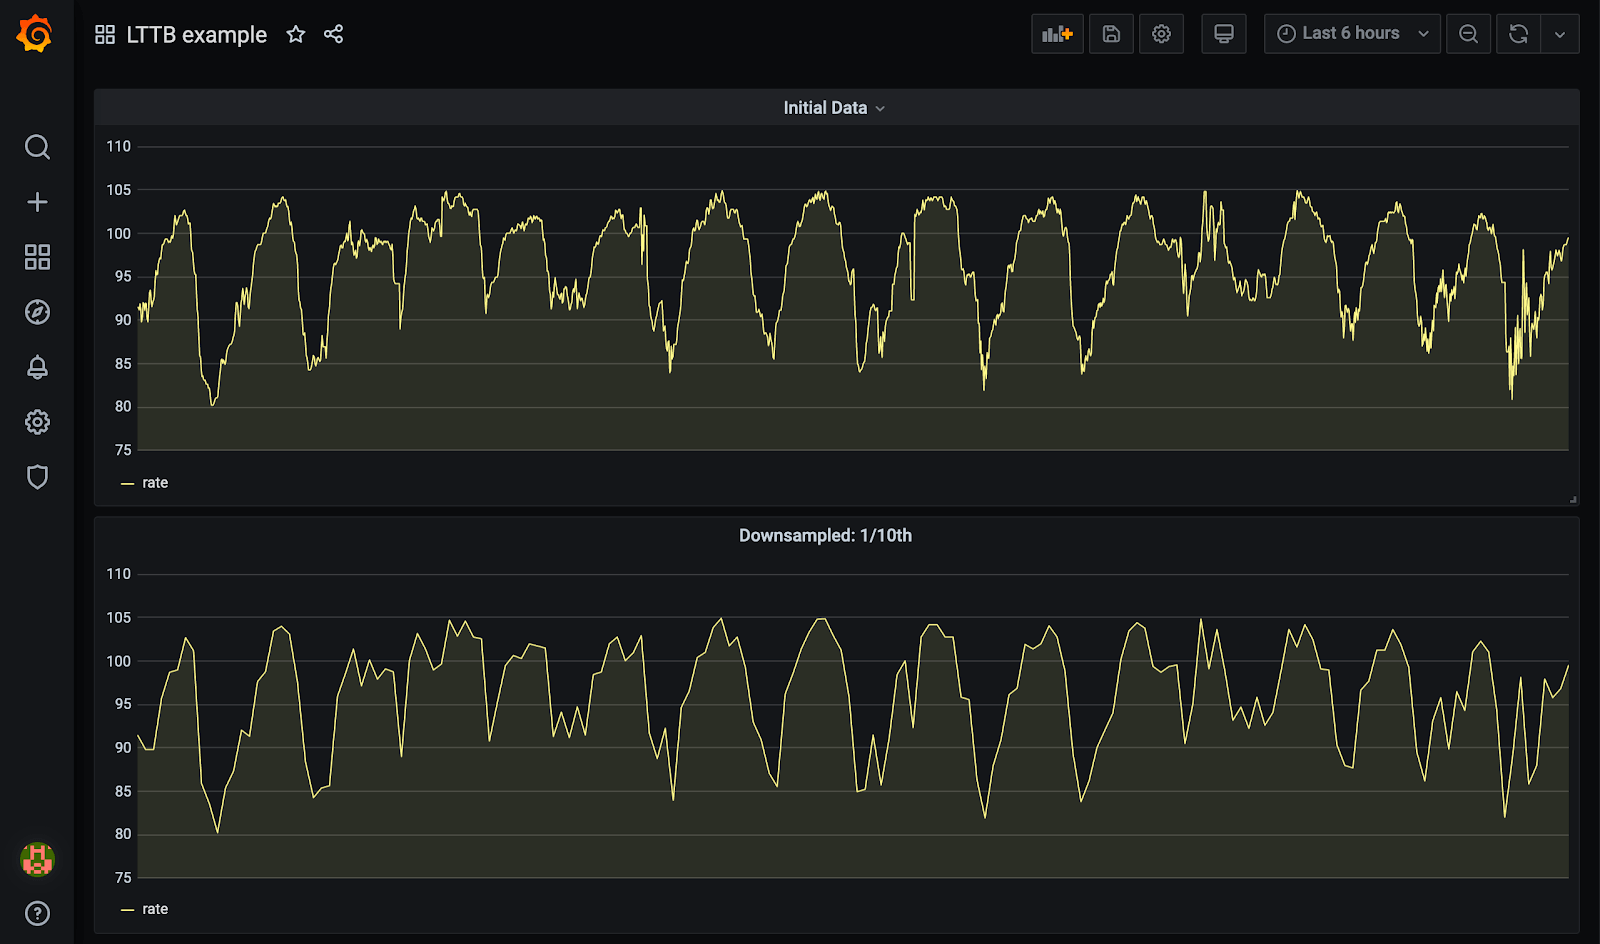
Example downsampling data from this dataset. It keeps the large-scale features of the data, with an order of magnitude fewer data points
Statistical Sketching
Sketching algorithms, such as t-digest, hyperloglog, and count-min, allow us to get a quick, approximate, answer for certain queries when the statistical bounds provided are acceptable.
This is even more exciting in the TimescaleDB ecosystem since it appears most of these sketches will fit nicely into continuous aggregates, allowing incredibly low query latency.
For instance, a continuous aggregate displaying the daily unique visitors to a website could be defined like:
CREATE MATERIALIZED VIEW unique_vistors
WITH (timescaledb.continuous) AS
    SELECT
    time_bucket('1 day', time) as day,
    hll(visitor_id) as visitors
    FROM connections
    GROUP BY time_bucket('1 day', time);
Such a view could be queried to get the visitors over range of days, like so:
SELECT day, approx_distinct(visitors)
FROM unique_vistors
WHERE day >= '2020-01-01' AND day >= '2020-01-15'
Additionally, it would allow for re-aggregation to determine the number of unique visitors over a coarser time range, such as the number of monthly visitors:
SELECT time_bucket(day, '30 days'), approx_distinct(hll(visitors))
FROM unique_vistors
GROUP BY time_bucket(day, '30 days')
Pipelining
SQL queries can get long, especially when there are multiple layers of aggregation and function calls.
For instance, to write a pairwise delta at minute-granularity in TimescaleDB, we’d use something like:
SELECT minutes, sampled - lag(sampled) OVER (ORDER BY minutes) as delta
FROM (
    SELECT
        time_bucket_gapfill(time, '1 minute') minutes,
        interpolate(first(value, time)) sampled
    FROM data
    GROUP BY time_bucket_gapfill(time, '1 minute')
) interpolated;
To mitigate this, the Timescale Analytics proposal includes a unified pipeline API capability that would allow us to use the much more straightforward (and elegant) query below:
Besides the simpler syntax, this API could also enable some powerful optimizations, such as incremental pipelines, single-pass processing, and vectorization.
This is still very much in the design phase, and we’re currently having discussions about what such an API should look like, what pipeline elements are appropriate, and what the textual format should be.
How we’re building Timescale Analytics
We’re building Timescale Analytics as a PostgreSQL extension. PostgreSQL's extension framework is quite powerful and allows for different levels of integration with database internals.
Timescale Analytics will be separate from the core TimescaleDB extension. This is because TimescaleDB core interfaces quite deeply into PostgreSQL’s internals— including the planner, executor, and DDL interfaces—due to the demands of time-series data storage. This necessitates a certain conservatism to its development process in order to ensure that updating TimescaleDB versions cannot damage existing databases, and that features interact appropriately with PostgreSQL’s core functionality.
By separating the new analytics functionality into a dedicated Timescale Analytics extension, we can vastly reduce the contact area for these new functions, enabling us to move faster without increased risk. We will be focusing on improvements that take advantage of the PostgreSQL extension hooks for creating functions, aggregates, operators, and other database objects, rather those that require interfacing with the lower-level planning and execution infrastructure. Creating a separate extension also allows us to experiment with our build process and technologies, for instance, writing the extension in Rust.
More importantly, we hope using a separate extension will lower barriers for community contributions. We know that the complexity of our integrations with PostgreSQL can make it difficult to contribute to TimescaleDB proper. We believe this new project will allow for much more self-contained contributions by avoiding projects requiring deep integration with the PostgreSQL planner or executor.
So, if you’ve been wanting to contribute back but didn’t know how or are a Rustacean looking to get involved in databasing, please join us!
Get Involved
Before the code is written is the perfect time to have a say in where the project will go. To this end, we want—and need—your feedback: what are the frustrating parts of analyzing time-series data? What takes far more code than you feel it should? What runs slowly or only runs quickly after seemingly arcane rewrites?
We want to solve community-wide problems and incorporate as much feedback as possible, in addition to relying on our intuition, observation, and experiences.
Want to help? You can submit suggestions and help shape the direction in 3 primary ways:
Look at some of the discussions we’re having right now and weigh in with your opinions. Any and all comments are welcome, whether you’re an experienced developer or just learning.
Check out the features we’re thinking of adding, and weigh in on if they’re something you want, if we’re missing something, or if there are any issues or alternatives. We are releasing nightly Docker images of our builds.
Most importantly: share your problems! Tell us the kinds of queries or analyses you wish were easier, the issues you run into, or the workarounds you’ve created to solve gaps. (Example datasets are especially helpful, as they concretize your problems and create a shared language in which to discuss them.)
TimescaleDB 2.27: Broader Vectorized Execution, Up to 160x More Efficient UPDATE/DELETE, and Smarter UPSERT Pruning
Up to 160x more efficient UPDATE/DELETE, 30% to 2x faster vectorized execution, and skip unnecessary decompression + compression. Here's what's new in TimescaleDB 2.27.