In this tutorial, you’re going to build a pipeline for ingesting manufacturing IoT sensor data into TimescaleDB and running analytical queries to understand equipment performance.
You’ll see how TimescaleDB’s hypertables and hypercore storage helps you solve one of the hardest challenges in modern manufacturing:
Managing massive streams of machine sensor data — and still querying it fast enough to make decisions.
This tutorial assumes you already have a Tiger Cloud account with available services and have installed a postgreSQL client for your terminal. If not, please read the documentation here, and begin a 30-day free trial here.
Create a New Service
When you create a new service, Tiger automatically optimizes storage, compute, partitioning, and compression behind the scenes based on the workload you choose. Here is the configuration we recommend for this tutorial.
SERVICE TYPE
Since we’ll be ingesting real-time sensor data from machines, choose Real-time analytics.
This gives you fast ingestion and high-performance queries — the two pillars of IoT time-series work.
CLOUD AND REGION
Choose your preferred cloud provider and a location close to you. For this tutorial, we’ll choose AWS and US East (Ohio).
Note: The cloud provider and region cannot be changed later.
COMPUTE SIZE
Manufacturing IoT data gets big fast. On a free trial, you may as well select something generous, so choose 8 CPU / 32 GiB Memory.
You can always scale down later if you want.
ENVIRONMENT AND AVAILABILITY
For this tutorial, we are not dealing with production-critical data, so we’ll choose Development and No Replica.
For real production deployments, Tiger supports high availability (HA) replication and regular backups for disaster recovery (DR).
CONNECTIVITY
This tutorial does not cover connectivity power-ups, so we will skip these.
SERVICE NAME
Let’s use something meaningful, like factory-iot-pipeline.
Press Create service. Tiger will now begin provisioning your Postgres + TimescaleDB service.
Save Credentials
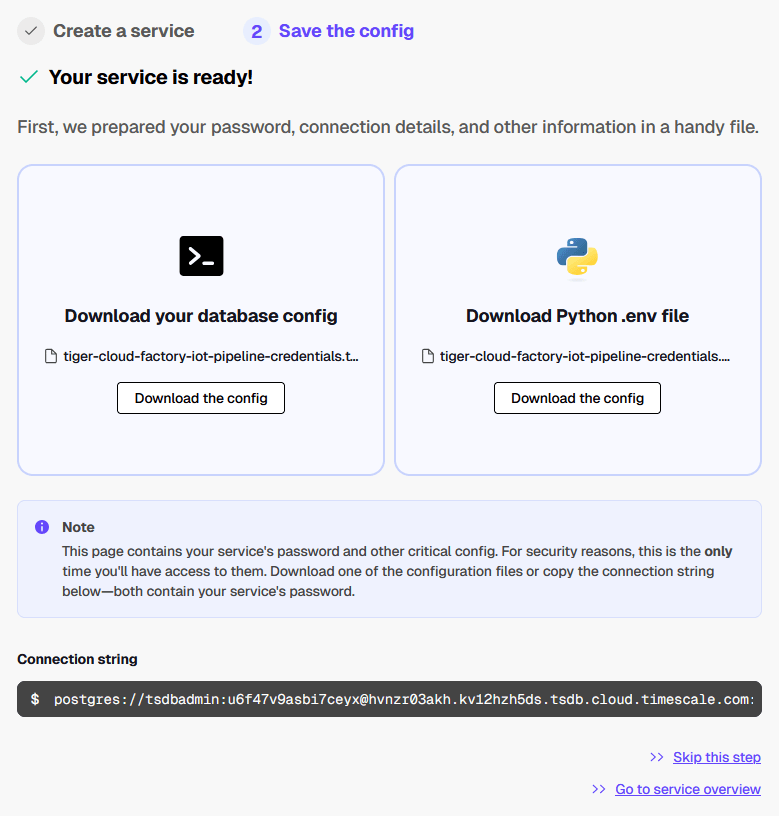
While Tiger prepares your service, you’ll see the connection credentials on your screen.
This contains critical information for connecting to your service, and for security, this is the only time they will ever be shown.
Download the configuration file (.txt or .env) and store it somewhere safe.
Finish Setup
You may be asked what you intend to do with your service. For this tutorial, choose:
I am planning to evaluate database performance with my new application (I want to test ingest performance).
This will unlock Tiger Data feature recommendations that are most relevant to IoT workloads.
Now let’s get into the fun part: ingestion and analysis.
Log Into Database
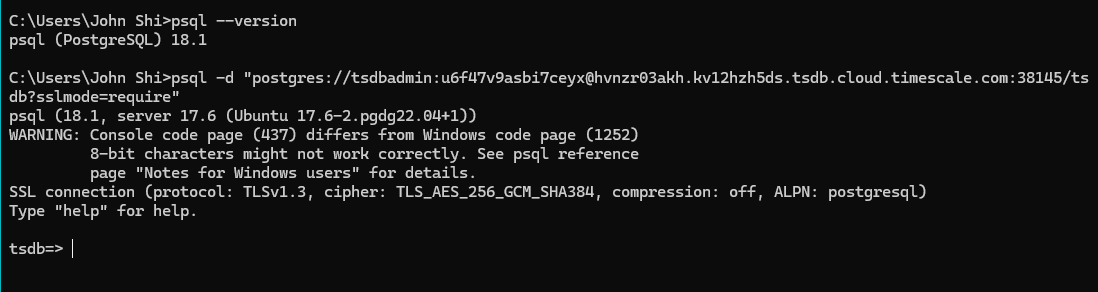
We will connect to the database service through a terminal using the connection string found in the credential file from Step 2.
Time to create your first TimescaleDB hypertable—the foundation of everything you’ll do in IoT analytics.
The temperature sensors we are gathering data from are identified by the id of the machine they’re on and their own specific id. The temperature readings are given as a double precision floating point number and a string indicating the quality of the measurement.
To create this table, paste the following string into your psql terminal:
CREATE TABLE sensor_readings (
    time TIMESTAMPTZ NOT NULL,
    machine_id INTEGER NOT NULL,
    sensor_id INTEGER NOT NULL,
    value DOUBLE PRECISION,
    quality TEXT,
    PRIMARY KEY (time, machine_id, sensor_id)
) WITH (
    tsdb.hypertable,
    tsdb.partition_column = 'time',
    tsdb.orderby = 'time DESC'
);
The primary key is defined to ensure that the same sensor cannot duplicate readings and to improve queries that return values for a specific sensor at a specific time.
The terms in the WITH statement indicate to TimescaleDB that this table should be treated as a hypertable, with partitioning on the time column.
You’ll see CREATE TABLE once the table has been created.
To verify the table was created, issue the following command:
\d sensor_readings
You now have an empty hypertable optimized for IoT time-series workloads.
Ingest Sensor Data into TimescaleDB
Normally, you would now connect your devices by translating the sensor readings into an SQL INSERT Query.
For example, if we had 3 readings from machine 1, the insert query might look like this:
INSERT INTO sensor_readings (time,machine_id,sensor_id,value,quality)
VALUES
	(Now(),1,1,105.1,'good'),
     (Now(),1,2,104.9,'good'),
	(Now(),1,3,104.2,'good');
Copy and paste the above query into the terminal. The result should be INSERT 0 3, indicating that 3 rows were created.
In order to better illustrate the power of hypertables, we’re going to clear the table and insert a large amount of simulated data. Specifically, we will simulate 20 machines, with 5 sensors each generating random values every minute for the past month.
TRUNCATE TABLE sensor_readings;
INSERT INTO sensor_readings
SELECT time, machine_id, sensor_id,
	random()*(100-50)+50 AS temperature,
	(ARRAY['good','good','bad'])[floor(random()*3)+1] AS status
FROM generate_series(now() - INTERVAL '1 month',now(), INTERVAL '1 minute') AS time,
generate_series(1,20) AS machine_id,
generate_series(1,5) AS sensor_id;
This should take less than a minute and add almost 4.5 million rows to the table.
Enable Hypercore Compression
It doesn’t take long before the storage requirements can become overwhelming.
A common method to address this is to split the data into two groups:
Recent, uncompressed data for high speed ‘hot’ queries
Older, compressed data for historical queries
TimescaleDB’s hypercore storage makes this easy.
Enable compression on this table with the following:
ALTER TABLE sensor_readings
SET (
  timescaledb.compress,
  timescaledb.compress_orderby = 'time',
  timescaledb.compress_segmentby = 'machine_id'
);
This will dramatically reduce the storage requirements for the data, while keeping some data uncompressed for fast retrieval.
To view the current compression policies, enter the following query:
SELECT hypertable_name,schedule_interval,config FROM timescaledb_information.jobs WHERE proc_name='policy_compression';
Depending on how your Tiger Cloud instance is setup, the output should look like the following:
This specific table is set to run the compression each day and compress all data older than 7 days.
If no compression policy is present, or you want to make changes to the policy, consult the documentation here. All compression is done “behind the scenes” and will be transparent to all queries.
Write Analytical Queries
Let’s try running some queries to retrieve analytics your manufacturing teams may need. These can either be run in the terminal, or through the ‘SQL editor’ tab in Tiger Cloud.
Query 1: Number of readings per machine
SELECT
    machine_id,
    COUNT(*) AS readings
FROM sensor_readings
WHERE time > now() - INTERVAL '1 week'
GROUP BY machine_id
ORDER BY machine_id;
This style of query could help you understand which machines have produced the highest volume of data.
Query 2: Worst quality sensors over the past day
SELECT
    machine_id,
    sensor_id,
    COUNT(*) AS bad_readings
FROM sensor_readings
WHERE time > now() - INTERVAL '1 day' AND quality='bad'
GROUP BY machine_id,sensor_id
ORDER BY bad_readings DESC
LIMIT 5;
This style of query could help determine which sensors are malfunctioning the most and help prioritize maintenance.
Query 3: 10 Highest Machine Temperature days
SELECT
    DATE(time_bucket('1 day', time)) AS day,
    machine_id,
    AVG(value) AS avg_temperature
FROM sensor_readings
GROUP BY day, machine_id
ORDER BY avg_temperature DESC
LIMIT 10;
This style of query could help determine which machine is running the hottest, which could indicate process problems.
All three of the above queries process large amounts of data, yet run very quickly. Feel free to experiment with different queries on the dataset and see how powerful TimescaleDB really is.
Conclusion
Congratulations, you’ve built an industrial data pipeline! You now have:
A TimescaleDB service
A hypertable optimized for time-series
Real IoT sensor data ingested
Hypercore compression enabled
Several baseline analytics queries
With this tutorial, we have shown you the following benefits of TimescaleDB:
Hypertables for massive, parallel ingestion
Hypercore for compressed historical analytics
Chunked storage for predictable performance
Time-bucket queries for industrial analysis
Unified OLTP + OLAP in a PostgreSQL-compatible environment
If you’d like to explore TimescaleDB more, you can simulate more data, connect real devices, and run more complex analytics such as comparing machine outputs and detecting anomalies.
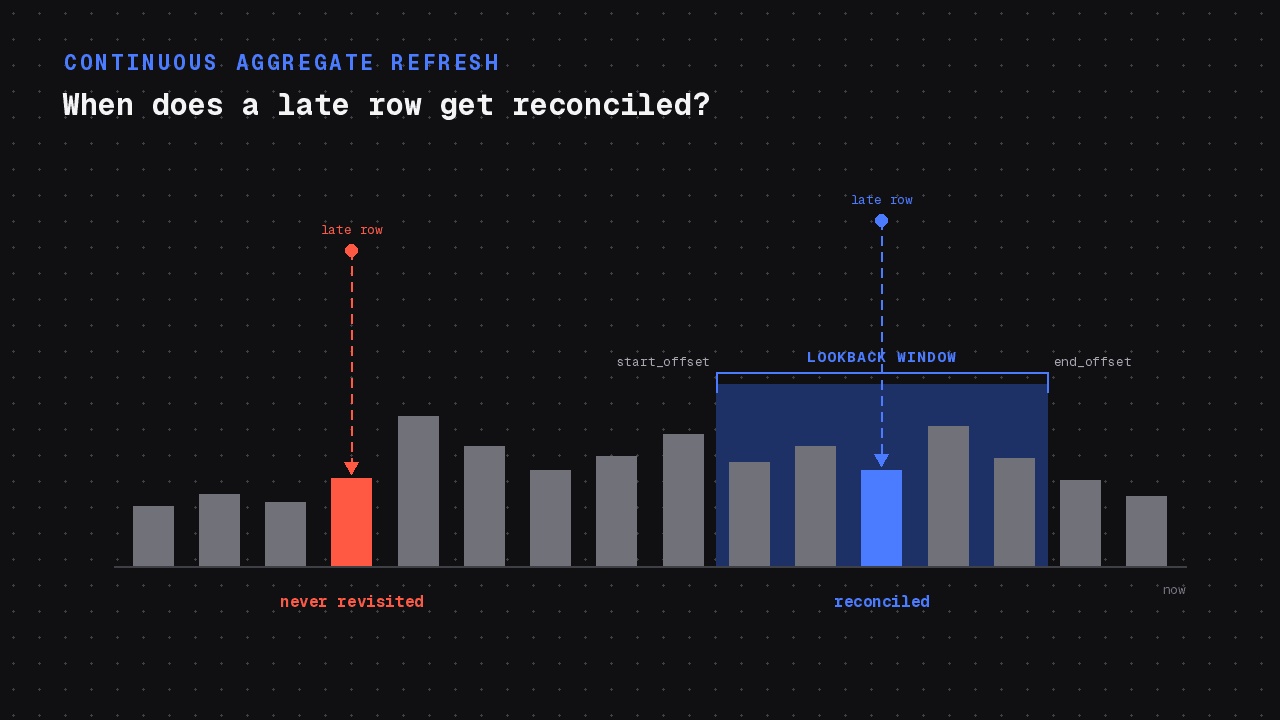
Continuous Aggregate Refresh, Demystified: Invalidation, Lookback, and Late-Arriving Data
TimescaleDB continuous aggregates and late-arriving data: invalidation tracking, lookback windows, and the two offsets that prevent stale aggregate buckets.
How ControlCom Turns 300+ Million Monthly Facility Data Points Into Instant Answers With Tiger Data
Industrial IoT on TimescaleDB: ControlCom streams 1K-10K points/sec from thousands of assets, powering instant dashboards and AI that caught $160K billing errors.
IIoT in Manufacturing: The Data Challenges Behind Industry 4.0 (and How to Solve Them)
IIoT in manufacturing generates high-frequency sensor data most databases can't handle. See the 5 trends, the data-layer fixes, and real customer examples.