Your indexes are perfect, your CPU is healthy, but your p99 latency is spiking. When you look at the logs, you see a standard IN clause fetching data for a few thousand users. It looks harmless, but for high-growth databases, this single query pattern becomes a significant performance burden. This guide explains how switching to ANY(ARRAY[]) reduces query planning time and prevents your query planner from stalling as you scale.
What You Will Learn
Large IN clauses act as a hidden tax on your PostgreSQL database. Passing a massive list of IDs from your application to a query creates a performance bottleneck that simple indexing cannot fix. In this article, you will learn:
The hidden planning tax PostgreSQL pays to parse large lists of constants.
How to implement ANY(ARRAY[...]) as a more efficient alternative for batch lookups.
How to diagnose query planner bottlenecks using EXPLAIN ANALYZE.
Why It Matters
Object-Relational Mappers (ORMs) are the primary culprits behind oversized IN clauses. When an application needs to fetch metadata for a list of 5,000 users, the ORM typically generates a single query like the following example:
SELECT * FROM users WHERE id IN (1, 2, 3, ... 5000)
While this appears to be a standard batch operation, it forces the database to parse each item individually. Large IN lists can cause the query planner to spend more time analyzing the query than executing it. This overhead breaks plan caching, where latency creeps up even without traffic spikes. If you are managing billions of rows, the cost of moving these lists between your application and the database can consume your entire CPU budget.
Parsing vs. Executing
To a developer, an IN clause is just a list. To the PostgreSQL parser, it is a complex expression tree.
When you send a query with 5,000 IDs in an IN clause, the parser must:
Tokenize every single constant in the string.
Assign types to every element (e.g. ensuring they are all integers).
Build a tree node for each item.
This creates a large internal structure that the query planner needs to traverse. In contrast, using an array parameter wraps all 5,000 IDs into a single object. The parser sees one parameter, assigns it one type (int[]), and moves straight to the planning phase. This reduces the memory usage of the query string and prevents the expression tree from becoming unmanageable.
Query Planner Diagnostics
To determine if your IN clauses are hurting performance, you need to look beyond total latency and instead look at a breakdown of your query’s lifecycle. Luckily, most of these diagnostics are available via EXPLAIN ANALYZE.
Identifying the Planning Tax
When running EXPLAIN ANALYZE, pay close attention to the Planning Time. If it exceeds 50% of the total time, the database is struggling to parse your constant list. For example, a query that takes 40 ms to plan but only 2 ms to execute is a prime candidate for refactoring.
Analyzing Scan Types
Check how the engine navigates your data structures within the EXPLAIN output. A standard Index Scan is highly efficient for small IN lists because the overhead of looking up a few individual keys is relatively low. However, as the list grows, the planner typically switches to a Bitmap Index Scan, which is commonly used with the ANY(ARRAY[]) syntax. In this scenario, the database constructs a map of all matching rows in memory before initiating the fetch. This process is far more efficient for large batches than jumping back and forth on an index for 5,000 separate values.
Benchmarking the Planning Tax
To see the performance gains in your own environment, use EXPLAIN (ANALYZE, BUFFERS) to monitor the planning and execution metrics of your queries. These examples demonstrate how to measure the planning tax of a standard IN clause, and the gains you will see with the more efficient ANY(ARRAY[]) pattern, for a typical device_metrics table.
Standard IN Clause
A standard IN clause with 5,000 IDs forces the database to tokenize each element individually, resulting in high Planning Time. The problem is that the parser needs to parse each constant and build a massive expression tree before execution starts.
EXPLAIN (ANALYZE, BUFFERS)
SELECT reading_value
FROM device_metrics
WHERE device_id IN (101, 102, 103, ... 5000);
ANY(ARRAY[])
When you use ANY(ARRAY[]) syntax, you tell PostgreSQL to treat the thousands of IDs as a single object rather than thousands of individual constants. This drastically reduces the query's structural complexity.
EXPLAIN (ANALYZE, BUFFERS)
SELECT reading_value
FROM device_metrics
WHERE device_id = ANY(ARRAY[101, 102, 103, ... 5000]::int[]);
Results
In high-volume environments, moving from the standard IN clause to an array parameter often yields the following improvements:
Planning Time: Can drop from 40+ ms to less than 2 ms.
Memory Usage: Significant reduction in the memory required to store the query string and the resulting expression tree.
Scan Strategy: The planner is more likely to use a Bitmap Index Scan, which fetches data in larger, more efficient batches than individual index lookups.
Next Steps
Switching from a standard IN clause to array parameters can be one of the most impactful changes you can make for database performance. Here are some steps you can take to implement this in your own database.
Enable pg_stat_statements: Ensure this extension is enabled in your shared_preload_libraries to track historical query performance at scale.
SELECT query, calls, mean_exec_time
FROM pg_stat_statements
WHERE query ILIKE '%IN (%'
ORDER BY mean_exec_time DESC LIMIT 5;
Audit ORMs: Check your ORM configuration to see if it supports "Array Mode" to automate the use of the ANY(ARRAY[]) pattern.
Benchmark: EXPLAIN (ANALYZE, BUFFERS) on your largest batch queries. If planning time exceeds 10 ms or 50% of total latency, apply the refactor immediately.
ANY(ARRAY[]) and all these tools come with Tiger Cloud by default. Start a free Tiger Cloud trial today and see these performance benefits for yourself.
PostgreSQL write amplification explained: why indexes multiply WAL volume, how to measure it on your tables, and four ways to reduce it without schema changes.
PostgreSQL table bloat: detect it before it kills performance. Measure heap and index density, set autovacuum thresholds, and alert on dead tuple ratios and vacuum lag.
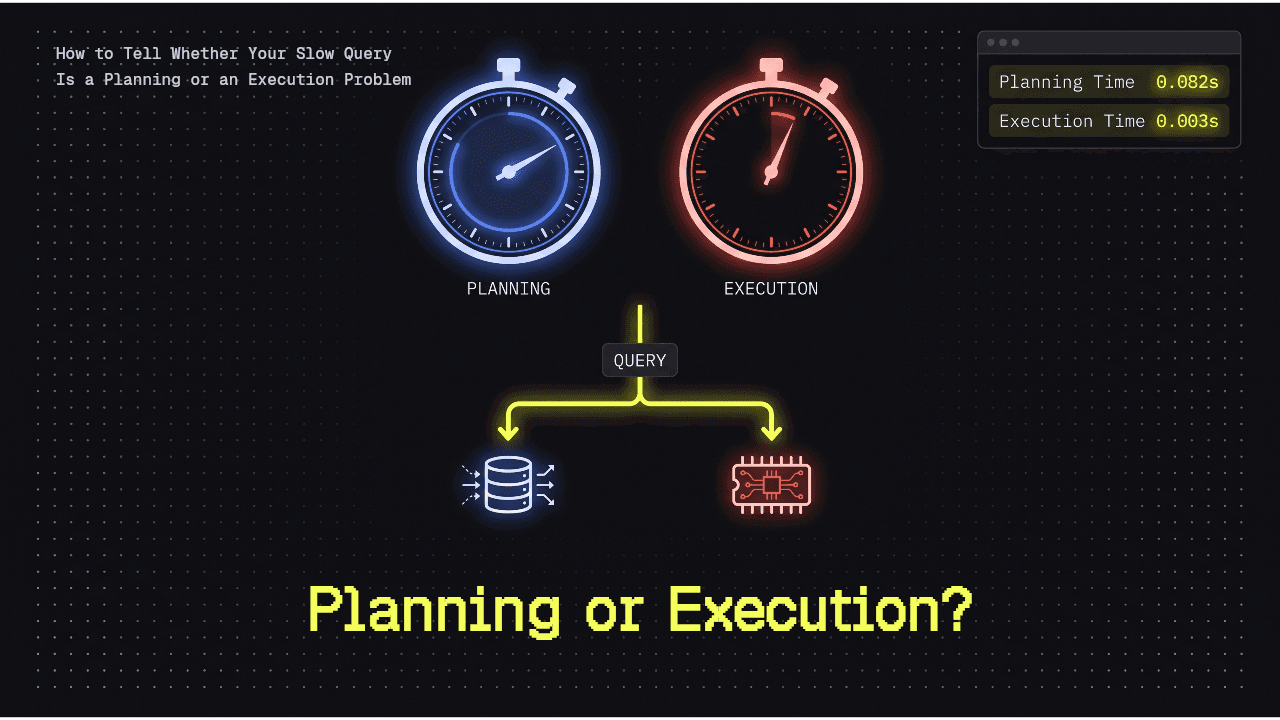
How to Tell Whether Your Slow Query Is a Planning or an Execution Problem
How to tell if your slow Postgres query is a planning or execution problem: read EXPLAIN ANALYZE's Planning Time and Execution Time to diagnose the bottleneck.