TigerData logo
TigerData logo
  • Product

    Product

    Tiger Cloud

    Robust elastic cloud platform for startups and enterprises

    TimescaleDB Enterprise

    Self-managed TimescaleDB for on-prem, edge and private cloud

    Open source

    TimescaleDB

    Time-series, real-time analytics and events on Postgres

    Search

    Vector and keyword search on Postgres

  • Industry

    Data Centers

    Energy & Utilities

    Oilfield Services

    Smart Manufacturing

    Crypto

  • Docs
  • Pricing
  • Developer Hub

    Changelog

    Benchmarks

    Blog

    Community

    Customer Stories

    Events

    Support

    Integrations

    Launch Hub

  • Company

    About

    TigerData logo

    Timescale

    Partners

    Security

    Careers

View on GitHub (opens in a new tab)

Contact usStart a free trial
Home
Tiger MCP vs. a Generic Postgres MCP Server
Time Series Forecasting with PostgreSQL: Methods, SQL Examples, and When to Use PythonTime-Series Analysis and Forecasting With Python Why Consider Using PostgreSQL for Time-Series Data?Time-Series Analysis in RWhat Is Temporal Data?Understanding Autoregressive Time-Series ModelingAlternatives to TimescaleStationary Time-Series AnalysisWhat Are Open-Source Time-Series Databases—Understanding Your OptionsIs Your Data Time Series? Data Types Supported by PostgreSQL and TimescaleUnderstanding Database Workloads: Variable, Bursty, and Uniform PatternsThe Best Time-Series Databases Compared (2026)Time Series Anomaly Detection: Methods, SQL, and Real-Time ImplementationAWS Timestream Alternatives: Your Migration Options After LiveAnalyticsTime-Series Database: What It Is, How It Works, and When You Need OneWhat Is a Time Series and How Is It Used?How to Work With Time Series in Python?Tools for Working With Time-Series Analysis in PythonGuide to Time-Series Analysis in PythonCreating a Fast Time-Series Graph With Postgres Materialized Views
OpenTelemetry Backend: Choosing Metrics Storage That Doesn't Lock You InGPU Cluster Monitoring: The Database Behind AI Infrastructure TelemetryWhat Is DCIM Software, and What Database Does It Use?Data Center Power Monitoring: The Database Layer Behind PUE, PDU, and Sustainability MetricsPrometheus Long-Term Storage: Thanos, Mimir, VictoriaMetrics, and PostgreSQL Compared
Understanding PostgreSQLUnderstanding SQL Aggregate FunctionsUnderstanding the rank() and dense_rank() Functions in PostgreSQLUnderstanding percentile_cont() and percentile_disc() in PostgreSQLStructured vs. Semi-Structured vs. Unstructured Data in PostgreSQLOptimizing Your Database: A Deep Dive into PostgreSQL Data TypesPostgres Cheat SheetHow to Address ‘Error: Could Not Resize Shared Memory Segment’ Understanding the Postgres extract() FunctionUnderstanding FROM in PostgreSQL (With Examples)How to Install PostgreSQL on LinuxHow to Install PostgreSQL on MacOSUnderstanding FILTER in PostgreSQL (With Examples)Understanding HAVING in PostgreSQL (With Examples)5 Common Connection Errors in PostgreSQL and How to Solve ThemUnderstanding GROUP BY in PostgreSQL (With Examples)How to Fix No Partition of Relation Found for Row in Postgres DatabasesUnderstanding LIMIT in PostgreSQL (With Examples)How to Fix Transaction ID Wraparound ExhaustionUnderstanding ORDER BY in PostgreSQL (With Examples)Understanding PostgreSQL FunctionsUnderstanding WINDOW in PostgreSQL (With Examples)Understanding PostgreSQL WITHIN GROUPPostgreSQL Mathematical Functions: Enhancing Coding EfficiencyUnderstanding DISTINCT in PostgreSQL (With Examples)Understanding WHERE in PostgreSQL (With Examples)Understanding OFFSET in PostgreSQL (With Examples)Understanding the Postgres string_agg FunctionUnderstanding PostgreSQL SELECTWhat Characters Are Allowed in PostgreSQL Strings?What Is Data Transformation, and Why Is It Important?What Is Data Compression and How Does It Work?Using PostgreSQL UPDATE With JOINUnderstanding PostgreSQL User-Defined FunctionsUnderstanding Foreign Keys in PostgreSQLData Processing With PostgreSQL Window FunctionsUnderstanding PostgreSQL Date and Time FunctionsWhat Is a PostgreSQL Full Outer Join?What Is a PostgreSQL Inner Join?What Is a PostgreSQL Left Join? And a Right Join?PostgreSQL Join Type TheoryA Guide to PostgreSQL ViewsStrategies for Improving Postgres JOIN PerformanceUnderstanding PostgreSQL's COALESCE FunctionUnderstanding PostgreSQL Array FunctionsUnderstanding PostgreSQL Conditional FunctionsUsing PostgreSQL String Functions for Improved Data AnalysisPostgreSQL vs. Cassandra: The Decision Framework for Time-Series and Write-Heavy WorkloadsPostgreSQL Joins : A SummaryWhat Is a PostgreSQL Cross Join?Data Partitioning: What It Is and Why It MattersSelf-Hosted or Cloud Database? A Countryside Reflection on Infrastructure ChoicesUnderstanding ACID Compliance
Connect Your AI Coding Agent to Tiger Cloud: Setup for Cursor, Claude Code, VS Code, and MoreHow to Monitor and Optimize PostgreSQL Index PerformanceGuide to PostgreSQL PerformancePostgreSQL Performance Tuning: Designing and Implementing Your Database SchemaPostgreSQL Performance Tuning: Key ParametersPostgreSQL Performance Tuning: Optimizing Database IndexesDetermining the Optimal Postgres Partition SizeWhen to Consider Postgres PartitioningAn Intro to Data Modeling on PostgreSQLDesigning Your Database Schema: Wide vs. Narrow Postgres TablesGuide to PostgreSQL Database OperationsBest Practices for Time-Series Data Modeling: Single or Multiple Partitioned Table(s) a.k.a. Hypertables Best Practices for (Time-)Series Metadata Tables A PostgreSQL Database Replication GuideA Guide to Data Analysis on PostgreSQLHow to Query JSONB in PostgreSQLHow to Compute Standard Deviation With PostgreSQLPostgreSQL Performance Tuning: How to Size Your DatabaseSQL/JSON Data Model and JSON in SQL: A PostgreSQL PerspectiveUnderstanding PostgreSQL TablespacesTop PostgreSQL Drivers for PythonPg_partman vs. Hypertables for Postgres PartitioningExplaining PostgreSQL EXPLAINGuide to PostgreSQL Database DesignHow PostgreSQL Data Aggregation WorksBuilding a Scalable DatabaseA Guide to pg_restore (and pg_restore Example)How to Index JSONB Columns in PostgreSQLWhat Is Audit Logging and How to Enable It in PostgreSQLOptimizing Array Queries With GIN Indexes in PostgreSQLHow to Reduce Bloat in Large PostgreSQL TablesGuide to PostgreSQL SecurityHow to Query JSON Metadata in PostgreSQLRecursive Query in SQL: What It Is, and How to Write OneNavigating Growing PostgreSQL Tables With Partitioning (and More)What Is a PostgreSQL Temporary View?How to Use PostgreSQL for Data TransformationHandling Large Objects in PostgresHow to Use Psycopg2: The PostgreSQL Adapter for PythonA Guide to Scaling PostgreSQLAWS Timestream for InfluxDB Alternative: When You Need to Look FurtherHow to Migrate from AWS Timestream to PostgreSQL: A Technical GuideHow to Choose a Database: A Decision Framework for Modern ApplicationsGuide to Postgres Data Management
Time-Series Database High Availability and Disaster RecoveryBest Practices for Scaling PostgreSQLHow to Store Video in PostgreSQL Using BYTEABest Practices for Postgres PerformanceHow to Design Your PostgreSQL Database: Two Schema ExamplesBest Practices for PostgreSQL Database OperationsHow to Manage Your Data With Data Retention PoliciesBest Practices for PostgreSQL Data AnalysisBest Practices for PostgreSQL AggregationBest Practices for Postgres Database ReplicationBest Practices for Postgres Data ManagementHow to Use a Common Table Expression (CTE) in SQLHow to Use PostgreSQL for Data NormalizationTesting Postgres Ingest: INSERT vs. Batch INSERT vs. COPYBest Practices for Postgres SecurityHow to Handle High-Cardinality Data in PostgreSQLPostgreSQL Compression: Every Option, When To Use Each, and What To Expect
The Best PostgreSQL Extensions for Analytics Workloads: A Field GuidePostgreSQL Extensions: amcheckPostgreSQL Extensions: Unlocking Multidimensional Points With Cube PostgreSQL Extensions: hstorePostgreSQL Extensions: ltreePostgreSQL Extensions: Secure Your Time-Series Data With pgcryptoPostgreSQL Extensions: pg_prewarmPostgreSQL Extensions: pgRoutingPostgreSQL Extensions: pg_stat_statementsPostgreSQL Extensions: Database Testing With pgTAPPostgreSQL Extensions: Install pg_trgm for Data MatchingPostgreSQL Extensions: PL/pgSQLPostgreSQL Extensions: Using PostGIS and Timescale for Advanced Geospatial InsightsPostgreSQL Extensions: Intro to uuid-osspTurning PostgreSQL Into a Vector Database With pgvector
What Is ClickHouse and How Does It Compare to PostgreSQL and TimescaleDB for Time Series?Timescale vs. Amazon RDS PostgreSQL: Up to 350x Faster Queries, 44 % Faster Ingest, 95 % Storage Savings for Time-Series DataWhat We Learned From Benchmarking Amazon Aurora PostgreSQL ServerlessTimescaleDB vs. Amazon Timestream: 6,000x Higher Inserts, 5-175x Faster Queries, 150-220x CheaperHow to Store Time-Series Data in MongoDB and Why That’s a Bad IdeaPostgreSQL + TimescaleDB: 1,000x Faster Queries, 90 % Data Compression, and Much MoreEye or the Tiger: Benchmarking Cassandra vs. TimescaleDB for Time-Series Data
MES Data Architecture: Modeling Work Orders, Genealogy, and Historian IntegrationMeter Data Management: Why AMI Interval Data Breaks Legacy MDM SystemsGeofencing and Driver Behavior Analytics: How to Store Both in One DatabaseWhich Database for a Digital Twin? Digital Twin Database Options ComparedGrid Modernization: Why the Data Layer Decides Whether It WorksFleet Telemetry Database: How to Store and Query Vehicle Sensor Data at ScaleUnderstanding IoT (Internet of Things)A Beginner’s Guide to IIoT and Industry 4.0DERMS Database: Solving the Single Source of DER Data ProblemForecasting the Physical World: Foundation Models for Predictive MaintenanceBuilding Energy Management System: The Data Layer Behind Energy Monitoring, Sub-Metering, and M&VSmart Building Analytics: Turning BMS Telemetry Into Occupancy, Energy, and HVAC InsightEV Charging Load ManagementBuilding Management System Database: Architecture for BACnet, Modbus, and Smart Building Sensor Data at ScaleSmart Grid Data Platform: Architecting for SCADA, AMI, PMU, and DERMS Data at ScaleDigital Twin Architecture: The Database and Data Model Behind a Digital TwinCAN Bus Data Logger: Decoding DBC and J1939 Signals into PostgresPredictive Maintenance Database Architecture: Storing and Querying Sensor Data for Failure PredictionPhysical AI Telemetry: Database Architecture for Autonomous-Vehicle FleetsPlant Historian: What It Captures and Where the Analytics Layer BeginsManufacturing Analytics Database: Architecture for Real-Time Production DataRobot Fleet Telemetry: Database Architecture for AMR, Industrial Robot, and Service Robot DataData Center Monitoring: What Database Stores Your Telemetry?EV Charging Management System: Architecture, OCPP Data, and the Right DatabaseIIoT Database Requirements: Six Things Your Database Must DoWater Utilities Database: How to Store and Query SCADA, AMI, and Quality Data at ScaleWhat Is an Edge Database? On-Device Storage, Sync Patterns, and Choosing the Right StackData Historian vs. Time-Series Database: How to Choose and When to SwitchWhat Is a Data Historian?The Best Databases for IoT in 2026: A Practical ComparisonHow Hopthru Powers Real-Time Transit Analytics From a 1 TB TableStoring IoT Data: 8 Reasons Why You Should Use PostgreSQLHow to Simulate a Basic IoT Sensor Dataset on PostgreSQLFrom Ingest to Insights in Milliseconds: Everactive's Tech Transformation With TimescaleHow Ndustrial Is Providing Fast Real-Time Queries and Safely Storing Client Data With 97 % CompressionWhy You Should Use PostgreSQL for Industrial IoT Data Migrating a Low-Code IoT Platform Storing 20M Records/DayHow United Manufacturing Hub Is Introducing Open Source to ManufacturingBuilding IoT Pipelines for Faster Analytics With IoT CoreVisualizing IoT Data at Scale With Hopara and TimescaleDB
A Brief History of AI: How Did We Get Here, and What's Next?A Beginner’s Guide to Vector EmbeddingsPostgreSQL as a Vector Database: A Pgvector TutorialUsing Pgvector With PythonHow to Choose a Vector DatabaseVector Databases Are the Wrong AbstractionUnderstanding DiskANNA Guide to Cosine SimilarityStreaming DiskANN: How We Made PostgreSQL as Fast as Pinecone for Vector DataImplementing Cosine Similarity in PythonVector Database Basics: HNSWVector Database Options for AWSVector Store vs. Vector Database: Understanding the ConnectionPgvector vs. Pinecone: Vector Database Performance and Cost ComparisonHow to Build LLM Applications With Pgvector Vector Store in LangChainHow to Implement RAG With Amazon Bedrock and LangChainRAG Is More Than Just Vector SearchRefining Vector Search Queries With Time Filters in Pgvector: A TutorialUnderstanding Semantic SearchWhat Is Vector Search? Text-to-SQL: A Developer’s Zero-to-Hero GuideWhen Should You Use Full-Text Search vs. Vector Search?HNSW vs. DiskANNVector Search vs Semantic SearchBuilding AI Agents with Persistent Memory: A Unified Database ApproachNearest Neighbor Indexes: What Are IVFFlat Indexes in Pgvector and How Do They WorkPostgreSQL Hybrid Search Using Pgvector and CohereBuilding an AI Image Gallery With OpenAI CLIP, Claude Sonnet 3.5, and Pgvector
PostgreSQL OLTP: Transactions, Scale, and the Architecture That Makes It WorkHow to Choose an OLAP Database: A Practical Decision Guide (2026)Data Analytics vs. Real-Time Analytics: How to Pick Your Database (and Why It Should Be PostgreSQL)How to Choose a Real-Time Analytics DatabaseColumnar Databases vs. Row-Oriented Databases: Which to Choose?What Is the Best Database for Real-Time AnalyticsPostgreSQL as a Real-Time Analytics DatabaseUnderstanding OLAP: What It Is, How It Differs From OLTP, and Running It on PostgreSQLHow to Build an IoT Pipeline for Real-Time Analytics in PostgreSQL
Alternatives to RDSWhy Is RDS so Expensive? Understanding RDS Pricing and CostsEstimating RDS CostsHow to Migrate From AWS RDS for PostgreSQL to TimescaleAmazon Aurora vs. RDS: Understanding the Difference
5 InfluxDB Alternatives for Your Time-Series Data8 Reasons to Choose Timescale as Your InfluxDB Alternative InfluxQL, Flux, and SQL: Which Query Language Is Best? (With Cheatsheet)What InfluxDB Got WrongTimescaleDB vs. InfluxDB: Purpose Built Differently for Time-Series Data
5 Ways to Monitor Your PostgreSQL DatabaseHow to Migrate Your Data to Timescale (3 Ways)Postgres TOAST vs. Timescale CompressionBuilding Python Apps With PostgreSQL: A Developer's GuideData Visualization in PostgreSQL With Apache SupersetMore Time-Series Data Analysis, Fewer Lines of Code: Meet HyperfunctionsIs Postgres Partitioning Really That Hard? An Introduction To HypertablesPostgreSQL Materialized Views and Where to Find ThemTime-Series Downsampling: The Complete Guide to Tiered Data Resolution in SQLContinuous Aggregates: Incremental Materialized Views for Time-Series DataComplete Guide: Migrating from MongoDB to Tiger Data (Step-by-Step)Timescale Tips: Testing Your Chunk Size
Postgres cheat sheet
HomeAlternativesTime-series basicsData Center & Infrastructure TelemetryPostgres basicsPostgres guidesPostgres best practices
Home
Tiger MCP vs. a Generic Postgres MCP Server
Time Series Forecasting with PostgreSQL: Methods, SQL Examples, and When to Use PythonTime-Series Analysis and Forecasting With Python Why Consider Using PostgreSQL for Time-Series Data?Time-Series Analysis in RWhat Is Temporal Data?Understanding Autoregressive Time-Series ModelingAlternatives to TimescaleStationary Time-Series AnalysisWhat Are Open-Source Time-Series Databases—Understanding Your OptionsIs Your Data Time Series? Data Types Supported by PostgreSQL and TimescaleUnderstanding Database Workloads: Variable, Bursty, and Uniform PatternsThe Best Time-Series Databases Compared (2026)Time Series Anomaly Detection: Methods, SQL, and Real-Time ImplementationAWS Timestream Alternatives: Your Migration Options After LiveAnalyticsTime-Series Database: What It Is, How It Works, and When You Need OneWhat Is a Time Series and How Is It Used?How to Work With Time Series in Python?Tools for Working With Time-Series Analysis in PythonGuide to Time-Series Analysis in PythonCreating a Fast Time-Series Graph With Postgres Materialized Views
OpenTelemetry Backend: Choosing Metrics Storage That Doesn't Lock You InGPU Cluster Monitoring: The Database Behind AI Infrastructure TelemetryWhat Is DCIM Software, and What Database Does It Use?Data Center Power Monitoring: The Database Layer Behind PUE, PDU, and Sustainability MetricsPrometheus Long-Term Storage: Thanos, Mimir, VictoriaMetrics, and PostgreSQL Compared
Understanding PostgreSQLUnderstanding SQL Aggregate FunctionsUnderstanding the rank() and dense_rank() Functions in PostgreSQLUnderstanding percentile_cont() and percentile_disc() in PostgreSQLStructured vs. Semi-Structured vs. Unstructured Data in PostgreSQLOptimizing Your Database: A Deep Dive into PostgreSQL Data TypesPostgres Cheat SheetHow to Address ‘Error: Could Not Resize Shared Memory Segment’ Understanding the Postgres extract() FunctionUnderstanding FROM in PostgreSQL (With Examples)How to Install PostgreSQL on LinuxHow to Install PostgreSQL on MacOSUnderstanding FILTER in PostgreSQL (With Examples)Understanding HAVING in PostgreSQL (With Examples)5 Common Connection Errors in PostgreSQL and How to Solve ThemUnderstanding GROUP BY in PostgreSQL (With Examples)How to Fix No Partition of Relation Found for Row in Postgres DatabasesUnderstanding LIMIT in PostgreSQL (With Examples)How to Fix Transaction ID Wraparound ExhaustionUnderstanding ORDER BY in PostgreSQL (With Examples)Understanding PostgreSQL FunctionsUnderstanding WINDOW in PostgreSQL (With Examples)Understanding PostgreSQL WITHIN GROUPPostgreSQL Mathematical Functions: Enhancing Coding EfficiencyUnderstanding DISTINCT in PostgreSQL (With Examples)Understanding WHERE in PostgreSQL (With Examples)Understanding OFFSET in PostgreSQL (With Examples)Understanding the Postgres string_agg FunctionUnderstanding PostgreSQL SELECTWhat Characters Are Allowed in PostgreSQL Strings?What Is Data Transformation, and Why Is It Important?What Is Data Compression and How Does It Work?Using PostgreSQL UPDATE With JOINUnderstanding PostgreSQL User-Defined FunctionsUnderstanding Foreign Keys in PostgreSQLData Processing With PostgreSQL Window FunctionsUnderstanding PostgreSQL Date and Time FunctionsWhat Is a PostgreSQL Full Outer Join?What Is a PostgreSQL Inner Join?What Is a PostgreSQL Left Join? And a Right Join?PostgreSQL Join Type TheoryA Guide to PostgreSQL ViewsStrategies for Improving Postgres JOIN PerformanceUnderstanding PostgreSQL's COALESCE FunctionUnderstanding PostgreSQL Array FunctionsUnderstanding PostgreSQL Conditional FunctionsUsing PostgreSQL String Functions for Improved Data AnalysisPostgreSQL vs. Cassandra: The Decision Framework for Time-Series and Write-Heavy WorkloadsPostgreSQL Joins : A SummaryWhat Is a PostgreSQL Cross Join?Data Partitioning: What It Is and Why It MattersSelf-Hosted or Cloud Database? A Countryside Reflection on Infrastructure ChoicesUnderstanding ACID Compliance
Connect Your AI Coding Agent to Tiger Cloud: Setup for Cursor, Claude Code, VS Code, and MoreHow to Monitor and Optimize PostgreSQL Index PerformanceGuide to PostgreSQL PerformancePostgreSQL Performance Tuning: Designing and Implementing Your Database SchemaPostgreSQL Performance Tuning: Key ParametersPostgreSQL Performance Tuning: Optimizing Database IndexesDetermining the Optimal Postgres Partition SizeWhen to Consider Postgres PartitioningAn Intro to Data Modeling on PostgreSQLDesigning Your Database Schema: Wide vs. Narrow Postgres TablesGuide to PostgreSQL Database OperationsBest Practices for Time-Series Data Modeling: Single or Multiple Partitioned Table(s) a.k.a. Hypertables Best Practices for (Time-)Series Metadata Tables A PostgreSQL Database Replication GuideA Guide to Data Analysis on PostgreSQLHow to Query JSONB in PostgreSQLHow to Compute Standard Deviation With PostgreSQLPostgreSQL Performance Tuning: How to Size Your DatabaseSQL/JSON Data Model and JSON in SQL: A PostgreSQL PerspectiveUnderstanding PostgreSQL TablespacesTop PostgreSQL Drivers for PythonPg_partman vs. Hypertables for Postgres PartitioningExplaining PostgreSQL EXPLAINGuide to PostgreSQL Database DesignHow PostgreSQL Data Aggregation WorksBuilding a Scalable DatabaseA Guide to pg_restore (and pg_restore Example)How to Index JSONB Columns in PostgreSQLWhat Is Audit Logging and How to Enable It in PostgreSQLOptimizing Array Queries With GIN Indexes in PostgreSQLHow to Reduce Bloat in Large PostgreSQL TablesGuide to PostgreSQL SecurityHow to Query JSON Metadata in PostgreSQLRecursive Query in SQL: What It Is, and How to Write OneNavigating Growing PostgreSQL Tables With Partitioning (and More)What Is a PostgreSQL Temporary View?How to Use PostgreSQL for Data TransformationHandling Large Objects in PostgresHow to Use Psycopg2: The PostgreSQL Adapter for PythonA Guide to Scaling PostgreSQLAWS Timestream for InfluxDB Alternative: When You Need to Look FurtherHow to Migrate from AWS Timestream to PostgreSQL: A Technical GuideHow to Choose a Database: A Decision Framework for Modern ApplicationsGuide to Postgres Data Management
Time-Series Database High Availability and Disaster RecoveryBest Practices for Scaling PostgreSQLHow to Store Video in PostgreSQL Using BYTEABest Practices for Postgres PerformanceHow to Design Your PostgreSQL Database: Two Schema ExamplesBest Practices for PostgreSQL Database OperationsHow to Manage Your Data With Data Retention PoliciesBest Practices for PostgreSQL Data AnalysisBest Practices for PostgreSQL AggregationBest Practices for Postgres Database ReplicationBest Practices for Postgres Data ManagementHow to Use a Common Table Expression (CTE) in SQLHow to Use PostgreSQL for Data NormalizationTesting Postgres Ingest: INSERT vs. Batch INSERT vs. COPYBest Practices for Postgres SecurityHow to Handle High-Cardinality Data in PostgreSQLPostgreSQL Compression: Every Option, When To Use Each, and What To Expect
The Best PostgreSQL Extensions for Analytics Workloads: A Field GuidePostgreSQL Extensions: amcheckPostgreSQL Extensions: Unlocking Multidimensional Points With Cube PostgreSQL Extensions: hstorePostgreSQL Extensions: ltreePostgreSQL Extensions: Secure Your Time-Series Data With pgcryptoPostgreSQL Extensions: pg_prewarmPostgreSQL Extensions: pgRoutingPostgreSQL Extensions: pg_stat_statementsPostgreSQL Extensions: Database Testing With pgTAPPostgreSQL Extensions: Install pg_trgm for Data MatchingPostgreSQL Extensions: PL/pgSQLPostgreSQL Extensions: Using PostGIS and Timescale for Advanced Geospatial InsightsPostgreSQL Extensions: Intro to uuid-osspTurning PostgreSQL Into a Vector Database With pgvector
What Is ClickHouse and How Does It Compare to PostgreSQL and TimescaleDB for Time Series?Timescale vs. Amazon RDS PostgreSQL: Up to 350x Faster Queries, 44 % Faster Ingest, 95 % Storage Savings for Time-Series DataWhat We Learned From Benchmarking Amazon Aurora PostgreSQL ServerlessTimescaleDB vs. Amazon Timestream: 6,000x Higher Inserts, 5-175x Faster Queries, 150-220x CheaperHow to Store Time-Series Data in MongoDB and Why That’s a Bad IdeaPostgreSQL + TimescaleDB: 1,000x Faster Queries, 90 % Data Compression, and Much MoreEye or the Tiger: Benchmarking Cassandra vs. TimescaleDB for Time-Series Data
MES Data Architecture: Modeling Work Orders, Genealogy, and Historian IntegrationMeter Data Management: Why AMI Interval Data Breaks Legacy MDM SystemsGeofencing and Driver Behavior Analytics: How to Store Both in One DatabaseWhich Database for a Digital Twin? Digital Twin Database Options ComparedGrid Modernization: Why the Data Layer Decides Whether It WorksFleet Telemetry Database: How to Store and Query Vehicle Sensor Data at ScaleUnderstanding IoT (Internet of Things)A Beginner’s Guide to IIoT and Industry 4.0DERMS Database: Solving the Single Source of DER Data ProblemForecasting the Physical World: Foundation Models for Predictive MaintenanceBuilding Energy Management System: The Data Layer Behind Energy Monitoring, Sub-Metering, and M&VSmart Building Analytics: Turning BMS Telemetry Into Occupancy, Energy, and HVAC InsightEV Charging Load ManagementBuilding Management System Database: Architecture for BACnet, Modbus, and Smart Building Sensor Data at ScaleSmart Grid Data Platform: Architecting for SCADA, AMI, PMU, and DERMS Data at ScaleDigital Twin Architecture: The Database and Data Model Behind a Digital TwinCAN Bus Data Logger: Decoding DBC and J1939 Signals into PostgresPredictive Maintenance Database Architecture: Storing and Querying Sensor Data for Failure PredictionPhysical AI Telemetry: Database Architecture for Autonomous-Vehicle FleetsPlant Historian: What It Captures and Where the Analytics Layer BeginsManufacturing Analytics Database: Architecture for Real-Time Production DataRobot Fleet Telemetry: Database Architecture for AMR, Industrial Robot, and Service Robot DataData Center Monitoring: What Database Stores Your Telemetry?EV Charging Management System: Architecture, OCPP Data, and the Right DatabaseIIoT Database Requirements: Six Things Your Database Must DoWater Utilities Database: How to Store and Query SCADA, AMI, and Quality Data at ScaleWhat Is an Edge Database? On-Device Storage, Sync Patterns, and Choosing the Right StackData Historian vs. Time-Series Database: How to Choose and When to SwitchWhat Is a Data Historian?The Best Databases for IoT in 2026: A Practical ComparisonHow Hopthru Powers Real-Time Transit Analytics From a 1 TB TableStoring IoT Data: 8 Reasons Why You Should Use PostgreSQLHow to Simulate a Basic IoT Sensor Dataset on PostgreSQLFrom Ingest to Insights in Milliseconds: Everactive's Tech Transformation With TimescaleHow Ndustrial Is Providing Fast Real-Time Queries and Safely Storing Client Data With 97 % CompressionWhy You Should Use PostgreSQL for Industrial IoT Data Migrating a Low-Code IoT Platform Storing 20M Records/DayHow United Manufacturing Hub Is Introducing Open Source to ManufacturingBuilding IoT Pipelines for Faster Analytics With IoT CoreVisualizing IoT Data at Scale With Hopara and TimescaleDB
A Brief History of AI: How Did We Get Here, and What's Next?A Beginner’s Guide to Vector EmbeddingsPostgreSQL as a Vector Database: A Pgvector TutorialUsing Pgvector With PythonHow to Choose a Vector DatabaseVector Databases Are the Wrong AbstractionUnderstanding DiskANNA Guide to Cosine SimilarityStreaming DiskANN: How We Made PostgreSQL as Fast as Pinecone for Vector DataImplementing Cosine Similarity in PythonVector Database Basics: HNSWVector Database Options for AWSVector Store vs. Vector Database: Understanding the ConnectionPgvector vs. Pinecone: Vector Database Performance and Cost ComparisonHow to Build LLM Applications With Pgvector Vector Store in LangChainHow to Implement RAG With Amazon Bedrock and LangChainRAG Is More Than Just Vector SearchRefining Vector Search Queries With Time Filters in Pgvector: A TutorialUnderstanding Semantic SearchWhat Is Vector Search? Text-to-SQL: A Developer’s Zero-to-Hero GuideWhen Should You Use Full-Text Search vs. Vector Search?HNSW vs. DiskANNVector Search vs Semantic SearchBuilding AI Agents with Persistent Memory: A Unified Database ApproachNearest Neighbor Indexes: What Are IVFFlat Indexes in Pgvector and How Do They WorkPostgreSQL Hybrid Search Using Pgvector and CohereBuilding an AI Image Gallery With OpenAI CLIP, Claude Sonnet 3.5, and Pgvector
PostgreSQL OLTP: Transactions, Scale, and the Architecture That Makes It WorkHow to Choose an OLAP Database: A Practical Decision Guide (2026)Data Analytics vs. Real-Time Analytics: How to Pick Your Database (and Why It Should Be PostgreSQL)How to Choose a Real-Time Analytics DatabaseColumnar Databases vs. Row-Oriented Databases: Which to Choose?What Is the Best Database for Real-Time AnalyticsPostgreSQL as a Real-Time Analytics DatabaseUnderstanding OLAP: What It Is, How It Differs From OLTP, and Running It on PostgreSQLHow to Build an IoT Pipeline for Real-Time Analytics in PostgreSQL
Alternatives to RDSWhy Is RDS so Expensive? Understanding RDS Pricing and CostsEstimating RDS CostsHow to Migrate From AWS RDS for PostgreSQL to TimescaleAmazon Aurora vs. RDS: Understanding the Difference
5 InfluxDB Alternatives for Your Time-Series Data8 Reasons to Choose Timescale as Your InfluxDB Alternative InfluxQL, Flux, and SQL: Which Query Language Is Best? (With Cheatsheet)What InfluxDB Got WrongTimescaleDB vs. InfluxDB: Purpose Built Differently for Time-Series Data
5 Ways to Monitor Your PostgreSQL DatabaseHow to Migrate Your Data to Timescale (3 Ways)Postgres TOAST vs. Timescale CompressionBuilding Python Apps With PostgreSQL: A Developer's GuideData Visualization in PostgreSQL With Apache SupersetMore Time-Series Data Analysis, Fewer Lines of Code: Meet HyperfunctionsIs Postgres Partitioning Really That Hard? An Introduction To HypertablesPostgreSQL Materialized Views and Where to Find ThemTime-Series Downsampling: The Complete Guide to Tiered Data Resolution in SQLContinuous Aggregates: Incremental Materialized Views for Time-Series DataComplete Guide: Migrating from MongoDB to Tiger Data (Step-by-Step)Timescale Tips: Testing Your Chunk Size
Postgres cheat sheet
Tiger Data

Products

  • TimescaleDB
  • Tiger Cloud
  • TimescaleDB Enterprise
  • Postgres Search Stack

Industry

  • Data Centers
  • Energy & Utilities
  • Oilfield Services
  • Smart Manufacturing
  • Crypto

Support

  • Cloud Status
  • Support
  • Security
  • Terms of Service
  • Code Of Conduct

Learn

  • Documentation
  • Blog
  • Tutorials
  • Changelog
  • Success Stories

Company

  • About
  • Contact Us
  • Careers
  • Newsroom
  • Brand
  • Events
Privacy preferencesLegalPrivacySitemap

Subscribe to the Tiger Data newsletter

Strategic Partner with Inductive Automation — Ignition

2026 (c) Timescale, Inc., d/b/a Tiger Data.
All rights reserved.

Tiger Data

2026 (c) Timescale, Inc., d/b/a Tiger Data.
All rights reserved.

Privacy preferencesLegalPrivacySitemap

By Tiger Data Team

Updated at Oct 2, 2026

Table of contents

    PostgreSQL OLTP: Transactions, Scale, and the Architecture That Makes It Work

    Understanding OLTP

    By Tiger Data Team

    Updated at Oct 2, 2026

    What is OLTP?

    Every checkout, bank transfer, and app login runs on it, even if you never see it happening. OLTP stands for Online Transaction Processing. It describes a workload pattern built around high volumes of short, individual transactions. 

    Each transaction reads, writes, or updates one record (or a small handful of records), and it has to complete atomically, stay consistent, and become durable the instant it commits. OLTP optimizes for correctness on individual rows. Batch or analytical workloads work differently. They scan millions of rows at once to compute aggregates.

    The four ACID (Atomic, Consistent, Isolated, and Durable) properties are what make a transaction trustworthy. Atomicity means every operation in a transaction either succeeds completely or fails completely, with no partial writes left behind. Consistency means a transaction always moves the database from one valid state to another, with every constraint and rule holding after each commit. 

    Isolation means concurrent transactions don't interfere with each other. Each one runs as if it were the only transaction in the system. Durability means once a transaction commits, it survives crashes and restarts as a permanent write.

    Ask any engineer to name a classic OLTP system, and three examples come up almost immediately. The first is an e-commerce order management system, where every add-to-cart, checkout, and inventory decrement is its own transaction. The second is a banking ledger, where every debit and credit posts atomically against a balance. The third is a SaaS application's user event store, where session writes, preference updates, and audit logs arrive at high concurrency and need to be readable the instant they're inserted.

    OLTP vs. OLAP at a glance

    Dimension

    OLTP

    OLAP

    Write pattern

    Continuous, high-frequency inserts and updates

    Batch loads or streaming ingest

    Read pattern

    Point lookups, narrow range scans

    Full-table scans, wide aggregations

    Query type

    Simple SELECT / INSERT / UPDATE / DELETE

    Complex GROUP BY, window functions, JOINs across large datasets

    Rows per transaction

    1 to a few hundred

    Millions to billions

    Latency requirement

    Milliseconds

    Seconds to minutes acceptable

    Example workloads

    Order management, banking, SaaS backends

    Business intelligence, reporting, historical analytics

    Optimization target

    Transactional correctness, concurrency

    Analytical throughput, compression

    For a deeper look at analytical workloads on PostgreSQL, see OLAP workloads on PostgreSQL, a guide.

    PostgreSQL has become the dominant open-source OLTP engine in production today. The 2025 Stack Overflow Developer Survey confirmed it as the most-used database among professional developers, marking its third consecutive year at the top. The rest of this guide looks at how PostgreSQL actually handles OLTP workloads: where the architecture holds up under pressure, and where it needs deliberate operational attention at scale.

    PostgreSQL as a production OLTP engine

    PostgreSQL's production OLTP story rests on two architectural pillars: Multi-Version Concurrency Control (MVCC) for high-concurrency reads and writes, and the Write-Ahead Log (WAL) for crash recovery and replication. Both deliver real benefits, and both carry real operational costs worth understanding before you hit them in production.

    How MVCC enables high-concurrency reads and writes

    PostgreSQL's concurrency model is MVCC. Understanding it explains both the strengths and the operational costs you'll run into. When a transaction runs an UPDATE, PostgreSQL writes a new version of the row (a new tuple) to the table's data pages and marks the old version as expired. When a SELECT runs, it gets a consistent snapshot of the database as of the moment the query starts (or the moment the transaction starts, under Repeatable Read and Serializable isolation). Readers see the old version until the writer commits. Once committed, new readers see the new version.

    Because of this, reads and writes don't block each other. A reporting query scanning 50 million rows won't hold a lock that blocks application writes. A burst of concurrent inserts won't queue behind a slow read. For mixed read-write OLTP workloads, this is what allows PostgreSQL to scale well with concurrency: many simultaneous readers and writers, without the explicit locking overhead older concurrency models require.

    This comes with a trade-off though, MVCC creates dead tuples. When a row is updated or deleted, the old version stays on disk until autovacuum reclaims it. Under heavy write loads, tables can accumulate dead rows faster than autovacuum's default settings can clear them, leading to table bloat and a query planner working off stale statistics. This is the most commonly discussed PostgreSQL OLTP pain point in production, and it's the focus of the next section.

    PostgreSQL's Write-Ahead Log (WAL) is the second core piece. Every transaction is written to WAL before it's applied to the data pages. WAL enables crash recovery (replay the log to reconstruct committed state) and streaming replication (ship WAL records to replicas). At high transaction rates, WAL write amplification is a significant cost, though modern NVMe storage and proper wal_buffers tuning keep it manageable.

    Write amplification and autovacuum

    For every row UPDATE, PostgreSQL writes the full new row version to the table's data pages, plus a WAL record for crash recovery. On update-heavy OLTP workloads (frequent status changes, balance updates, state machine transitions), this creates more disk I/O than in-place update engines produce. It's a known architectural trade-off, and it's solvable with the right configuration.

    Autovacuum is PostgreSQL's background process for reclaiming dead tuples, updating planner statistics, and preventing transaction ID wraparound. Default settings work fine at low to moderate write rates. At high throughput, tables taking thousands of updates per second can accumulate dead tuples faster than the default autovacuum workers can process them. Watch for growing table bloat, rising dead tuple counts in pg_stat_user_tables, and planner estimates that drift from actual row counts.

    Three parameters matter most for tuning autovacuum on high-write OLTP tables: autovacuum_vacuum_scale_factor (lower it so autovacuum triggers more often on smaller tables), autovacuum_vacuum_cost_delay (reduce it, or set it to zero, on fast storage), and autovacuum_max_workers (raise it above the default of 3 for databases with many active tables). The timescaledb-tune tool can raise autovacuum_max_workers above the default as part of tuning PostgreSQL for TimescaleDB's higher write rates. 

    Monitor n_dead_tup and autovacuum_count in pg_stat_user_tables to spot tables where autovacuum can't keep pace. See Best Practices for Postgres Performance and the Guide to PostgreSQL Performance for deeper tuning guidance.

    PostgreSQL OLTP configuration reference

    Parameter

    What it controls

    OLTP starting recommendation

    Trade-off

    shared_buffers

    Memory allocated for PostgreSQL's shared buffer cache

    25% of system RAM (do not exceed 40%)

    Higher values reduce disk I/O, but too high leaves insufficient RAM for the OS page cache, which backfires

    work_mem

    Memory per sort/hash operation before spilling to disk

    32 MB global, tuned per-session for complex queries

    Allocated per operation rather than per connection, so high values with many concurrent connections can exhaust RAM

    max_connections

    Maximum concurrent client connections

    3-5x available CPU cores, with PgBouncer above ~200 connections

    Higher values consume memory and increase context-switching overhead at the OS process level

    wal_buffers

    In-memory buffer for WAL data before flushing to disk

    64 MB, set manually for high-write OLTP (default auto-tunes to ~3% of shared_buffers, capped at 16 MB)

    Larger values reduce WAL flush frequency, with diminishing returns past 64 MB for most workloads

    autovacuum_vacuum_scale_factor

    Fraction of table size that triggers autovacuum

    0.01–0.05 for high-write tables (default is 0.2)

    Lower values mean more frequent vacuums, which is appropriate for tables with frequent updates

    checkpoint_completion_target

    How long PostgreSQL spreads checkpoint I/O

    0.9 (PostgreSQL's default since v14)

    Higher values smooth I/O; too low causes checkpoint spikes that compete with query I/O

    For tool-assisted tuning, timescaledb-tune adjusts common PostgreSQL parameters for TimescaleDB workloads. The Tiger Cloud Console also exposes an Advanced Parameters tab for managed service users.

    Connection pooling and why PgBouncer is essential at scale

    PostgreSQL spawns one OS process per client connection. At low connection counts (tens to a few hundred), this is stable and predictable. 

    At high connection counts, memory pressure and context-switching overhead degrade query throughput. Direct connections tend to show measurable overhead somewhere around 200-300 connections, depending on available RAM and CPU cores.

    PgBouncer sits between the application tier and PostgreSQL, maintaining a small pool of actual PostgreSQL server connections and multiplexing application client connections onto them. In transaction pooling mode (the standard choice for OLTP workloads), PgBouncer holds a server connection only for the duration of a single transaction, then returns it to the pool. This allows thousands of application connections to share a pool of 100-300 server connections without per-process overhead building up on the PostgreSQL side.

    A common production pattern routes 2,000-10,000 application connections through PgBouncer, mapped down to 100-300 PostgreSQL server connections. The application tier sees what looks like a large connection pool. PostgreSQL sees a manageable number of server processes.

    OpenAI's engineering team published an architectural overview describing how they scale a single unsharded PostgreSQL primary, with nearly 50 read replicas, to serve ChatGPT's roughly 800 million users. 

    Connection pooling is one important piece of that architecture: they run PgBouncer as a proxy layer in front of the read replicas, pooling connections to cut their average connection setup time from 50ms to 5ms. It sits alongside other techniques they rely on, including caching, rate limiting at multiple layers, and offloading reads to replicas, to keep the whole system stable at that scale.

    PgBouncer is the community-standard choice, but it's not the only option. Pgpool-II provides additional load balancing and high availability features at higher operational complexity. Connection pooling is also built into some cloud-managed PostgreSQL services, including Tiger Cloud's managed PgBouncer integration, accessible via the Operations tab in the Tiger Console.

    OLTP schema design in PostgreSQL

    Schemas optimized for OLTP start with normalization. Third normal form (3NF) splits data into related tables with foreign key relationships, minimizing duplication and keeping atomic updates scoped to just the relevant rows. 

    Denormalization trades write efficiency for read efficiency. That suits analytical workloads, but it usually hurts OLTP-heavy systems, where transactional correctness and write throughput matter more than read scan performance.

    Index strategy for OLTP workloads follows three patterns. B-tree indexes, PostgreSQL's default, work best for equality and range queries on primary and foreign key columns. Covering indexes include the extra columns a query returns directly in the index, so high-frequency queries can skip the heap fetch. Partial indexes cover only the rows matching a WHERE clause (for example, WHERE status = 'pending'), keeping index size and maintenance overhead down for queries that target a subset of a table's rows.

    A normalized order management schema with appropriate indexes:

    -- Normalized OLTP schema: order management system CREATE TABLE customers ( customer_id BIGSERIAL PRIMARY KEY, email TEXT NOT NULL UNIQUE, full_name TEXT NOT NULL, created_at TIMESTAMPTZ NOT NULL DEFAULT now() ); CREATE TABLE products ( product_id BIGSERIAL PRIMARY KEY, sku TEXT NOT NULL UNIQUE, name TEXT NOT NULL, price NUMERIC(12,2) NOT NULL CHECK (price >= 0), stock_qty INTEGER NOT NULL DEFAULT 0 ); CREATE TABLE orders ( order_id BIGSERIAL PRIMARY KEY, customer_id BIGINT NOT NULL REFERENCES customers(customer_id), status TEXT NOT NULL DEFAULT 'pending', total_amount NUMERIC(12,2) NOT NULL, created_at TIMESTAMPTZ NOT NULL DEFAULT now() ); CREATE TABLE order_items ( order_item_id BIGSERIAL PRIMARY KEY, order_id BIGINT NOT NULL REFERENCES orders(order_id), product_id BIGINT NOT NULL REFERENCES products(product_id), quantity INTEGER NOT NULL CHECK (quantity > 0), unit_price NUMERIC(12,2) NOT NULL ); -- High-frequency query pattern: customer order history, newest first CREATE INDEX ON orders (customer_id, created_at DESC); -- Partial index: only index pending orders (avoids bloat from completed orders) CREATE INDEX ON orders (created_at) WHERE status = 'pending'; -- Covering index: avoid heap fetch for order item lookups by order CREATE INDEX ON order_items (order_id) INCLUDE (product_id, quantity, unit_price);

    For deeper schema and index guidance, see A Guide to Scaling PostgreSQL and Best Practices for Scaling PostgreSQL.

    Scaling PostgreSQL OLTP

    OpenAI's architecture for hundreds of millions of users on one unsharded primary

    OpenAI published an architectural overview describing how they scaled PostgreSQL to support ChatGPT's roughly 800 million users. It's some of the clearest public evidence that PostgreSQL can handle OLTP at extreme scale, when the architecture around it is properly designed.

    The core pieces of OpenAI's published design include a single unsharded primary handling all writes, backed by nearly 50 read replicas that absorb read traffic. PgBouncer runs as a proxy layer in front of the read replicas, pooling and reusing connections to reduce overhead. A cache locking mechanism stops a burst of cache misses from hitting the database all at once, and rate limiting is applied across the application, connection pooler, proxy, and query layers.

    PostgreSQL isn't carrying every workload here. OpenAI migrates shardable, write-heavy workloads off PostgreSQL onto sharded systems like Azure Cosmos DB, and new tables default to those systems too. What stays on the unsharded primary is largely read-heavy, and that's exactly where PostgreSQL holds up so well. A single primary, properly pooled and replicated, serves hundreds of millions of users without needing to shard its write path. Operational complexity stays low as a result, since distributed transactions and cross-shard queries bring their own latency and failure modes that a single primary simply avoids.

    This points to a broader pattern for most PostgreSQL OLTP systems. For read-heavy workloads, connection management and read distribution are usually the first limits teams hit. Fix the connection model with PgBouncer, route reads to replicas, and offload what's shardable early. Write-heavy traffic is the harder ceiling for a single primary, which is why OpenAI moves it to sharded systems. For read-heavy workloads, though, one well-pooled primary goes further than most engineers expect. 

    The pattern breaks down for workloads where transactional data is also time-ordered (IoT sensor streams, financial transaction logs, or operational metrics arriving at high write frequency). A single table accumulating rows indefinitely runs into vacuum and partition management friction that replica scaling alone doesn't fix. That's where time-partitioned approaches become architecturally relevant.

    When table partitioning becomes necessary

    As PostgreSQL tables grow past hundreds of millions of rows, three problems compound:

    • The query planner has to reason about the full index range even for time-bounded queries, which adds overhead.

    • Autovacuum takes longer to process large tables, so dead tuples pile up between passes. 

    • Index bloat builds up as rows across the full history compete for index space.

    Native PostgreSQL declarative partitioning (available since PostgreSQL 10) addresses this by splitting a table into physical partitions by range, list, or hash. For time-ordered data, range partitioning on the timestamp column lines up the storage layout with the access pattern. Queries for the last 7 days touch only recent partitions and skip historical ones entirely. Autovacuum also runs independently per partition, finishing faster and avoiding long locks on the full dataset.

    The operational cost of native range partitioning is partition lifecycle management. Partitions need to be created in advance, old partitions need to be detached and dropped manually (or through scheduled scripts), and the DDL maintenance burden grows with the number of active partitions.

    For time-ordered data at high volumes, TimescaleDB automates this lifecycle. See When to Consider Postgres Partitioning for a structured decision framework on when native partitioning is sufficient and when an extension layer is worth adding.

    PostgreSQL OLTP for time-series and HTAP workloads

    The time-ordered OLTP pattern

    Many high-throughput OLTP systems produce data that's simultaneously transactional and time-ordered. Each record is atomic and needs to be durable and immediately readable after insert, which is a standard OLTP requirement. At the same time, rows arrive with timestamps, queries target time ranges, and historical data gets accessed far less often than recent data, which is a time-series access pattern layered on top.

    Three examples make this concrete. IoT sensor writes, where each reading is a discrete transaction and queries ask for the last 24 hours of sensor X. Financial transaction streams, where each payment posts atomically and analytics query the last 7 days by merchant. Operational metrics pipelines, where each metric point is a row and dashboards query recent windows continuously.

    Standard PostgreSQL architecture is suboptimal for this pattern at scale. A single monolithic table accumulates rows indefinitely, and autovacuum has to process the entire table on each cycle. The query planner considers the full index range even when queries target only the last hour. Hot recent data and cold historical data end up sharing the same table pages, which defeats buffer cache locality. A query for today's sensor readings can evict yesterday's cached pages, even though yesterday's data is rarely queried again.

    Time-partitioned storage solves the locality problem directly. Queries for recent data touch only the current partition. Autovacuum runs on individual partitions and finishes faster. Cold historical partitions can be compressed independently without affecting writes to the hot partition.

    TimescaleDB's hypertables automate this partitioning lifecycle. The extension creates fixed-size chunks (7 days by default) automatically as data arrives, routes queries to the relevant chunks, and exposes the full dataset as a single logical table with no changes to the application SQL.

    Hypertables and automatic time partitioning for OLTP at scale

    A hypertable is a logical table backed by multiple physical PostgreSQL tables (chunks), each covering a fixed time range. TimescaleDB routes inserts to the current chunk automatically and rewrites time-range queries to scan only the relevant chunks, a process called chunk pruning. From the application's perspective, the hypertable looks like a standard PostgreSQL table, so existing INSERT, SELECT, UPDATE, and DELETE statements work without modification.

    The operational advantages for OLTP workloads are concrete. Inserts always land on the current (hot) chunk, a small table with a compact index, with no lock contention across the full history. A query for WHERE time > now() - INTERVAL '7 days' touches 1-2 chunks regardless of total table size. Autovacuum on individual chunks finishes faster and holds shorter locks than autovacuum on a full unpartitioned table. Older chunks (data older than 30 days, for example) can be compressed to columnar format, cutting storage by up to 98% while staying fully queryable through standard SQL.

    The create_hypertable() documentation covers all parameters. Here's the basic progression from a standard PostgreSQL table to a hypertable with compression and retention:

    -- Step 1: create the TimescaleDB extension (run once per database) CREATE EXTENSION IF NOT EXISTS timescaledb; -- Step 2: create the base table -- TIMESTAMPTZ is the recommended type for the time column CREATE TABLE device_readings ( device_id TEXT NOT NULL, time TIMESTAMPTZ NOT NULL, value DOUBLE PRECISION NOT NULL, unit TEXT NOT NULL ); -- Step 3: convert to a hypertable, partitioned by time -- Size chunks so the indexes of the chunks being written fit in ~25% of memory SELECT create_hypertable( 'device_readings', by_range('time', INTERVAL '7 days') ); -- Step 4: enable the columnstore and add a columnstore policy -- Chunks older than 30 days move to the columnstore automatically -- Columnstore compression reduces storage by up to 98% for time-series data ALTER TABLE device_readings SET ( timescaledb.enable_columnstore, timescaledb.segmentby = 'device_id', timescaledb.orderby = 'time DESC' ); CALL add_columnstore_policy('device_readings', after => INTERVAL '30 days'); -- Step 5 (optional): add a retention policy -- Chunks older than 1 year are automatically dropped SELECT add_retention_policy('device_readings', INTERVAL '1 year');

    For existing tables with data, set migrate_data => TRUE in the create_hypertable() call. Migration on large tables can take a while, so plan for that. See the create_hypertable() documentation for migration options and limits.

    See PostgreSQL as a Real-Time Analytics Database for query patterns that take advantage of chunk pruning.

    Continuous aggregates for analytics on your OLTP data without ETL

    High-frequency OLTP writes create tension. Transactional data arrives continuously and needs to be immediately queryable at the row level, while analytical queries (hourly averages, daily totals, 7-day rolling counts) aggregate over that same data again and again. Without a continuous aggregate, a query like the one below has to scan millions of rows every time a dashboard refreshes:

    SELECT time_bucket('1 hour', time) AS bucket, device_id, AVG(value) AS avg_value FROM device_readings WHERE time > now() - INTERVAL '30 days' GROUP BY device_id, bucket ORDER BY bucket DESC;

    At high data volumes, that scan competes with live writes and degrades query latency for both analytical and transactional queries.

    TimescaleDB's continuous aggregates maintain an incrementally updated materialized view. Instead of rescanning the full dataset on each query, the engine tracks which time buckets have received new data and refreshes only those. For an hourly view over 30 days of data (720 hourly buckets), a new insert updates at most one or two buckets. The other 718+ hours of pre-computed results are served directly from the materialized layer.

    The DDL and refresh policy for the device readings example:

    -- Create a continuous aggregate: hourly stats per device -- The WITH (timescaledb.continuous) clause enables incremental refresh -- materialized_only = false adds not-yet-materialized recent rows at query time -- (real-time aggregation, off by default since TimescaleDB 2.13) -- GROUP BY must include a time_bucket() expression on the hypertable's time column CREATE MATERIALIZED VIEW hourly_device_stats WITH (timescaledb.continuous, timescaledb.materialized_only = false) AS SELECT device_id, time_bucket('1 hour', time) AS bucket, AVG(value) AS avg_value, MIN(value) AS min_value, MAX(value) AS max_value, COUNT(*) AS reading_count FROM device_readings GROUP BY device_id, bucket; -- Set an automatic refresh policy -- start_offset: how far back to refresh (catches late-arriving data) -- end_offset: leave the most recent 1 hour to the real-time layer (materialized_only = false) -- schedule_interval: how often the background refresh runs SELECT add_continuous_aggregate_policy( 'hourly_device_stats', start_offset => INTERVAL '3 hours', end_offset => INTERVAL '1 hour', schedule_interval => INTERVAL '1 hour' ); -- Query the continuous aggregate: same SQL, dramatically faster SELECT device_id, bucket, avg_value, reading_count FROM hourly_device_stats WHERE bucket > now() - INTERVAL '7 days' ORDER BY device_id, bucket DESC;

    This allows a PostgreSQL database to function as an HTAP (Hybrid Transactional/Analytical Processing) system. OLTP writes feed directly into pre-computed analytical views, with no ETL pipeline, no separate analytical store, and no synchronization lag for recent data. See the continuous aggregates documentation for hierarchical aggregates (building aggregates on top of other aggregates) and Continuous Aggregates, Incremental Materialized Views for Time-Series Data for production patterns.

    Hypercore and hybrid row-columnar storage for HTAP workloads

    Tiger Data's Hypercore is a hybrid row-columnar storage engine built into TimescaleDB. It stores data in different physical formats depending on its age and access pattern. Recent (hot) data stays in standard PostgreSQL row format for fast OLTP writes and point lookups, while older (cold) data moves automatically to a columnar format optimized for analytical scan performance and compression.

    The storage transition happens at the chunk level. A hypertable chunk covering the last 7 days stores data in row format, giving fast inserts, fast point reads, and full mutability. Once that chunk ages past the configured threshold, Hypercore converts it to columnar format, cutting storage by up to 98%. The conversion is transparent, so standard SQL queries work against both formats without modification. INSERT, UPDATE, DELETE, and UPSERT operations all work on compressed columnar data, preserving full ACID guarantees.

    A common production pattern for teams that need both OLTP and analytical performance is PostgreSQL for transactions plus ClickHouse for analytics, connected by a CDC (Change Data Capture) pipeline. That's a reasonable architecture for high-analytical-query-volume workloads where the data being analyzed is mostly non-time-ordered.

    For workloads where the OLTP data is itself the time-series data (IoT ingestion, financial transactions, operational metrics), Hypercore removes the need for that split architecture. Recent data stays in row format for transactional correctness, while historical data moves to columnar format for analytical query performance. Both formats are queryable with the same SQL, from the same database, with no replication lag between the transactional source of truth and the analytical view.

    In many time-series OLTP workloads, this tends to reduce infrastructure complexity (no CDC pipeline to maintain, no schema synchronization between two systems, no consistency lag), at some cost to analytical query performance for high-cardinality heterogeneous queries, where a dedicated columnar engine like ClickHouse has more tuning surface. The right trade-off depends on the specific workload. 

    For the full architecture detail on Hypercore's vectorized execution, chunk skipping, and sparse indexes, see Hypercore, A Hybrid Row-Columnar Storage Engine for Real-Time Analytics.

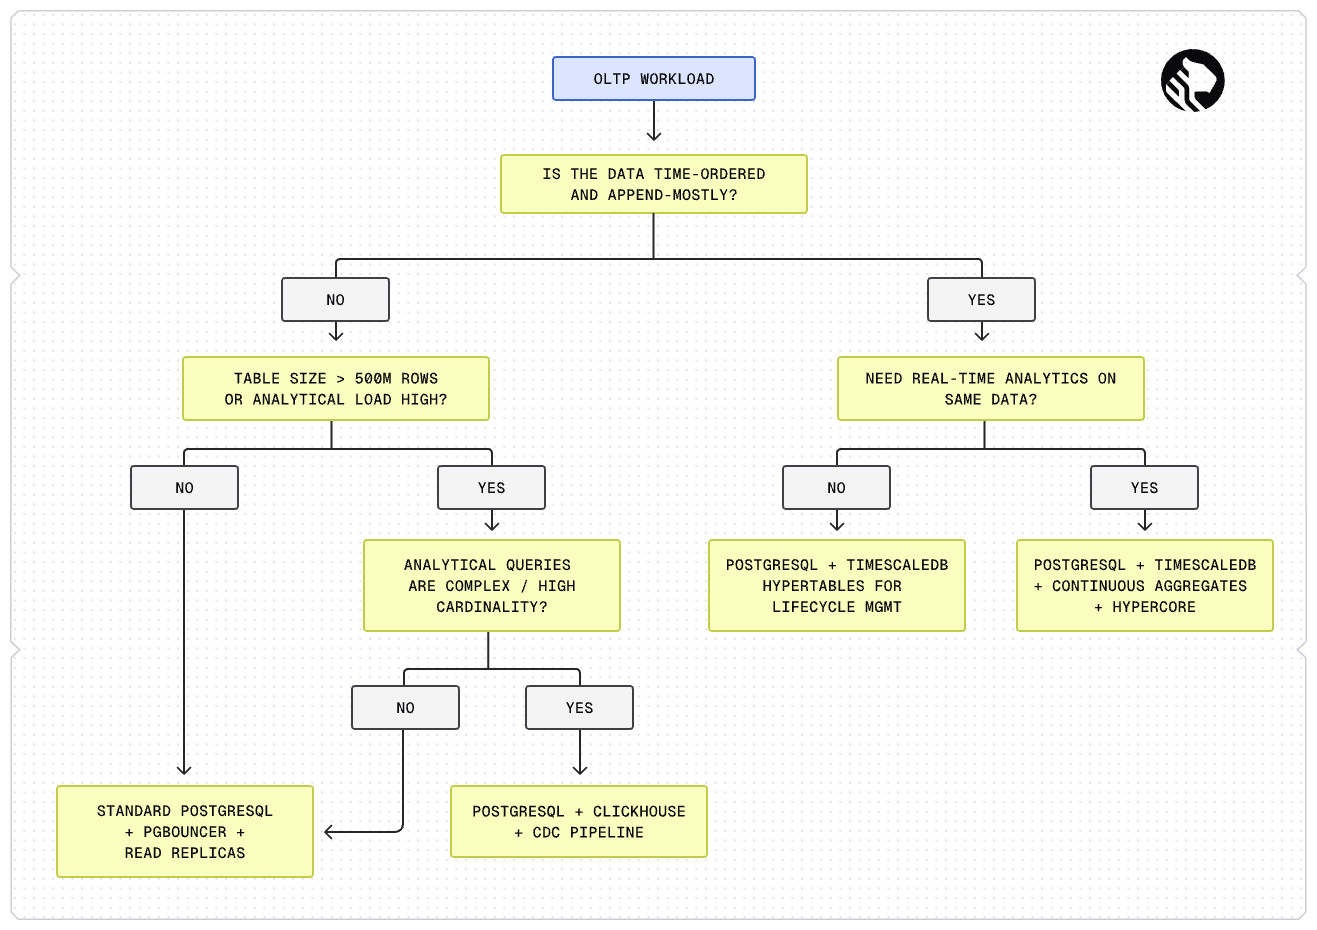
    OLTP architecture decision framework

    No single architecture fits every OLTP workload. The right choice depends on write volume, analytical query load, whether the data has a dominant time dimension, and how much operational complexity the team can sustain.

    Choose standard PostgreSQL OLTP when:

    • Your workload is a traditional application backend (user records, content management, SaaS operational data, e-commerce order management), where analytical queries are secondary and batch reporting is enough.

    • Your data doesn't have a dominant time dimension. Rows get updated in place frequently (account balances, user preferences, status flags) rather than mostly appended as new timestamped events.

    • You need maximum compatibility with the PostgreSQL ecosystem (ORMs, migration frameworks, existing DBA expertise) without adding an extension layer.

    • Your table sizes are manageable (tens to hundreds of millions of rows), and autovacuum is keeping pace without heavy tuning.

    Recommendation. Use PostgreSQL directly. Tune shared_buffers, work_mem, max_connections, and autovacuum settings per the configuration table above. Add PgBouncer at roughly 200+ concurrent connections. Monitor vacuum lag and table bloat with pg_stat_user_tables.

    Choose PostgreSQL + TimescaleDB (Tiger Cloud) when:

    • Your OLTP workload produces time-ordered, append-mostly data at high velocity, including IoT sensor readings, financial transaction streams, operational event logs, and metrics pipelines.

    • You want real-time analytical queries over that OLTP data without building and running a separate analytical store or CDC pipeline.

    • Your table sizes are reaching hundreds of millions to billions of rows, and managing autovacuum is becoming a real operational burden.

    • You need automated data lifecycle management, including chunk compression for historical data, retention policies that drop old partitions, and tiered storage for petabyte-scale history.

    Recommendation. Start with TimescaleDB's hypertable on your primary time-dimension table. Add continuous aggregates for the analytical queries you currently run as expensive aggregation queries on raw data. Consider Tiger Cloud for managed PostgreSQL + TimescaleDB with automated tuning and tiered object storage.

    Choose PostgreSQL + a separate OLAP system when

    • Your analytical query load is high (hundreds of complex aggregations per second), the data being analyzed is mostly non-time-ordered, or the analytical queries need capabilities PostgreSQL handles poorly at scale (wide aggregations, cube/rollup operations over heterogeneous dimensions).

    • A common pattern for this use case is PostgreSQL for the OLTP primary plus ClickHouse for the analytical layer, with CDC-based replication between them. This architecture fits workloads where operational data and analytical data are genuinely separate concerns with different access patterns.

    • The trade-off is added operational complexity (CDC pipeline management, schema synchronization, replication lag), though the pattern delivers strong analytical query performance for high-cardinality, heterogeneous data that doesn't fit time-series patterns.

    See How to Choose an OLAP Database for a structured comparison of OLAP database options.

    image

    Choosing the right PostgreSQL OLTP architecture

    PostgreSQL's production OLTP story comes down to deliberate configuration over out-of-the-box defaults. The engine's MVCC concurrency model, WAL-based durability, and native ACID compliance make it a strong foundation for transactional workloads at any scale. The operational costs (autovacuum tuning, connection pooling, write amplification management) are real, but they're well understood, with established tooling and community patterns for each.

    The architecture decision comes down to one question about your data's shape. If your OLTP data is time-ordered and append-mostly at high velocity, TimescaleDB's hypertables, continuous aggregates, and Hypercore storage extend PostgreSQL into territory that would otherwise need a separate analytical system and a CDC pipeline to connect it. If your workload is traditional relational OLTP with frequent in-place updates and modest analytical needs, standard PostgreSQL with PgBouncer and read replicas is the right fit. OpenAI's published architecture backs this up too: for read-heavy workloads, a single well-configured primary can scale further than most teams expect.

    Start with the configuration baseline in this guide, instrument pg_stat_user_tables for vacuum lag and bloat, and add PgBouncer before you hit 200 concurrent connections. Those three steps resolve most PostgreSQL OLTP scaling problems before they turn into incidents.

    For managed PostgreSQL and TimescaleDB with automated tuning, tiered storage, and built-in PgBouncer, Tiger Cloud handles the operational layer so your team can focus on the workload.

    FAQ

    Is PostgreSQL good for OLTP workloads?

    Yes. PostgreSQL is well-suited for OLTP workloads and is the most widely used relational database among professional developers, confirmed by the 2025 Stack Overflow Developer Survey. Its MVCC-based concurrency model allows many simultaneous readers and writers without read locks, and ACID compliance is native. At scale, PostgreSQL requires a connection pooler (PgBouncer is the standard choice) to avoid process-per-connection overhead, and autovacuum needs active tuning for high-write-rate workloads. Both requirements are manageable with proper configuration.

    Is PostgreSQL an OLTP or OLAP database?

    PostgreSQL is primarily designed for OLTP. It is a row-oriented, ACID-compliant transactional database. It can run analytical queries directly, but without extensions it lacks the columnar storage and vectorized execution that purpose-built OLAP engines use for large-scale analytical performance. With TimescaleDB installed, PostgreSQL gains columnar compression via Hypercore and continuous aggregates for real-time materialized OLAP queries, extending it into hybrid OLTP/OLAP territory for time-series-native workloads.

    How does PostgreSQL handle concurrent transactions?

    PostgreSQL uses Multi-Version Concurrency Control (MVCC). Each query works from a consistent snapshot of the database, taken when the query starts (or when the transaction starts, under Repeatable Read and Serializable). Writers create new row versions rather than overwriting in place, so reads do not block writes and writes do not block reads. When two transactions update the same row, the second waits for the first to finish. Under Read Committed (the default), it then re-checks the row and proceeds. Under Repeatable Read and Serializable, it receives a serialization error and must retry.

    What is the connection limit for PostgreSQL OLTP and how do you manage it?

    PostgreSQL spawns one OS process per client connection. At high connection counts, memory and context-switching overhead degrades throughput, with the practical ceiling for direct connections at roughly 200-300 before overhead becomes measurable. The standard solution is PgBouncer in transaction pooling mode, which multiplexes thousands of application connections onto a smaller pool of actual PostgreSQL server connections. OpenAI's published architecture for ChatGPT runs PgBouncer as a proxy layer in front of its read replicas, as one part of a broader set of techniques, alongside caching, rate limiting, and read replicas, that let a single PostgreSQL primary serve hundreds of millions of users.

    How do you scale PostgreSQL for high-throughput OLTP workloads?

    The main levers are: (1) connection pooling with PgBouncer to avoid process-per-connection overhead; (2) read replicas to route read traffic away from the primary; (3) parameter tuning including shared_buffers, work_mem, and autovacuum settings for OLTP workloads; (4) table partitioning for large tables via native range partitioning or TimescaleDB hypertables for time-ordered data; and (5) index optimization including covering indexes, partial indexes, and regular maintenance to reduce bloat.

    When should I use TimescaleDB for OLTP workloads?

    TimescaleDB adds the most value when your OLTP data is time-ordered (rows have timestamps and are predominantly appended rather than updated in place), your tables are reaching hundreds of millions or billions of rows, and you want real-time analytics over the same data without a separate analytical store or ETL pipeline. For standard relational OLTP workloads with frequent in-place updates and modest analytical needs, standard PostgreSQL is sufficient. TimescaleDB's core benefits are most pronounced for IoT ingestion, financial transaction streams, operational event logging, and metrics pipelines at scale.

    What is HTAP and does PostgreSQL support it?

    HTAP (Hybrid Transactional/Analytical Processing) describes a database architecture that handles both OLTP writes and analytical queries on the same data without requiring a separate analytical store or ETL pipeline. Standard PostgreSQL can run both types of queries but is not optimized for high-throughput analytical workloads on very large tables. With TimescaleDB, PostgreSQL gains continuous aggregates (incrementally maintained materialized views that serve pre-computed analytical results in real time) and Hypercore (hybrid row-columnar storage for historical data chunks), together delivering HTAP-style capabilities for time-series-native workloads.

    What are the main OLTP scaling pain points in PostgreSQL?

    The top three: (1) autovacuum lag, where MVCC dead-tuple accumulation under heavy update/delete loads can outpace default autovacuum settings, leading to table bloat and query planner degradation; (2) connection overhead, where the process-per-connection model requires PgBouncer at high concurrency; and (3) write amplification, where MVCC writes a full new row version per UPDATE plus a WAL record, creating more disk I/O than in-place update engines under update-heavy workloads. Each is solvable with proper tuning and tooling, but all three require deliberate attention as write rates climb.