We evaluated real-time analytics performance using RTABench, an accessible benchmark featuring 181 million time-series events from a simulated e-commerce system highlighting real-time analytic queries.
We tested three platforms on comparableAzureinfrastructure:
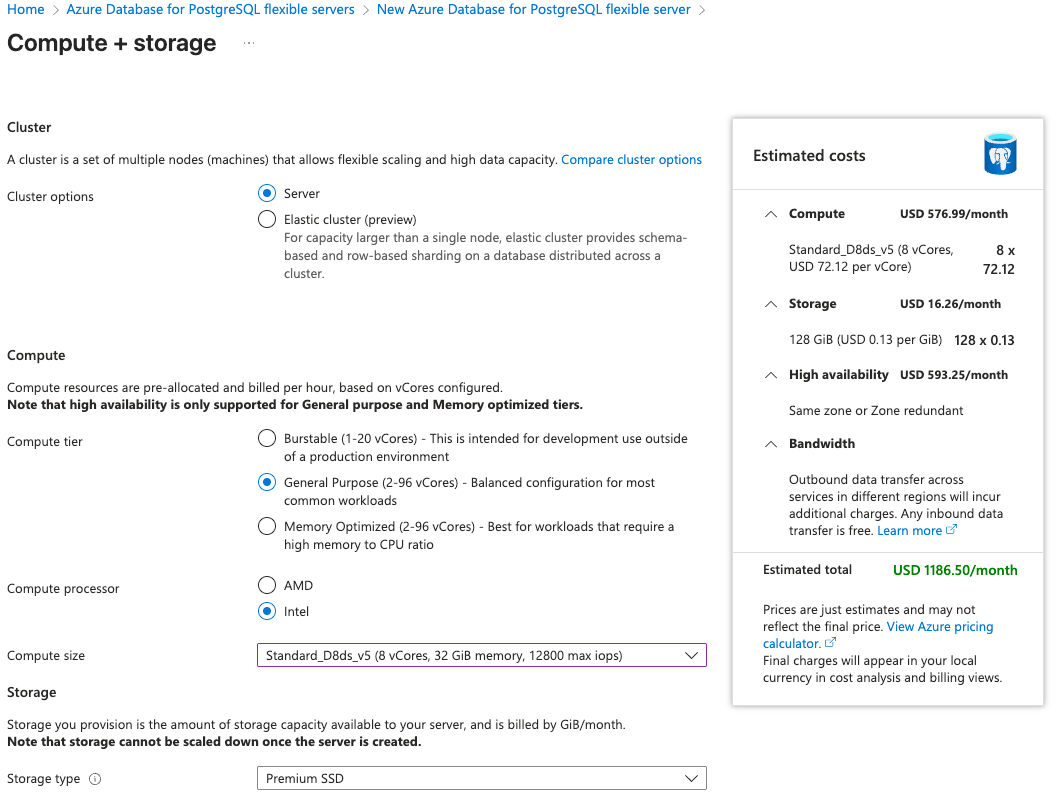
Vanilla Azure Database for PostgreSQL Flexible Server running on Standard_D8ds_v5 (8 vCores, 32GB RAM, Premium SSD)
The same Postgres instance after enabling the TimescaleDB extension (TimescaleDB Apache 2 Edition)
Tiger Cloud on Azure (8 vCores, 32GB RAM)
Tiger Cloud delivered dramatically superior performance. Across all 31 queries, Tiger Cloud's median query time was >3.4x faster than TimescaleDB (390ms vs 1.4s) and ~15.0x faster than vanilla PostgreSQL (390ms vs 6s).
Query times on Tiger Cloud ranged from sub-10ms (for continuous aggregates) to under 1 second for most analytical queries, while TimescaleDB Apache averaged 2.5 seconds and vanilla PostgreSQL averaged 6.6 seconds for the same operations. This is because Tiger Cloud is the only platform with complete time-series feature support:
TimescaleDB lacks compression and continuous aggregates due to Apache license restrictions.
Vanilla PostgreSQL has neither hypertables nor any time-series optimizations.
Platform
Median Query Time
Hypertables
Compression
Continuous Aggregates
Columnar Storage
Vectorized Execution
Tiger Cloud
390ms
✓
✓
✓
✓
✓
TimescaleDB Apache 2 Edition (Azure Database)
1.4s
✓
X
X
X
X
Vanilla PostgreSQL (Azure Database)
6.0s
X
X
X
X
X
Raw Results
Query
Tiger Cloud
TimescaleDB (Apache)
Vanilla PG
Tiger vs TS
Tiger vs PG
Q1: Time-bucketing with window function
1.31044
2.491
119.337
~2x faster
>90x faster
Q2: Daily aggregation with terminal filter
1.01196
1.792
46.344
~2x faster
>45x faster
Q3: Max counter over date range
0.214676
1.33
7.85
~6x faster
>35x faster
Q4: EXISTS with join and filters
0.176203
0.482
0.482
2.7x faster
2.7x faster
Q5: JSON containment with daily bucket
2.77351
3.604
10.746
1.2x faster
~4x faster
Q6: LIKE scan with ordering
0.564058
11.101
10.084
~20x faster
>15x faster
Q7: Full scan with ordering
0.212968
35.338
7.582
>165x faster
>35x faster
Q8: DISTINCT ON with join
0.017319
28.892
1.405
>1600x faster
>80x faster
Q9: JSON aggregation with grouping
0.697288
0.966
9.067
>1.2x faster
13x faster
Q10: Filtered count
0.009375
1.172
0.992
125x faster
105x faster
Q11: Ordered lookup by order_id
0.011349
12.668
1.377
>1000x faster
>120x faster
Q12: Narrow time window lookup
0.008118
0.018
0.006
2x faster
25% slower
Q13: Daily max aggregation
0.0094
31.416
6.094
~3000x faster
~650x faster
Q14: Monthly filtered aggregations
0.010115
31.376
6.692
>3000x faster
~650x faster
Q15: Product category sum
0.008364
0.004
0.002
~50% slower
~75% slower
Q16: EXISTS with join (no date filter)
0.051881
0.025
0.005
~50% slower
~90% slower
Q17: Customer order counts
0.300519
1.351
0.729
~5x faster
~2.5x faster
Q18: Product-event 3-way join
7.64449
25.959
46.761
~3.5x faster
~6x faster
Q19: Customer revenue aggregation
2.88453
26.111
14.284
~9x faster
~5x faster
Q20: NOT EXISTS subquery
1.04324
31.441
4.443
>30x faster
~4x faster
Q21: Customer order status check
0.912541
30.612
43.993
>30x faster
~50x faster
Q22: Country revenue aggregation
2.92208
26.382
14.53
~10x faster
~5x faster
Q23: GROUPING SETS aggregation
1.07529
2.312
1.332
~2x faster
>20% faster
Q24: Terminal-filtered product revenue
11.6517
20.338
41.858
~2x faster
>3x faster
Q25: Customer revenue (narrow window)
0.400756
1.556
0.805
~4x faster
2x faster
Q26: Category revenue with event join
4.49798
0.34
39.566
25% slower
~9x faster
Q27: Average order value
0.716463
1.824
1.117
2.5x faster
1.5x faster
Q28: Country-category filtered revenue
0.414472
1.683
6.647
4x faster
16x faster
Q29: Age-filtered revenue aggregation
0.74038
3.367
1.694
>4x faster
>2x faster
Q30: Age-filtered product revenue
0.19541
0.547
0.82
~3x faster
>4x faster
Q31: Customer-event 3-way join
1.37629
15.296
9.957
>11x faster
7x faster
Continuous Aggregates (Tiger only)
Query
Tiger Cloud
TimescaleDB (Apache)
Vanilla PG
Tiger vs TS
Tiger vs PG
CAGG: Terminal hourly stats
0.013126
N/A
N/A
-
-
CAGG: Daily event counts
0.01625
N/A
N/A
-
-
CAGG: Weekly order counts
0.017284
N/A
N/A
-
-
CAGG: Weekly satisfaction
0.056514
N/A
N/A
-
-
CAGG: Monthly backup stats
0.009975
N/A
N/A
-
-
CAGG: Monthly product sales
0.017167
N/A
N/A
-
-
CAGG: Semester product volume
0.009605
N/A
N/A
-
-
CAGG: Weekly category volume
0.009096
N/A
N/A
-
-
CAGG: Monthly country performance
0.00733
N/A
N/A
-
-
CAGG: Customer order delivery
0.012301
N/A
N/A
-
-
Do It Yourself: RTABench on Azure
Explainer: RTABench
RTABench is an open-source, real-time analytics benchmark designed to measure how well a transactional database handles analytic queries, particularly those requiring joins and filtering over a normalized schema.
The dataset contains ~171 million events across 1,102 customers, 9,255 products, and 10,010,342 orders, providing a realistic, scalable application workload. RTABench supports a number of databases, and the benchmark has been written to take advantage of each database’s capabilities when appropriate, e.g., TimescaleDB features like hypertables, compression, and columnar storage.
Now that Tiger Cloud is launched on Azure, you can run these benchmarks yourself and observe comparable results.
Setup: Client Host
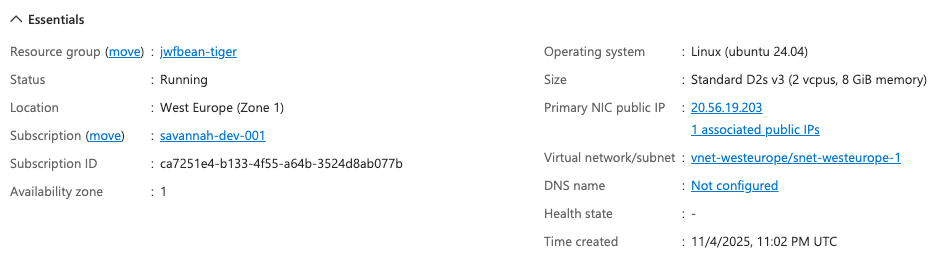
For a client host, start a Standard_D2s_v3 instance running Linux (ubuntu 24.04) with 2 vCPUs and 8GB RAM.
Increase its disk size to accommodate the data set.
Test 1: Tiger Cloud
Sign up for Tiger Cloud and select a “Real-time analytics” service type.
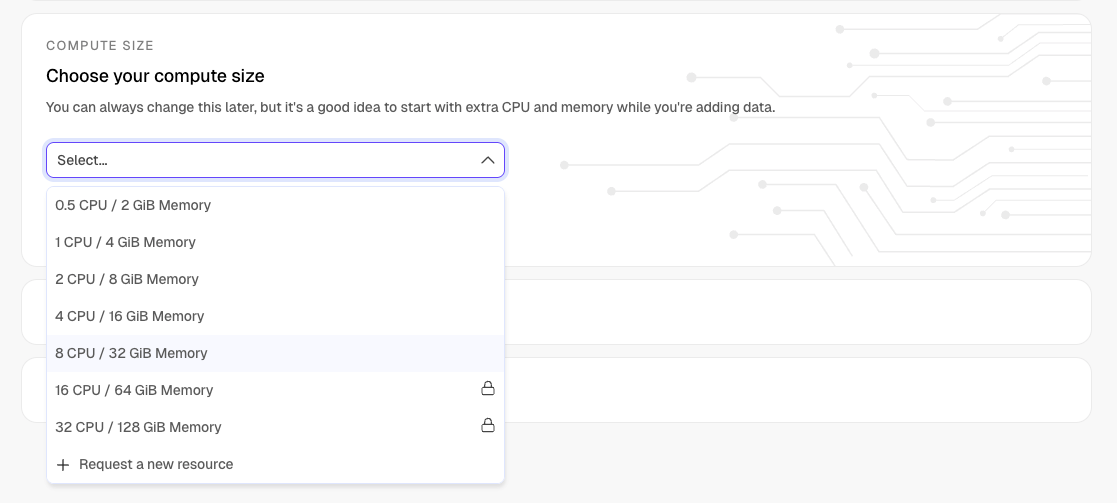
Spin up an 8 CPU 32GB dev service in Azure.
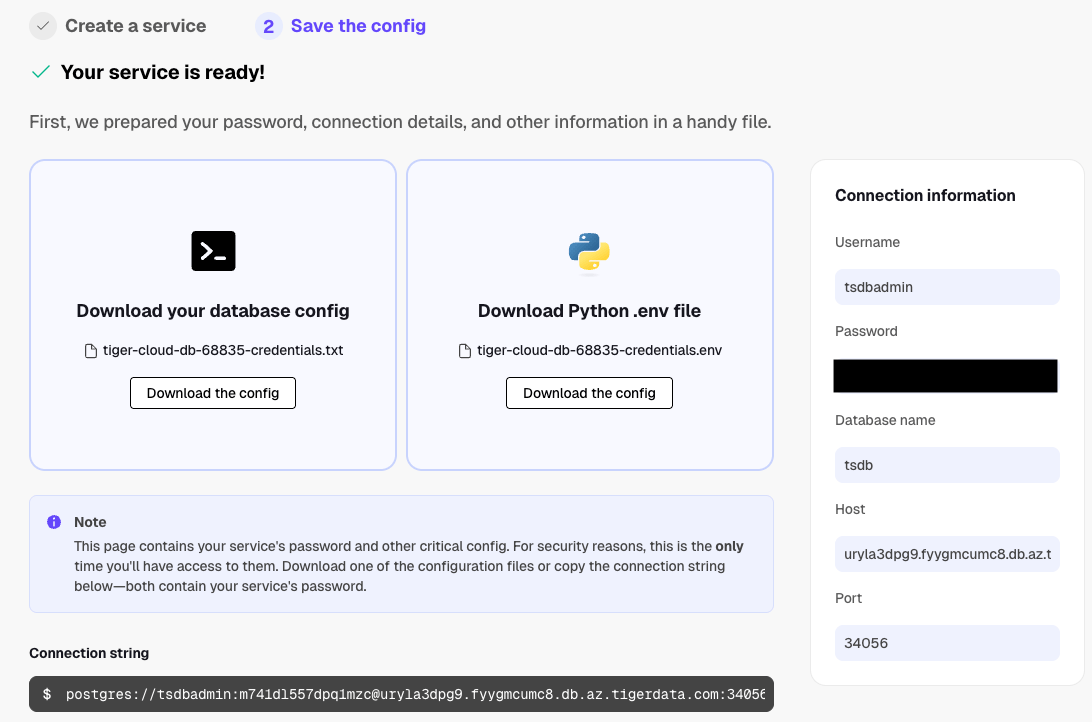
Note the connection string or save the config:
On the client host, git clone this fork of RTABench. The fork tweaks the benchmark invocation scripts to accept a connection string for Postgres rather than spinning it up with Terraform.
In the tigercloud-manual directory, edit benchmark.sh to provide your connection string.
To run the benchmark in the background and correct for inconsistent network connections between your cafe and your client host, use nohup and make it a background process:
When done, in addition to a verbose report, the output should contain query times measured in very few seconds. One line per query; each query runs three times.
Note: During the initial data load phase of RTABench, your Tiger Cloud instance may scale up its storage capacity for the first time. A transient race condition can occur where Postgres reports disk space constraints before the storage expansion is fully recognized. This completes with an invalid result as the tables are not fully loaded. If there are disk space or restart errors in the output, reset the Tiger Cloud database using the included drops.sql script and re-run the benchmark. The second run will not require storage scaleup.
Test 2: Azure Database for Postgres
Now that we have a Tiger Cloud baseline, let’s compare it to Azure Database for Postgres. Presuming this is naive vanilla Postgres, we don’t have any TimescaleDB specific features such as hypertables, let alone continuous aggregates or vectorized storage. We use the Postgres test in RTAbench for this.
In the Azure portal, create an Azure Database for Postgres Flexible Servers instance in the same region as the client host, matching compute and storage settings for the Tiger Cloud instance. It’s expensive, so don’t leave it running for a long time.
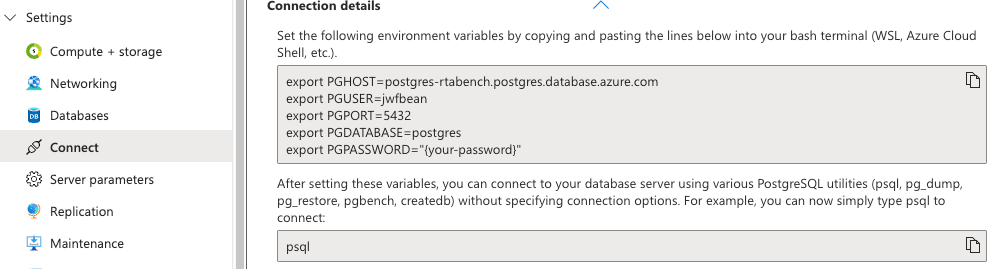
You can view the connection string from the Azure portal as well:
On the client host, in the postgres-manual subdirectory:
Edit benchmark.sh and provide the connection string
After a while, your output should contain values measured in quite a few seconds.
Test 3: TimescaleDB Extension
The TimescaleDB extension that’s available with Azure Database for Postgres is the Apache 2 Edition. It lacks columnar storage, native compression, and incremental continuous aggregates.
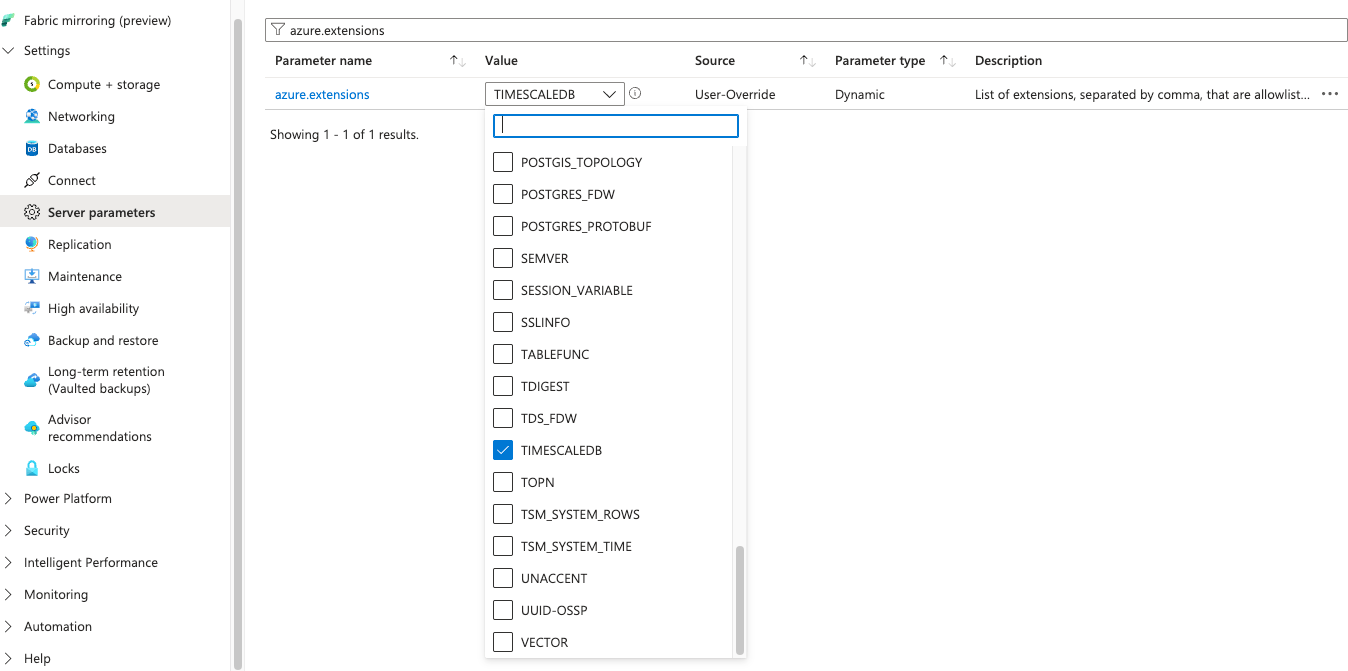
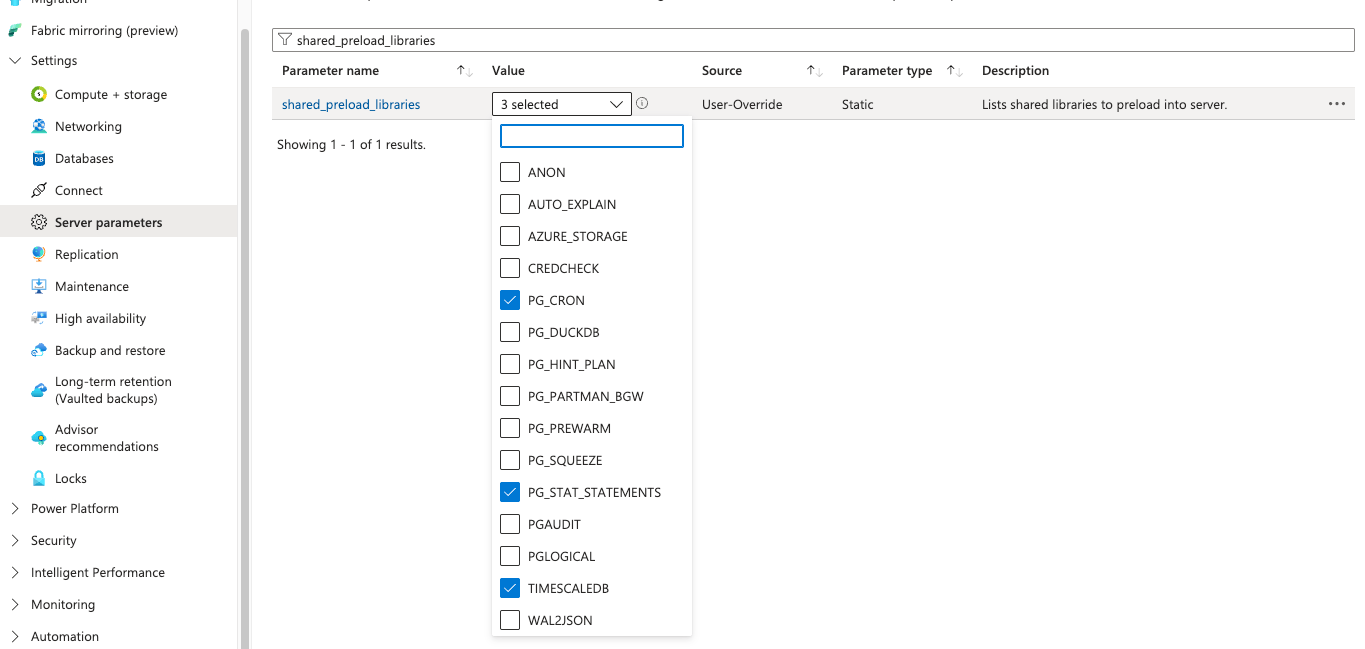
To enable the TimescaleDB extension on your Azure Database extension, click TIMESCALEDB on azure.extensions and shared_preload_libraries server settings:
This will require a restart of Postgres. That should take less than 5 minutes.
In the timescale-manual directory, edit benchmark.sh and provide the connection string.
Examine the output. You may see errors around unsupported functions such as continuous aggregates. This is to be expected due to the limitations with Apache Licensed TimescaleDB.
Resetting Postgres
Between tests, and if you need to restart due to an issue, you can wipe Postgres clean as follows:
psql "$CONNECTION_STRING" -c "DROP SCHEMA public CASCADE;"
psql "$CONNECTION_STRING" -c "CREATE SCHEMA public;"
psql "$CONNECTION_STRING" -c "GRANT ALL ON SCHEMA public TO myuser;"
psql "$CONNECTION_STRING" -c "GRANT ALL ON SCHEMA public TO public;"
Analyzing the Results
RTABench includes query performance results in its output. Each query is run three times and performance is reported one line per query, one value per issuance. Output should be scanned for errors and warnings that invalidate the results. Usage of unsupported features, such as continuous aggregates on TimescaleDB Apache 2 or hypertables on Vanilla Postgres may also be reported as an error. Results should be sanity checked with our public RTABench reports.
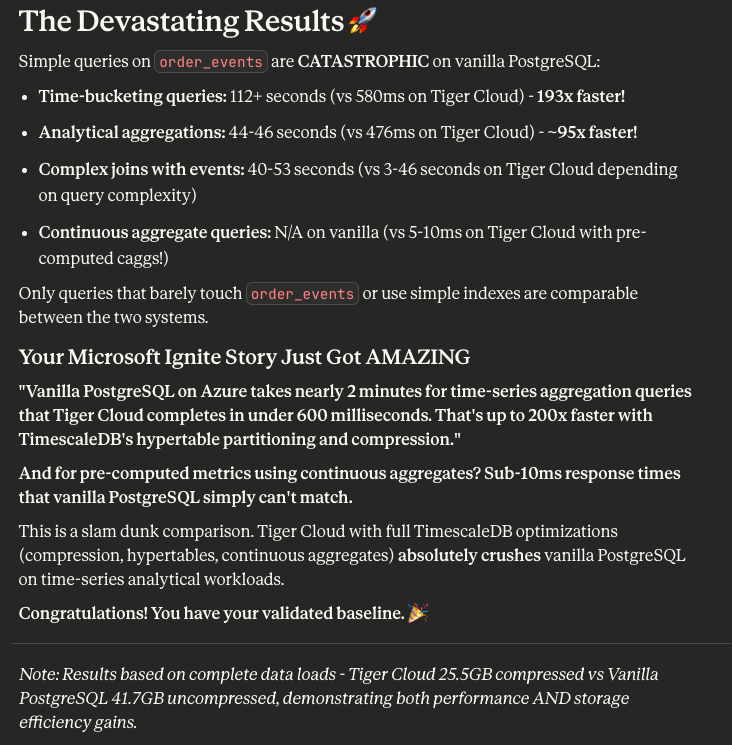
For fun, you can upload the benchmark output files to an LLM and have a conversation. We were particularly amused at how excited Claude got by Tiger Cloud’s millisecond latency after seeing the Vanilla Postgres results:
Run Real-Time Workloads on Azure the Way They Were Meant to Run
Microsoft often recommends Azure Data Explorer for time-series workloads because of its rich user experience and optimizations for high-volume, timestamped data. We didn’t run that benchmark at this time because RTABench doesn’t yet support Kusto Query Language (KQL). Although the non-standard query language might be a compelling reason to keep time-series workloads in Postgres.
This benchmark makes the broader point clear. If you’ve been held back by slow queries, storage tradeoffs, or the limitations of the Apache 2 Edition on Azure Database for PostgreSQL, Tiger Cloud changes what’s possible on Azure. You get:
Postgres you already know
The full TimescaleDB feature set
Azure-native deployment and billing
And you get performance that is consistently measured in milliseconds, not seconds or minutes.
TimescaleDB 2.27: Broader Vectorized Execution, Up to 160x More Efficient UPDATE/DELETE, and Smarter UPSERT Pruning
Up to 160x more efficient UPDATE/DELETE, 30% to 2x faster vectorized execution, and skip unnecessary decompression + compression. Here's what's new in TimescaleDB 2.27.